Sume Avatar 1.0
Sume Avatar 1.0 by API: reusable avatars, talking video from a script, multi-scene and two-speaker videos, previews, B-roll, and Face Swap (Beta).
Start with Introducing Sume Avatar 1.0
Avatar explainer: product_image or a photo scene, what each does
In Sume Avatar 1.0, product_image adds $0.01, $0.013 or $0.03 a second by tier; a photo scene sets the background. When to send which for a product explainer.
Avatar video for a 4:5 feed: render 3:4, then crop to 0.9375 height
Sume Avatar 1.0 has no 4:5 ratio. Render 3:4, crop the height to 0.9375 with video filter for $0.02, and caption after the crop so nothing is cut off.
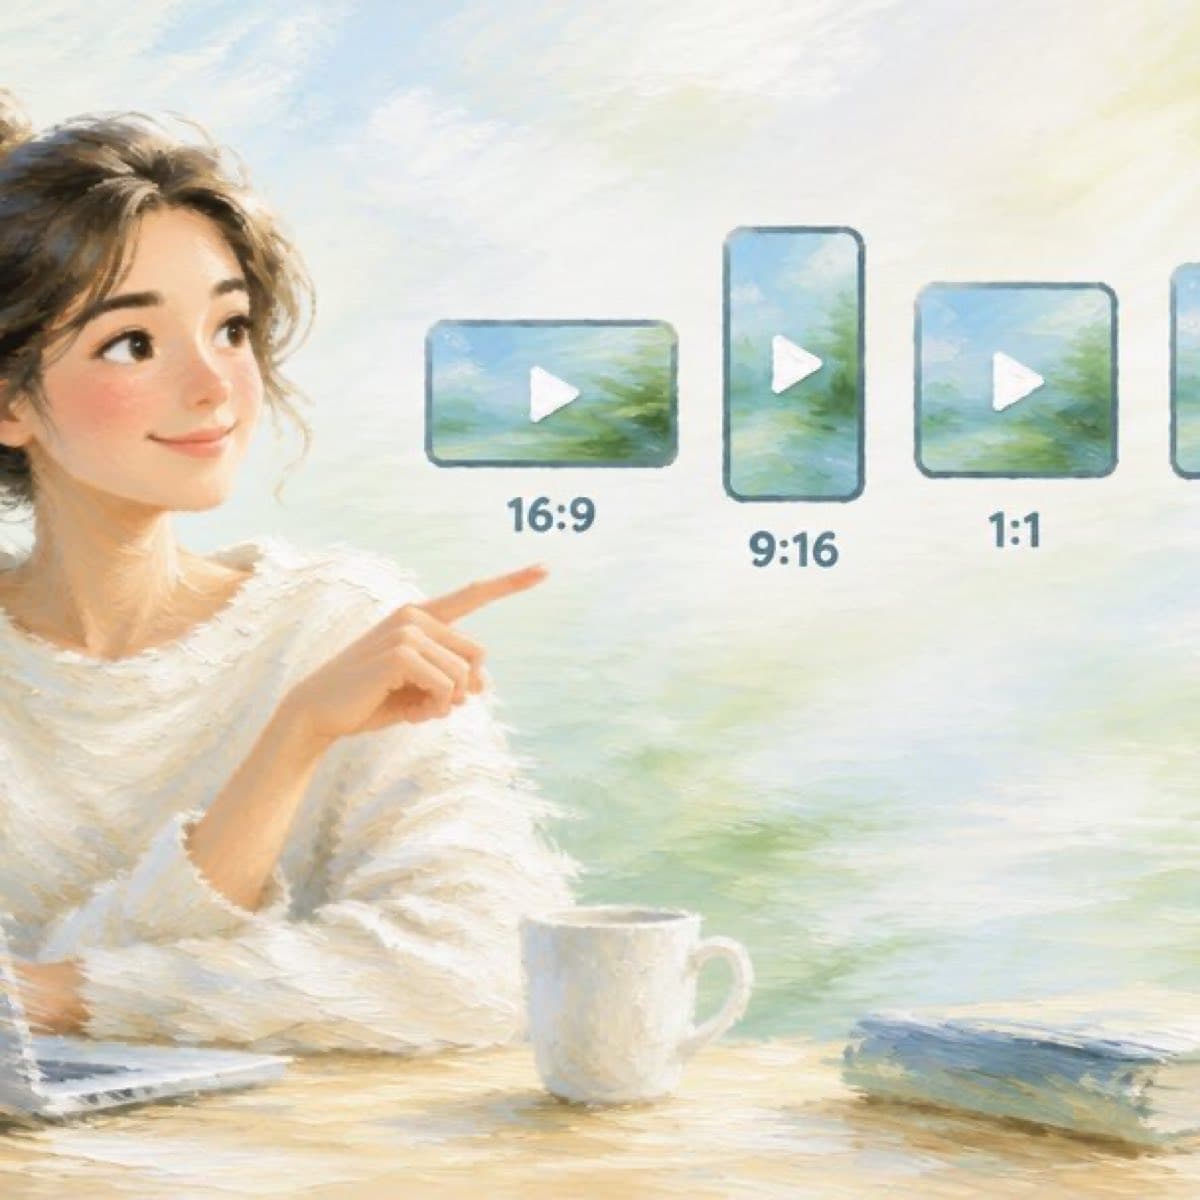
Avatar video ratio: five options for LinkedIn, Shorts and feeds
Sume Avatar 1.0 renders 1:1, 3:4, 9:16, 4:3 and 16:9 at 720p. Which ratio to pick for LinkedIn, Shorts, a feed post or a landing page, and what changes in cost.
Silence beat in an avatar video plan: 2 seconds with no words
Sume Avatar 1.0 multi-scene plans can include a silence beat. How to place a 2-second pause in a product reveal and what it adds at $0.258 a second.
A 20-second ad person swap: Recast fits, avatar face swap stops at 15
For a 20-second source clip, Sume's H3 Max Recast takes 5 to 30 seconds and 1 to 4 person photos; the Avatar Face Swap beta takes about 4 to 15 seconds.
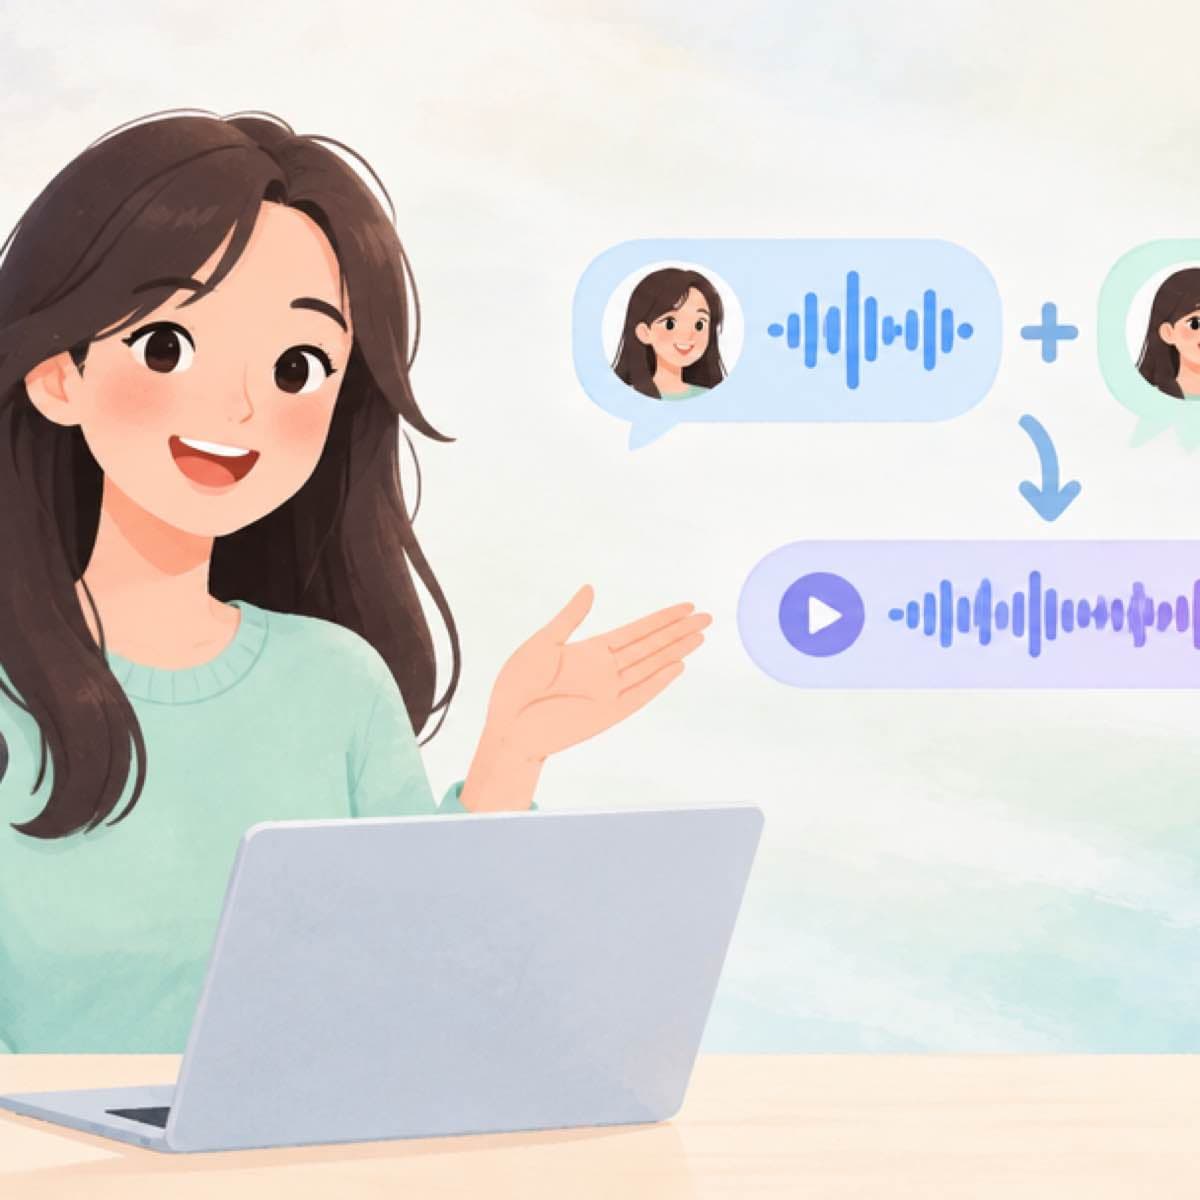
Lip-sync audio under 5 seconds: join two TTS lines with audio concat
MiniMax H3 Max lip-sync on Sume wants 5 to 14.8 seconds of audio. Join two short TTS lines with Timeline audio concat for $0.01 instead of padding.
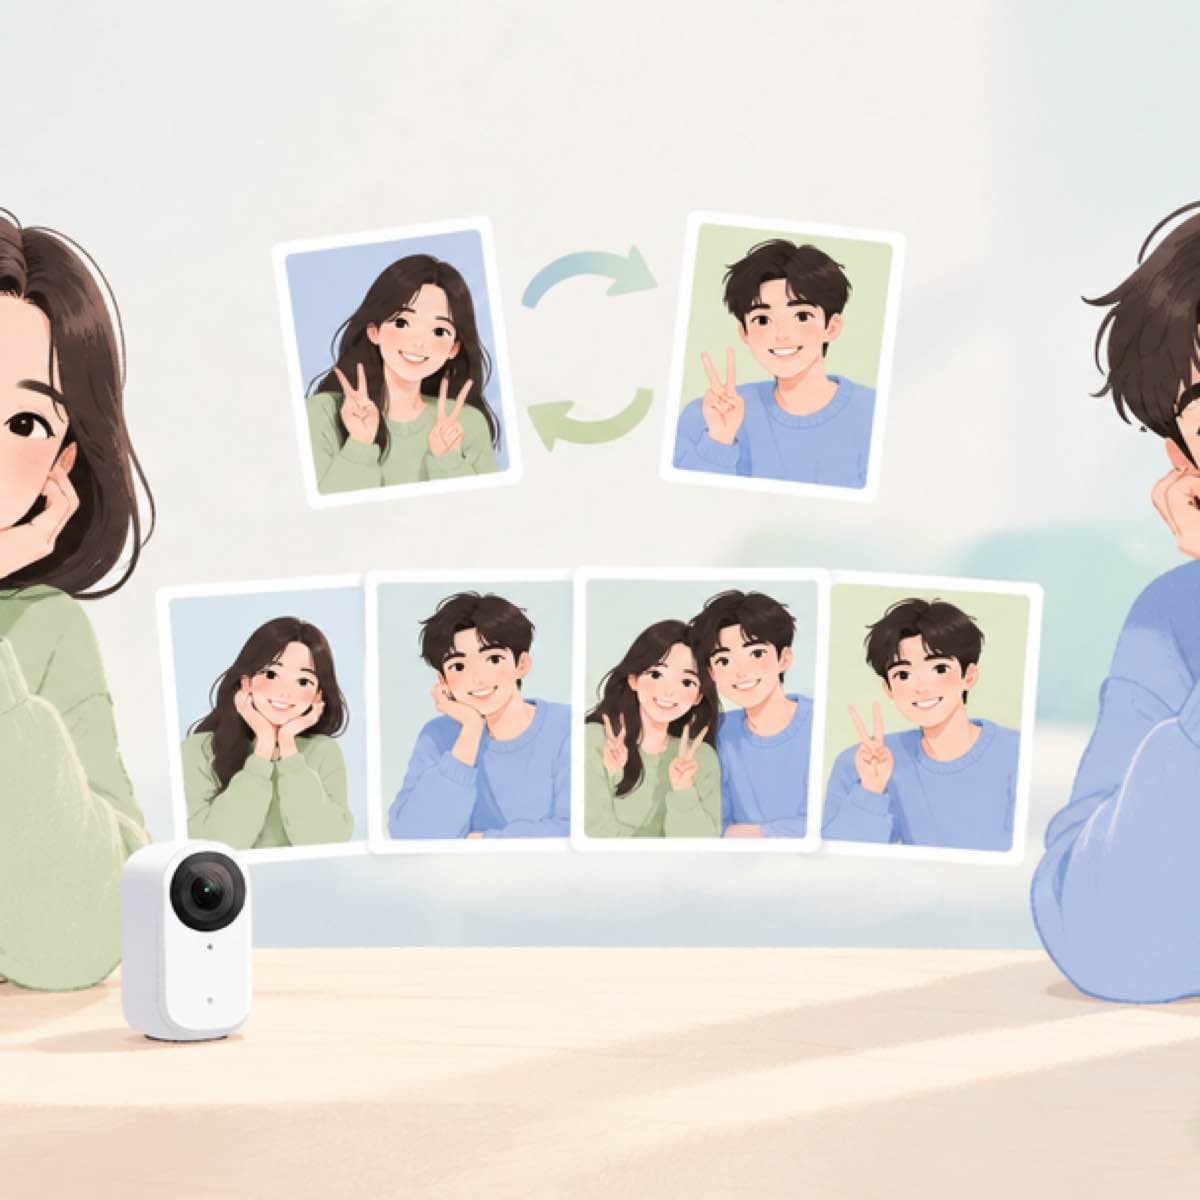
Swap two people in one clip: H3 Max Recast takes 1 to 4 photos
To change two people in one video, send one reference photo for each. Sume's H3 Max Recast takes 1 to 4 person photos and a 5 to 30 second source video.
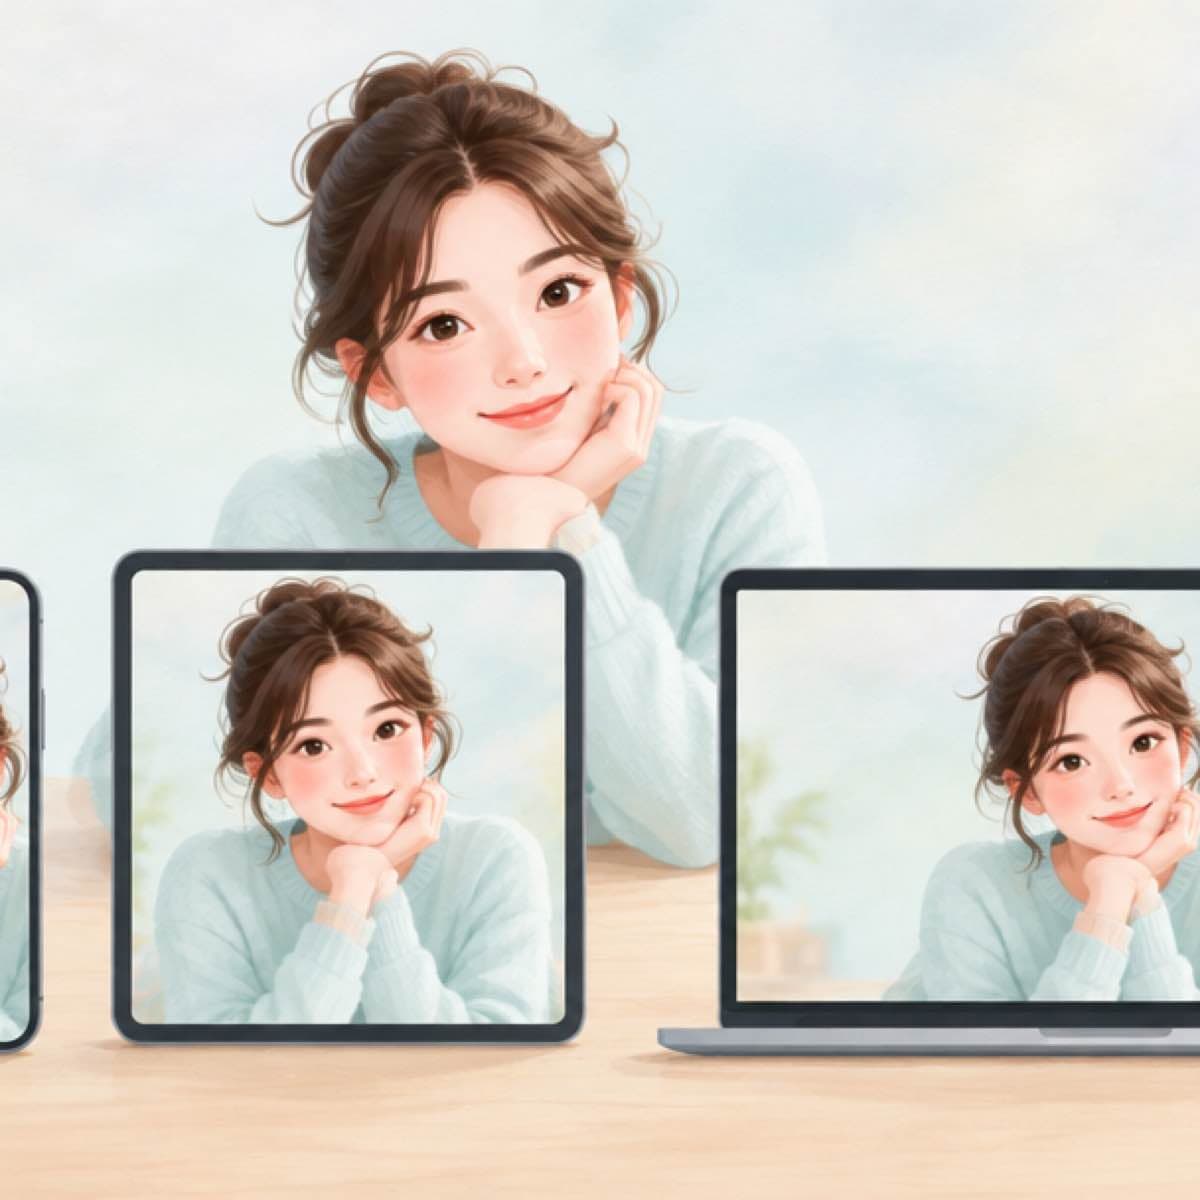
One avatar handle, three ratios: the same face in 9:16, 1:1, 16:9
Keep one AI presenter across Shorts, feed and webinar slots: reuse a single avatar_handle and change only aspect_ratio on each Sume talking-video call.
Bakery pre-order deadline: a 20-second avatar clip with the cake photo
A 20-second pre-order reminder with the cake photo as product_image costs about $3.88 on Standard, $5.16 on Plus or $11.60 on Max at Sume's rates.
Farmers market weekly update: a 25-second avatar clip, priced
A weekly 25-second avatar update for a market costs about $4.60 on Standard, $6.13 on Plus or $13.75 on Max at Sume's listed per-second rates.
Avatar script over 60 seconds: split it into two Avatar 1.0 jobs
Sume accepts avatar scripts that it estimates at 4 to 60 seconds. Longer scripts need to be shortened or split into jobs; here is how to split without a jump.
Wedding save-the-date: a 20-second avatar clip, cost by tier
A 20-second save-the-date spoken by an AI avatar costs about $3.68 on Standard, $4.90 on Plus or $11.00 on Max at Sume's listed per-second rates.
Gym class schedule change: a 20-second avatar video, priced
A 20-second avatar notice for a changed class time costs about $3.68 on Standard, $4.90 on Plus or $11.00 on Max at Sume's listed per-second rates.
AI avatar without a photo: Sume props input (age, sex, ethnicity)
No photo of your presenter? Sume creates an avatar from a text prompt or structured props such as age, sex and ethnicity. One POST, one flat creation price.
Korean talking avatar captions: black-outline or korean-ad, not slam
Korean script on a Sume avatar video with slam, punch or tiktok-green returns 400 caption_hangul_text_latin_style. Use black-outline or korean-ad.
Restaurant daily special: avatar clip with the dish as product image
A 15-second daily-special avatar clip with the dish photo as product_image costs about $2.91 on Standard, $3.87 on Plus or $8.70 on Max at Sume's rates.
HOA community notice: a 30-second avatar video for residents, priced
A 30-second avatar video for an HOA or building notice costs about $5.52 on Standard, $7.35 on Plus or $16.50 on Max at Sume's listed per-second rates.
Library story hour: an 18-second avatar announcement, priced
An 18-second avatar announcement for a library event costs about $3.31 on Standard, $4.41 on Plus or $9.90 on Max at Sume's listed per-second rates.
Griffin-Lite access form: what to prepare while you wait
Tavus gates Griffin-Lite behind a request form for trusted testers and lists no price. Prepare a use case and a disclosure plan, and render with Sume meanwhile.
School closure notice: a 15-second vertical avatar video, priced
A 15-second avatar closure notice for parents costs about $2.76 on Standard, $3.68 on Plus or $8.25 on Max at Sume's listed per-second rates.
Avatar clip under 4 seconds: add a silence beat or a longer line
Sume avatar scripts must plan to 4 seconds or more. For a one-liner, add a silence beat in video_inputs or lengthen the line instead of padding with filler.
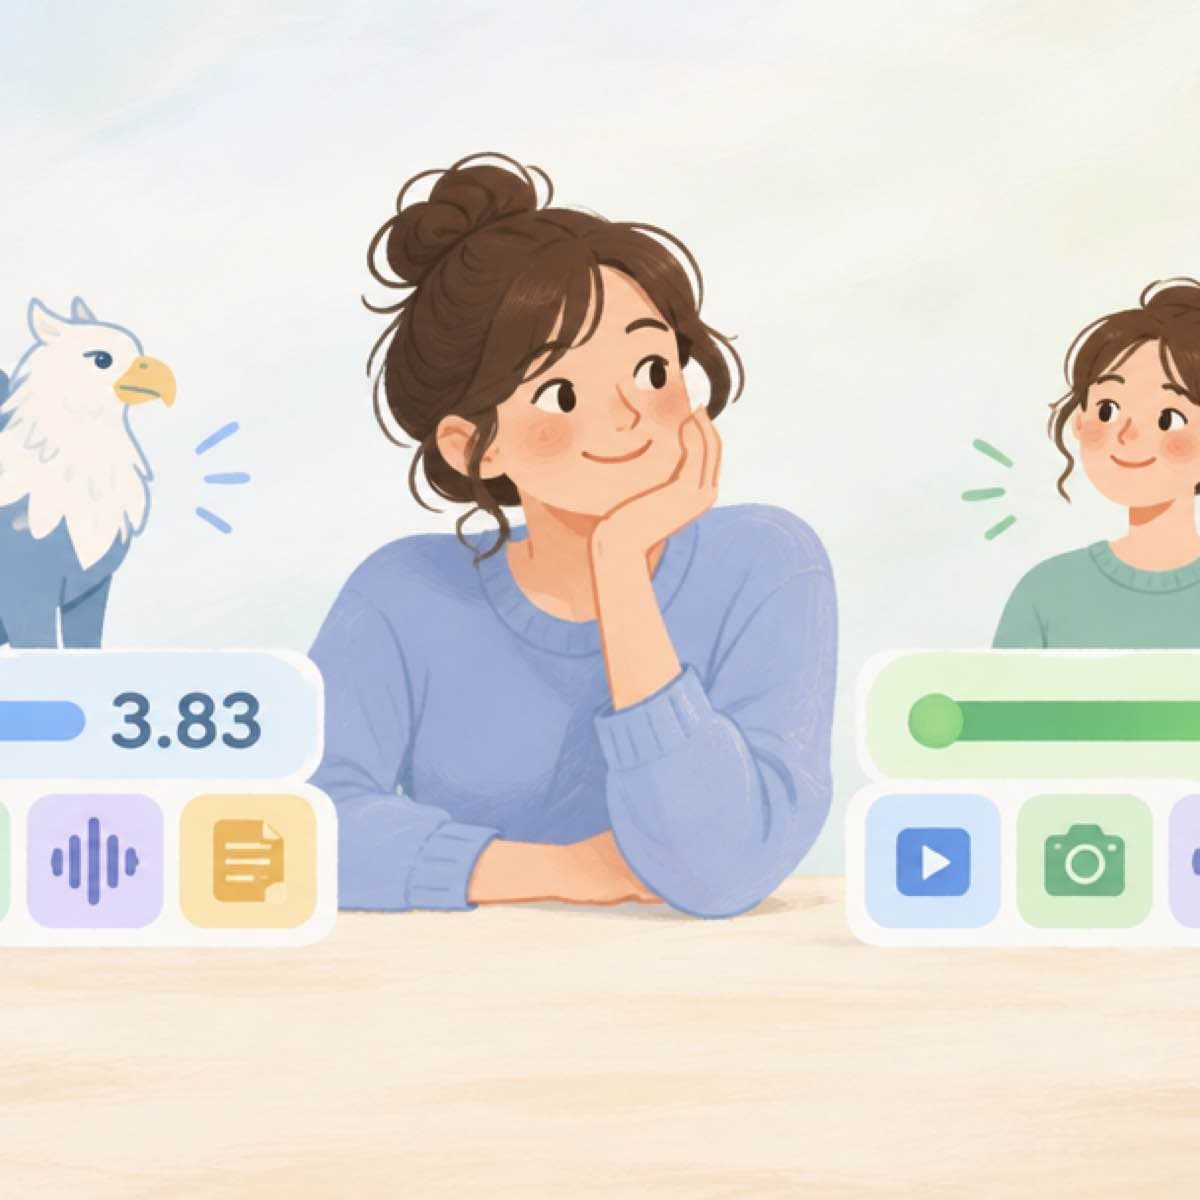
Griffin VideoFDB 3.83 vs human 3.92: what the scores cover
Tavus reports Griffin-Lite at 3.83 of 5 on VideoFDB generation against a 3.92 human reference. Those scores rate live conversation, not a scripted ad clip.
Talking avatar from an approved TTS file: image-to-video audio_url
To animate an avatar from a voiceover you already approved, send its Sume-hosted audio_url and duration_seconds to Avatar 1.0 image-to-video. Limits inside.
Does an AI avatar presenter make a Short original?
An avatar is a delivery method; YouTube's pages ask for original substance. How to give an Avatar 1.0 Short your own angle within its 60-second job limit.
What Sume Avatar 1.0 Does and Does Not Do vs Live Avatars
A plain list of what Sume Avatar 1.0 renders (scripted 4-60 s clips) and what it does not do (real-time conversation), set beside Tavus Griffin's live model.
Tavus Video to Face replica vs a Sume avatar from a photo or prompt
Tavus builds a replica from video or a photo; Sume builds an avatar from a prompt, props or a public photo URL. What each input gives you, and what it costs.
Full-duplex avatar listens while it speaks: script a clip instead
A full-duplex avatar hears you mid-sentence. If your content is scripted, build similar beats into one Sume avatar clip with silence scenes. Curl included.
Griffin-Lite 26 of 54 Turing result: what the sample size says
Tavus reports 26 of 54 callers fooled by Griffin-Lite after a one-minute call. A 95% interval is about 35% to 61%. Python computes it, and says what to claim.
Can I use Tavus Griffin-Lite yet? Preview status and what to ship
Tavus Griffin-Lite is a research preview for select trusted testers, not open to customers. Here is what the page says, and what you can build on Sume today.
What an AI avatar may not claim on TikTok Shop
TikTok Shop prohibits AI that impersonates real people or invents doctors and experts to endorse products. An avatar can present, but it can't be a fake expert.
One voice across 23 languages: MAI-Voice-2.1 vs a Sume avatar voice
MAI-Voice-2.1 keeps one voice across 23 languages. A Sume voice has one primary language and a 409 guard on mismatch. What that means for avatars.
Holiday ad captions on Avatar 1.0: slam, punch or tiktok-green?
Avatar 1.0 burns captions inline in slam (default), punch or tiktok-green. No separate billed caption job, and a caption failure keeps the clean video.
Approve the first frame, then pick the tier: Avatar video preview
Create Avatar 1.0 first-frame stills, regenerate until the look is right, then call generate-video with a quality override. Structural edits need a new preview.
Audit avatar videos for a missing CTA with cta_present
Sume's avatar-video metadata tags each scene with a segment_type and cta_present flag, so a script can list library clips that never ask viewers to act.
Avatar captions failed with script_alignment_mismatch: what to change
A pinned captions.script_text that does not align with the speech soft-fails the captions; the clean video stays. Match the spoken words, then re-caption.
Avatar package with captions and soundtrack: which video_url you get
In a Sume avatar package, captions burn onto the clean video first, then music is mixed in. If a stage soft-fails, video_url is the furthest successful file.
Avatar video is ready but transcript_text is null: poll metadata again
A Sume avatar video can be resource_status ready while metadata.status is still processing. The file is usable now; the transcript and tags arrive later.
Compare an avatar video's transcript_text to the approved script
Sume returns metadata.transcript_text on a finished avatar video once metadata is ready. Diff it against the approved script before publishing a support clip.
Bystander faces in a scene photo: check likeness before image_url
A photo scene can carry a stranger's face into the render. Check every face before you send image_url; the docs do not describe a screening step.
Map avatar video scene ids to onboarding steps with scene_previews
Give each video_inputs scene a stable id and Sume returns it in scene_previews with start, end and duration, so one clip can drive per-step chapters.
Pick a stock avatar by avoid_for and brand_safety_notes, not looks
Sume's avatar catalog returns profile metadata with best_for, avoid_for, brand_safety_notes and casting_notes. Read them before you cast a presenter for a clip.
Avatar video aspect ratios: five choices, 720p only, 9:16 default
Sume Avatar 1.0 accepts 1:1, 3:4, 9:16, 4:3 and 16:9, defaults to 9:16, and renders 720p only. What each choice means for a vertical or landscape ad.
UGC-style avatar ad: hook, silent demo beat and CTA in video_inputs
Build a three-scene UGC avatar ad with POST /v1/avatar-1.0/talking-video: a spoken hook, a silent demo beat, a spoken CTA, inside the 4 to 60 second window.
Avatar inline captions vs standalone video captions: what is billed
Inline captions on a Sume avatar video create no separate caption job. Standalone captions are a billed job on a public URL. When each one is right.
Full-duplex or script-driven avatar: six questions before you pick
Tavus Griffin-Lite is a full-duplex video conversation model in research preview. Six questions that separate it from Sume Avatar 1.0 talking video.
Avatar Face Swap (Beta) for ad variants: 4 to 15 second source clips
Sume's Avatar Face Swap Beta puts a ready avatar face on a public source video. What it requires, what it does not take, and how to poll the job.
Brand mascot as a reusable avatar: one photo, every ad video
Create the character once with a photo input on /v1/avatar-1.0/generate, then reuse its avatar_handle in each talking-video request so the face stays the same.
Voiceover too long for H3 Max lip sync: the 5 to 14.8 s window
MiniMax H3 Max lip sync on Sume takes Sume-hosted audio of 5 to 14.8 seconds, refuses other lengths instead of clamping, and caps the file at 10 MB.