Sume Avatar 1.0
Sume Avatar 1.0 by API: reusable avatars, talking video from a script, multi-scene and two-speaker videos, previews, B-roll, and Face Swap (Beta).
Start with Introducing Sume Avatar 1.0
Sume Avatar 1.0 creation cost: the price per avatar
Creating an Avatar 1.0 avatar on Sume is a fixed price per avatar, so a batch costs that price times the count. The total for every batch size priced.
Sume avatar talking video cost by length and quality tier
What an Avatar 1.0 talking video costs on Sume at the standard, plus and max tiers, with and without a product image, for each length and count priced.
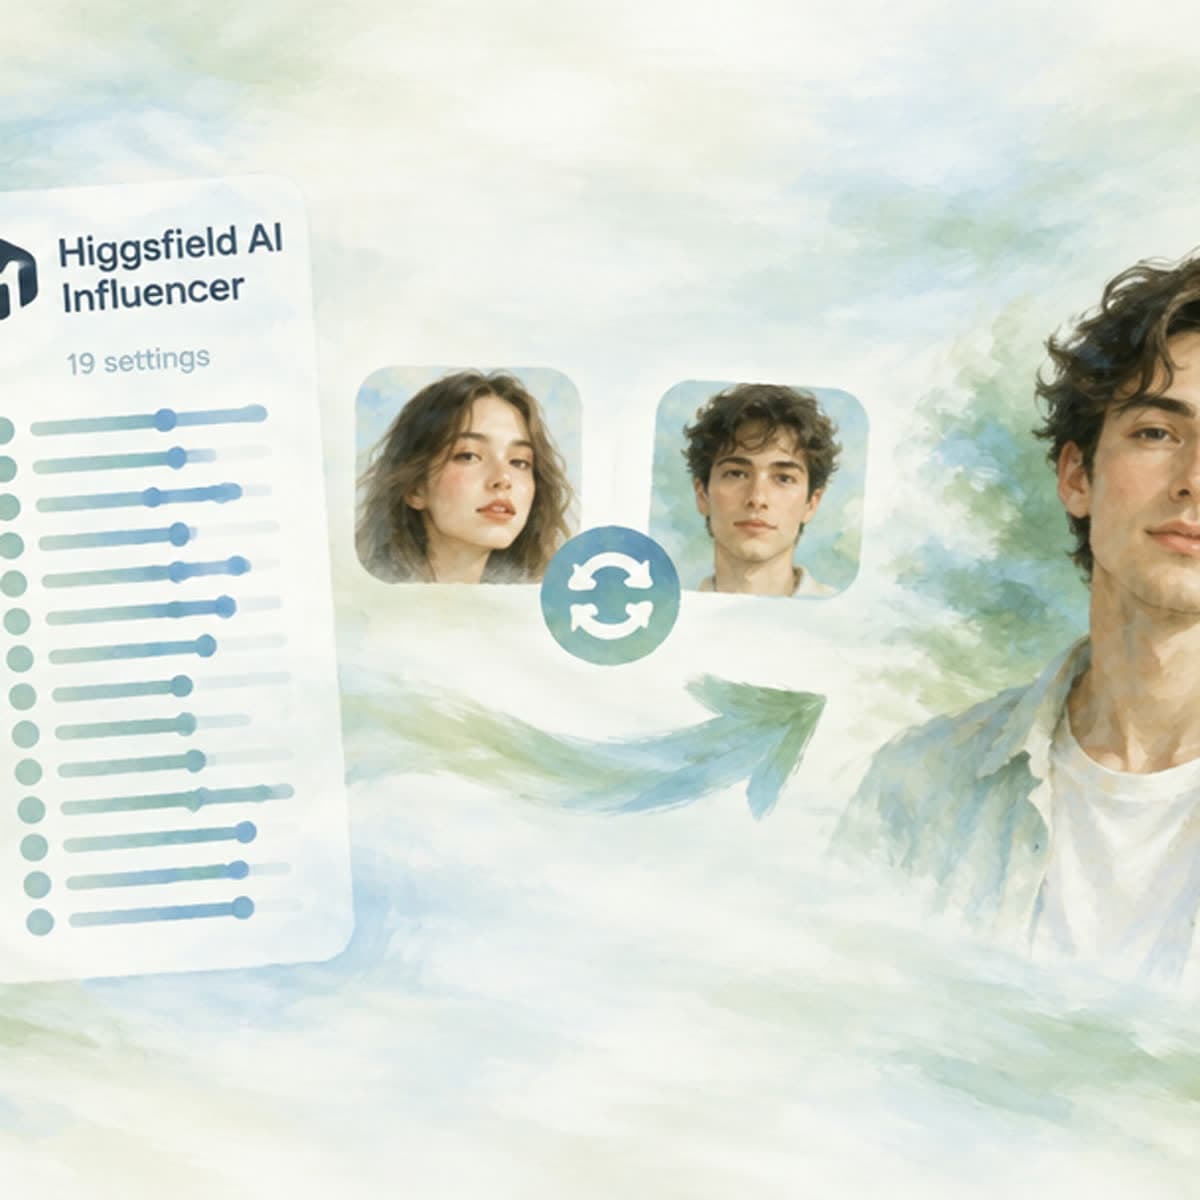
Higgsfield AI Influencer's 19 settings vs a Sume avatar and face swap
Higgsfield builds a character from 19 settings, then drops it into video. Sume makes an avatar from a prompt, photo or 3 traits, then script or face-swap it.
Why did that stock avatar rank first? Catalog search score weights
Sume's avatar catalog search scores handle 8, keywords 7, search card 6, display name 5. Read search_reasons and fix a query that ranks the wrong presenter.
Do [pause] tags and dashes in an avatar script cost extra seconds?
Sume Avatar 1.0 counts every space-separated token as a word, so [pause] tags and lone dashes add planned seconds. See the math and the silence-scene fix.
Is my Sume avatar ready? Check resource_status and preview_video_url
Read a Sume Avatar 1.0 resource before your first talking video: resource_status, preview_image_url, nullable preview_video_url, voice.status, handle filter.
UGC avatar scene prompt: why dim, glary lighting words are kept
Sume's first-frame step copies lighting words from your scene prompt as written, so ordinary light like TV glow or a side window stays. How to write it.
Avatar package soundtrack failed: what soundtrack_audio_* means
A package.soundtrack.audio_url that fails does not fail the video. Read package.soundtrack.public_reason: url_blocked, too_large, not_audio or download_failed.
HeyGen Voice is free in the API: what a talking video costs
HeyGen Voice launched Oct 9 as free in the platform and API. A voice model is one part of a talking video; see Sume's per-second render prices by tier.
Face swap or talking video: which Avatar endpoint fits?
Pick Sume Avatar face swap (Beta) or Avatar talking video by what you have: footage with audio, or a script. Inputs, limits and polling side by side.
Avatar video request rejected? Pre-flight these 6 inputs
Catch Sume Avatar 1.0 rejections before you submit: script vs video_inputs, the 4-60 second window, silence scenes, HTTPS media and caption style. A checklist.
Gradium's 329 character voices vs voices of Sume avatars
Gradium lists 329 character voices. On Sume, a spoken character is an avatar with a ready voice; Avatar 1.0 is English-only. What that means for casting.
Avatar preview final render has no webhook_url: poll the job
The preview generate-video call takes only quality, so it has no webhook_url. Poll the job, or use the direct avatar endpoint for a webhook-driven render.
Face swap beta, 9-second clip: you reserve the 15-second price
Sume's Avatar Face Swap beta reserves the maximum 15-second source price whatever your clip length: $2.76 at standard, $3.675 at plus, $8.25 at max.
Narrate a listing in your avatar's voice: TTS with avatar_handle
Sume TTS 1.0 can speak with the voice of a ready avatar if you pass avatar_handle. A 1,200-character listing script costs $0.057.
Avatar handle with a hyphen is rejected: the valid pattern
Sume avatar handles allow letters, digits, periods and underscores, 2 to 30 characters. A hyphen fails the pattern. Check yours in Python first.
Griffin-Lite's 0.27 to 0.59 s latency in 25 fps frames vs Sume clips
Tavus reports Griffin-Lite video latency of 0.43 s average (0.27 best, 0.59 worst). At 25 fps that is 7 to 15 frames. Sume renders recorded clips.
Which MCP grant lets an agent create an avatar? Write, no paid scope
On Sume's hosted MCP, avatars_create and the avatar video tools are paid tools that need the Write toggle at consent. There is no mcp:paid scope.
What to log for a likeness consent trail: five fields per request
Sume avatar and face swap requests carry an avatar_handle, a source URL, a quality, an Idempotency-Key and a job id. Log those five with the consent record.
One 15-second avatar script in 9:16, 1:1 and 16:9: cost of all three
Rendering one 15 s script in three aspect ratios is three jobs: $8.28 at standard, $11.025 at plus, $24.75 at max. Aspect ratio does not change the price.
Recast 3 old 10-second clips with the face swap beta: cost by tier
Face swap beta reserves 15 seconds of the tier price per run, so 3 runs cost $8.28 standard, $11.025 plus, $24.75 max.
Can a Sume avatar speak my own recording? Voice types explained
Avatar 1.0 talking video takes a script or per-scene voice blocks of type text or silence. What the docs list, what they do not, and how to plan a pause.
One wrong sentence in an avatar script: what 5 re-renders cost
Changing a script means a new Avatar 1.0 job. Five full re-renders of a 20-second take cost $18.40 on standard, $24.50 on plus and $55.00 on max.
Griffin-Lite 26 of 54: error bars and a viewer test for avatars
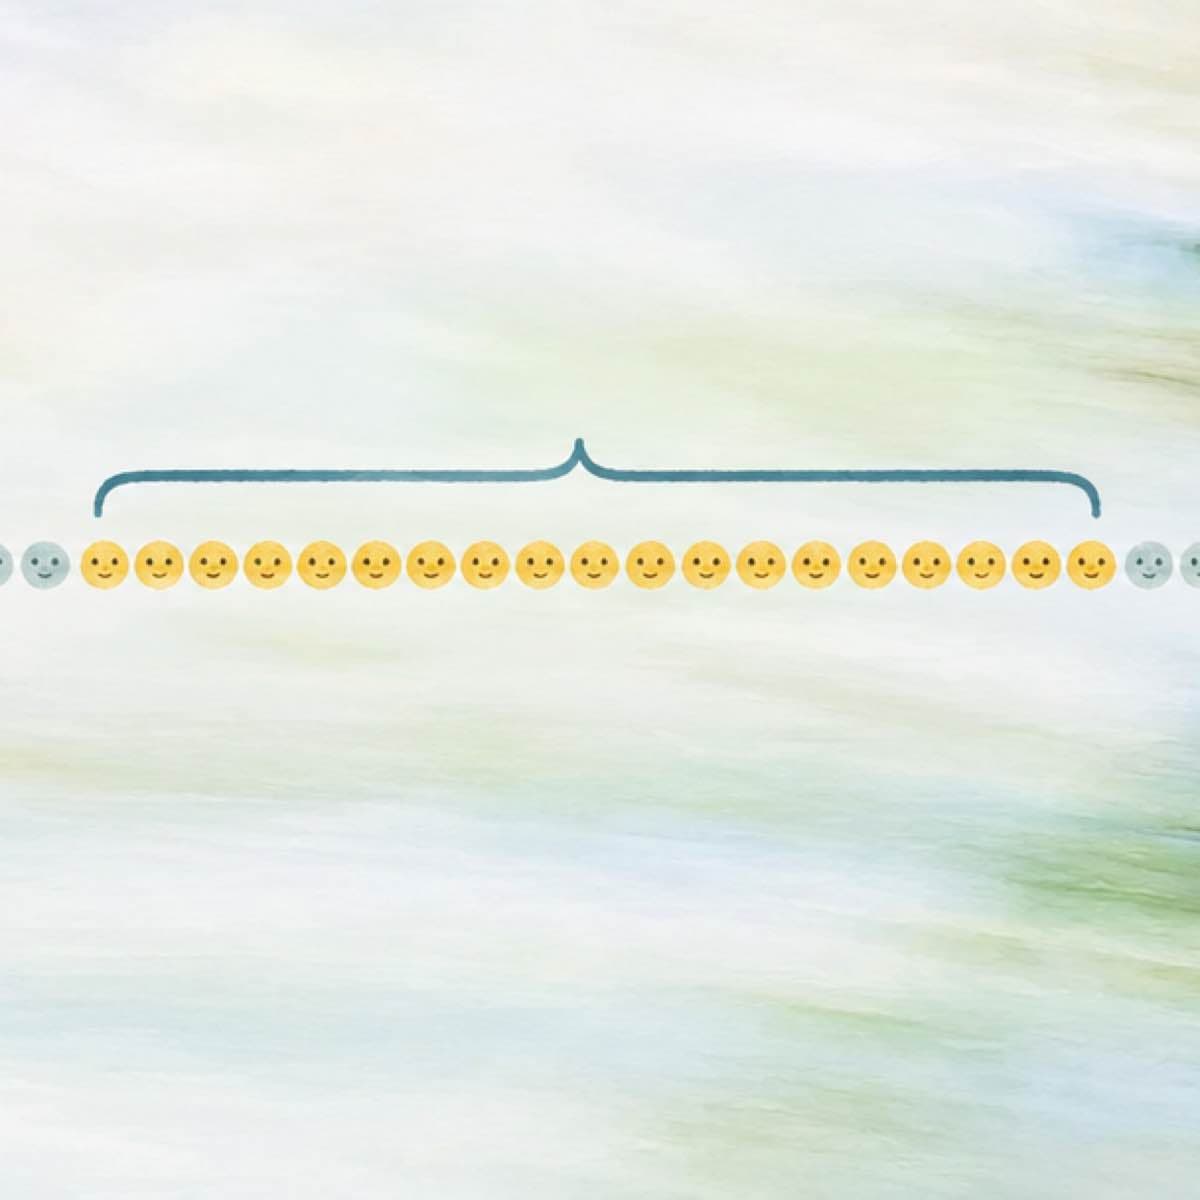
Tavus says 48% of 54 people took Griffin-Lite for real. With 54 viewers the 95% range is 35% to 61%. A Python check and a test plan for Sume avatar clips.
A 170-word avatar script in 34-word sentences plans 70 s: refused
Why a 170-word script of five 34-word sentences needs 70 seconds in Avatar 1.0, past the 60-second cap, and how to split it into two 35-second videos.
Avatar script: 33 words = one 12 s clip, 34 words = two 7 s clips
A Sume Avatar 1.0 sentence of 33 words fits one 12-second clip. Add a 34th word and it splits into two 7-second clips. The numbers, with code.
A 58-word six-sentence avatar script becomes a 10 s and a 12 s clip
How Sume Avatar 1.0 plans a 58-word script of six sentences: 27 words in 10 seconds, then 31 words in 12 seconds, 22 seconds total, and why the cut falls there.
Five 20-word avatar sentences make five 8-second clips, not three
Why five 20-word sentences plan as five 8-second clips (40 s) in Avatar 1.0, and how pairing shorter sentences saves clips.
One Sume avatar handle across talking video, TTS, stills and lip sync
A Sume avatar handle is accepted by talking-video, TTS voice selection, face-in-still images and the lip-sync routes. What each uses from it and what it costs.
Does Sume Avatar 1.0 speak Spanish or Korean? English only in code
The Avatar 1.0 talking-video prompt on main says English only. What that means for Spanish or Korean lines, and the audio-driven route to test instead.
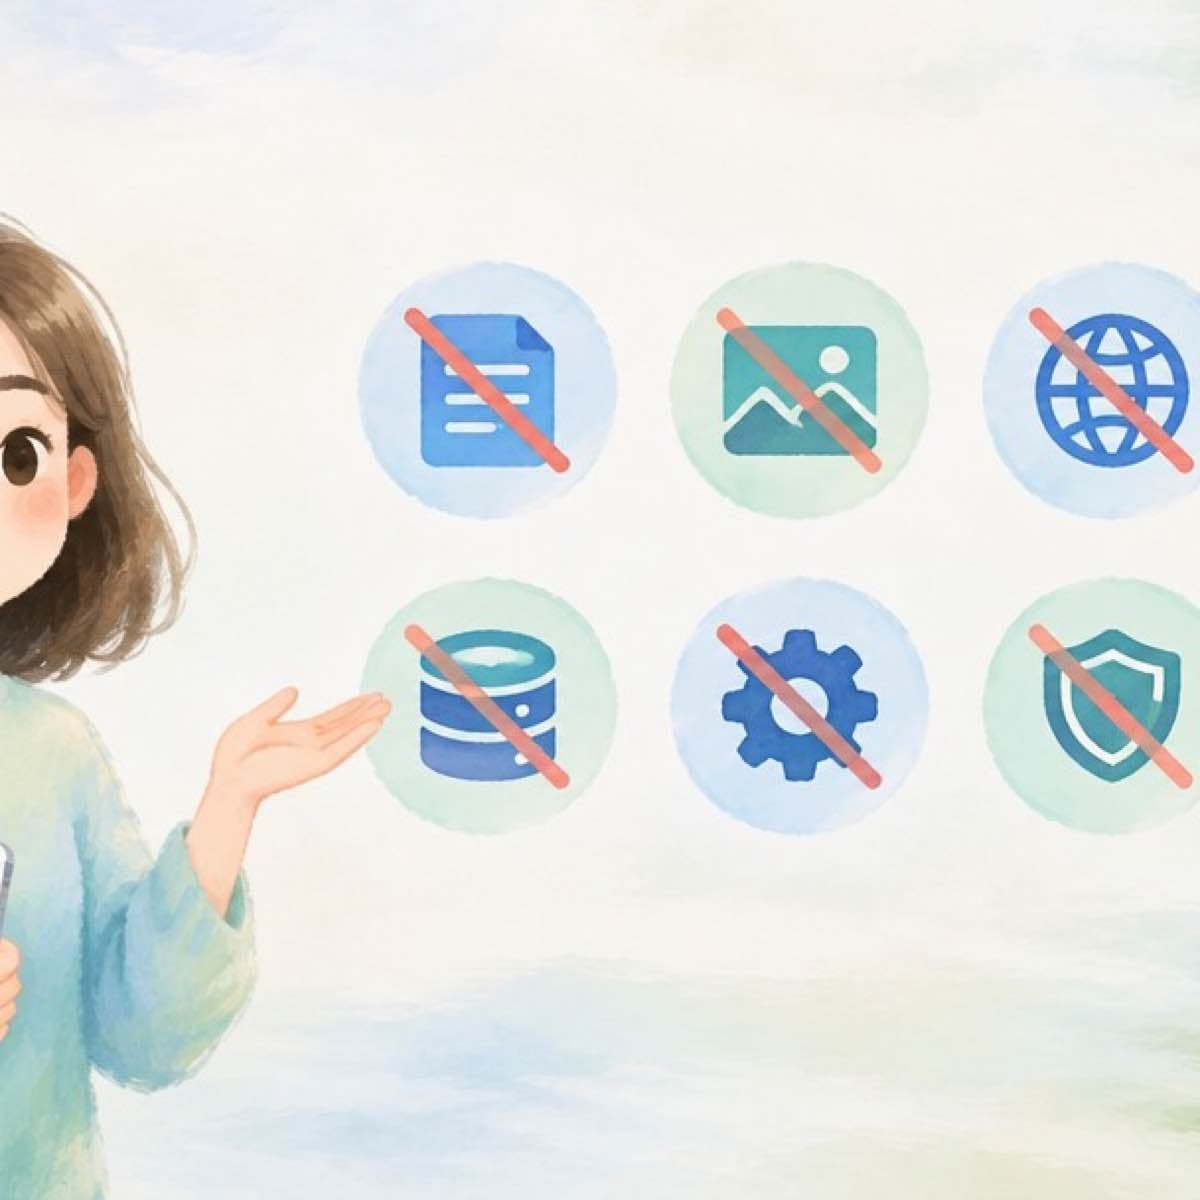
What Sume Avatar 1.0 does not do: eight limits to check first
No streaming, no interruption, English-only speech in code, 720p, 4 to 60 seconds, one avatar per video. The limits of Sume Avatar 1.0 in one table.
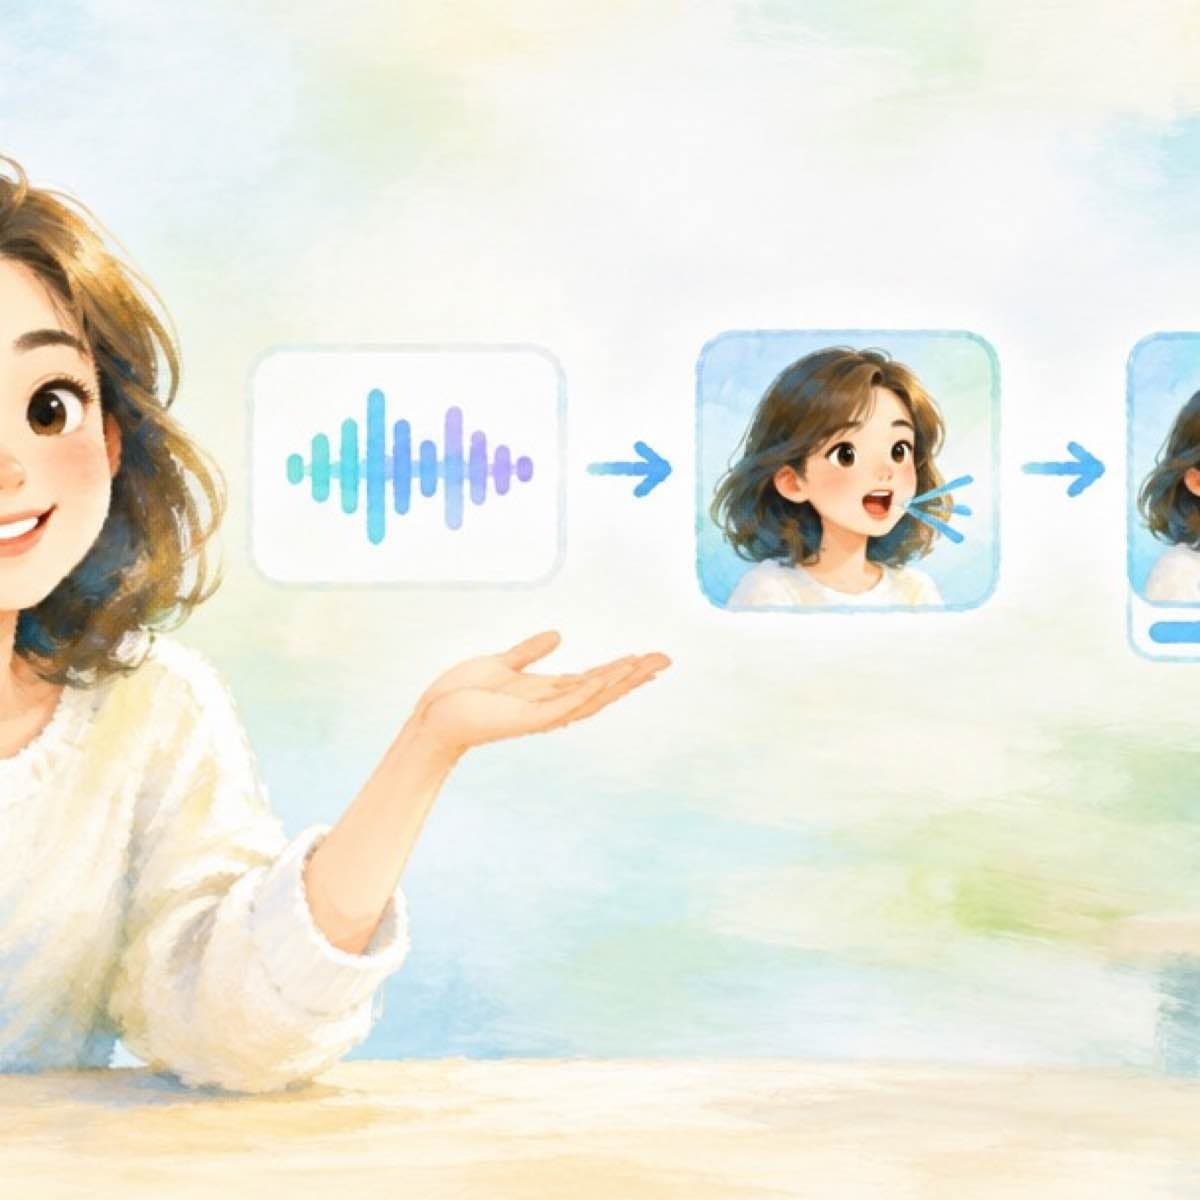
Sume TTS voice then H3 Max lip sync: 40 seconds in 3 slices
H3 Max lip-sync accepts 5 to 14.8 s of audio. Split a 40 second TTS script into three sentence-based slices at $4.00 on 768p, and what to check.
Lip sync a Korean voice recording on Sume: which route, what it costs
Avatar Video is English only in code. For a Korean recording, Sume offers audio-driven routes: H3 Max lip-sync and VEED Fabric. Windows, rates and a test plan.
AI avatar video aspect ratios: 5 options, 720p only on Sume
Sume Avatar 1.0 talking videos support 1:1, 3:4, 9:16, 4:3 and 16:9 at 720p. How to pick a ratio for Reels, ads, feed posts and web pages.
Will an AI video model lip-sync a voice-over added afterwards?
No: Sume's docs say video models do not lip-sync to generated speech or a later voice-over. A talking face needs a still plus audio, or an avatar video.
Make an AI avatar from a selfie: the photo URL rules on Sume
Sume builds an avatar from a prompt, a profile or a photo. The photo must be a public HTTPS image URL; localhost, private and non-image URLs are rejected.
Preview an AI avatar video before paying for the full render
Sume avatar video previews make first-frame stills only. Approve them, then call generate-video; you can change the final quality tier without a new preview.
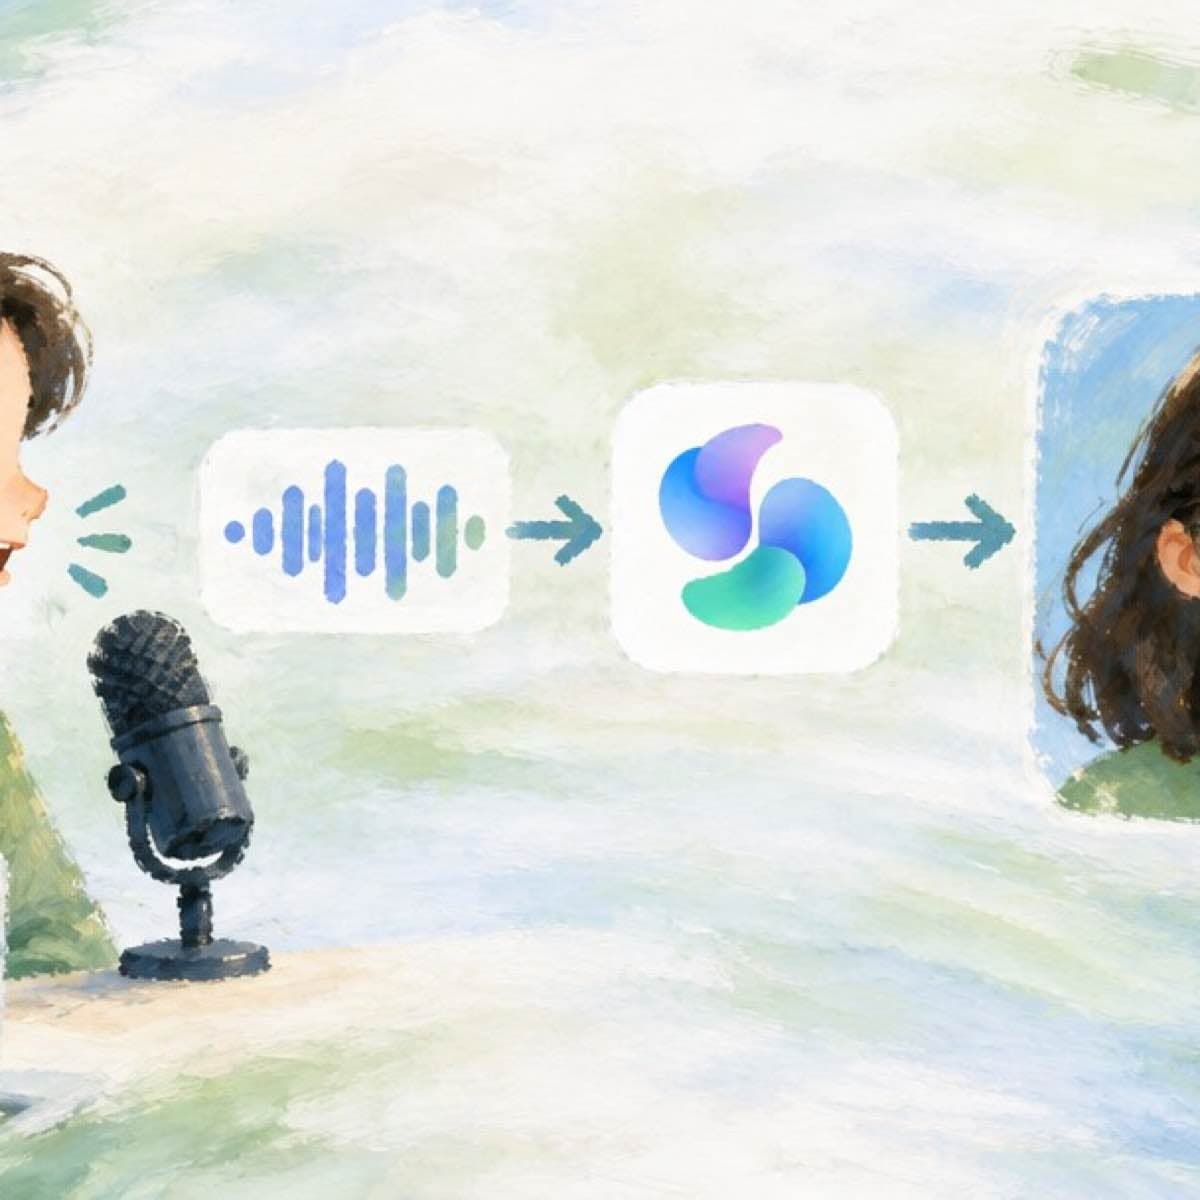
Recorded voice to talking face: Fabric or H3 Max lip sync on Sume?
Sume has two still-plus-audio routes: veed/fabric-1.0 for 1-300 s and MiniMax H3 Max Lip Sync for audio of 5-14.8 s. Choose by audio length and what you have.
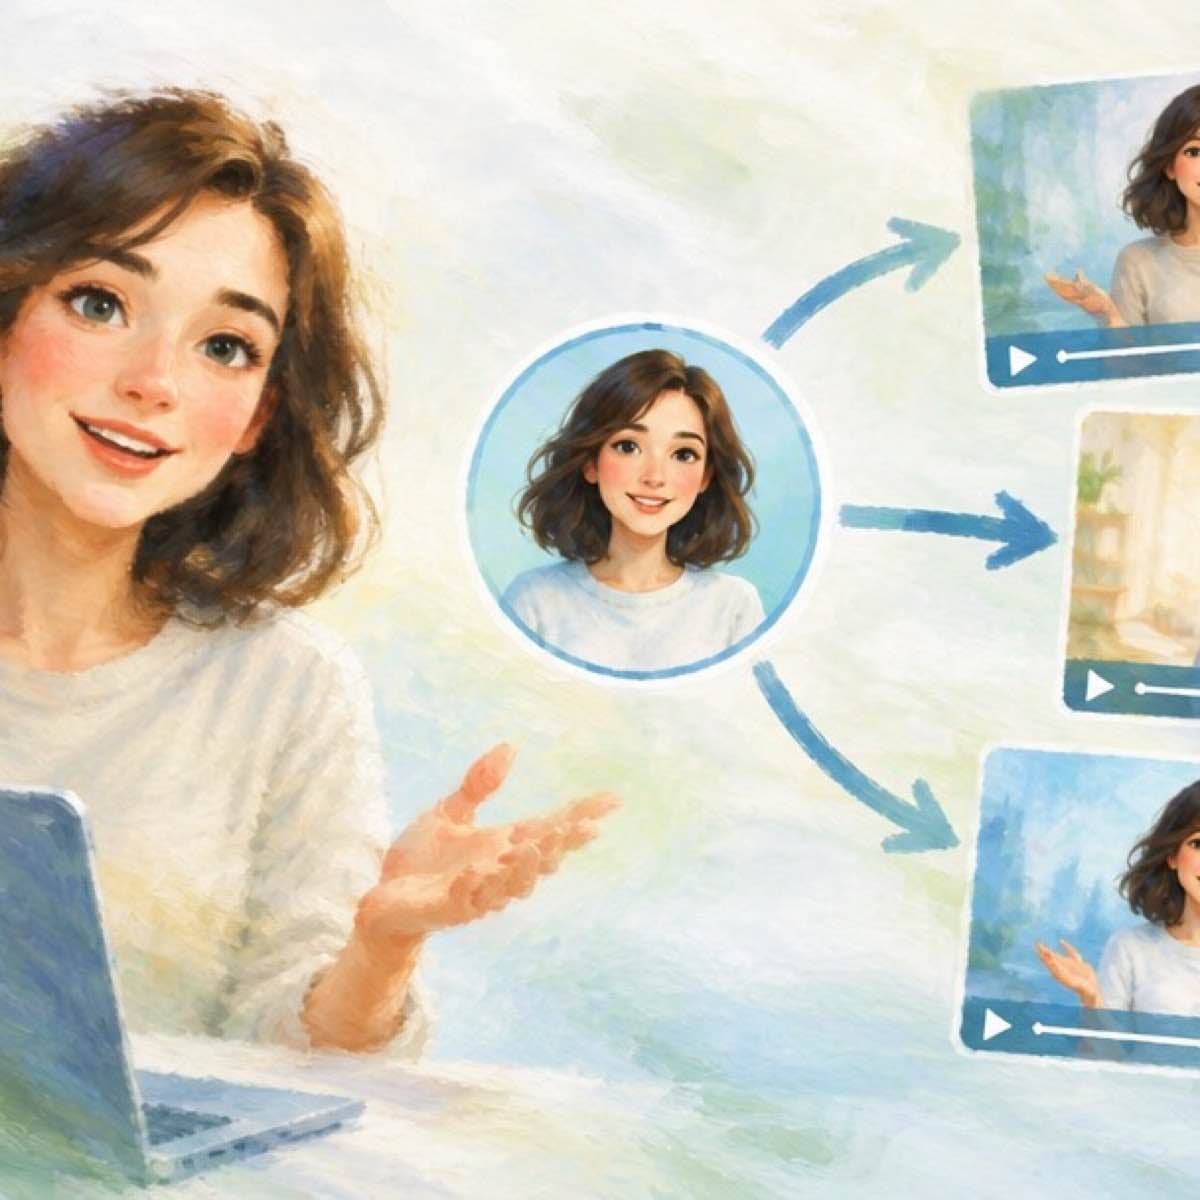
Reuse one AI spokesperson across videos with an avatar handle
A Sume avatar_handle is a stable name for a ready avatar. Sume strips a leading @, so you create once and call the handle in every talking-video request.
AI avatar video length limit: Sume accepts 4 to 60 seconds
Sume Avatar 1.0 accepts scripts that it estimates at 4-60 seconds. What happens outside that window, and how to split a longer script into jobs.
Avatar face swap beta limits: 4 to 15 seconds, quality required
Sume Avatar Face Swap is Beta: a public HTTPS source video of about 4-15 seconds with audio, a required quality tier, and no prompt or aspect options.
Avatar video with a product image: the per-second price gap
On Sume Avatar 1.0 a product_image adds $0.010 to $0.030 per second by tier. For a 30-second spokesperson clip that is $0.30 to $0.90. Arithmetic inside.
Avatar video succeeded but captions failed: what to do on Sume
On Sume a caption-stage failure is soft: the avatar job can still succeed with a clean video_url and captions.status=failed. How to check it and add captions.
Video call avatar or scripted talking video: which do you need?
A real-time avatar answers people live; a scripted talking video is a file you render and review first. How to choose, and what Sume Avatar 1.0 covers.
Add a silent beat to an AI avatar video with voice type silence
In Sume multi-scene avatar videos a scene with voice type silence is a pause with no speech. It needs a duration and rejects script text. Rules and example.
Sume Avatar 1.0 ratios vs TikTok ad ratios: three overlap, two do not
Avatar 1.0 makes 1:1, 3:4, 9:16, 4:3 or 16:9 at 720p, 4 to 60 s. TikTok's non-Spark ad page lists 9:16, 16:9 and 1:1, so 3:4 and 4:3 need a crop.
Can you buy Tavus Griffin-Lite? Presenter video options today
Tavus Griffin-Lite is a research preview for trusted testers, not a product customers can buy. What Sume ships for presenter videos in the meantime.
Vidu Q4 audio references vs a scripted avatar: which keeps a voice?
Vidu Q4 Preview takes up to 3 audio references; Sume does not list Vidu. How a scripted avatar video keeps a presenter's face and words consistent.