Models
The models behind Sume's video, image, speech, and music endpoints: ids, clip lengths, resolutions, aspect ratios, audio, references, and migration.
Start with What AI models does Sume support? Every model id, by API surface
EU, UK or South Korea team: which open video weights you may use
HunyuanVideo and MiniMax H3 licenses exclude the EU, UK and South Korea. Wan 2.2 is Apache 2.0 and LTX-2.5 is worldwide with a revenue line.
Gemini Omni Flash 1.1 ranks 8th, 4th and 3rd on three AA boards
Gemini Omni Flash 1.1 is eighth on AA text-to-video, fourth on image-to-video and third on editing. On Sume it is one id at $0.125 a second at 720p.
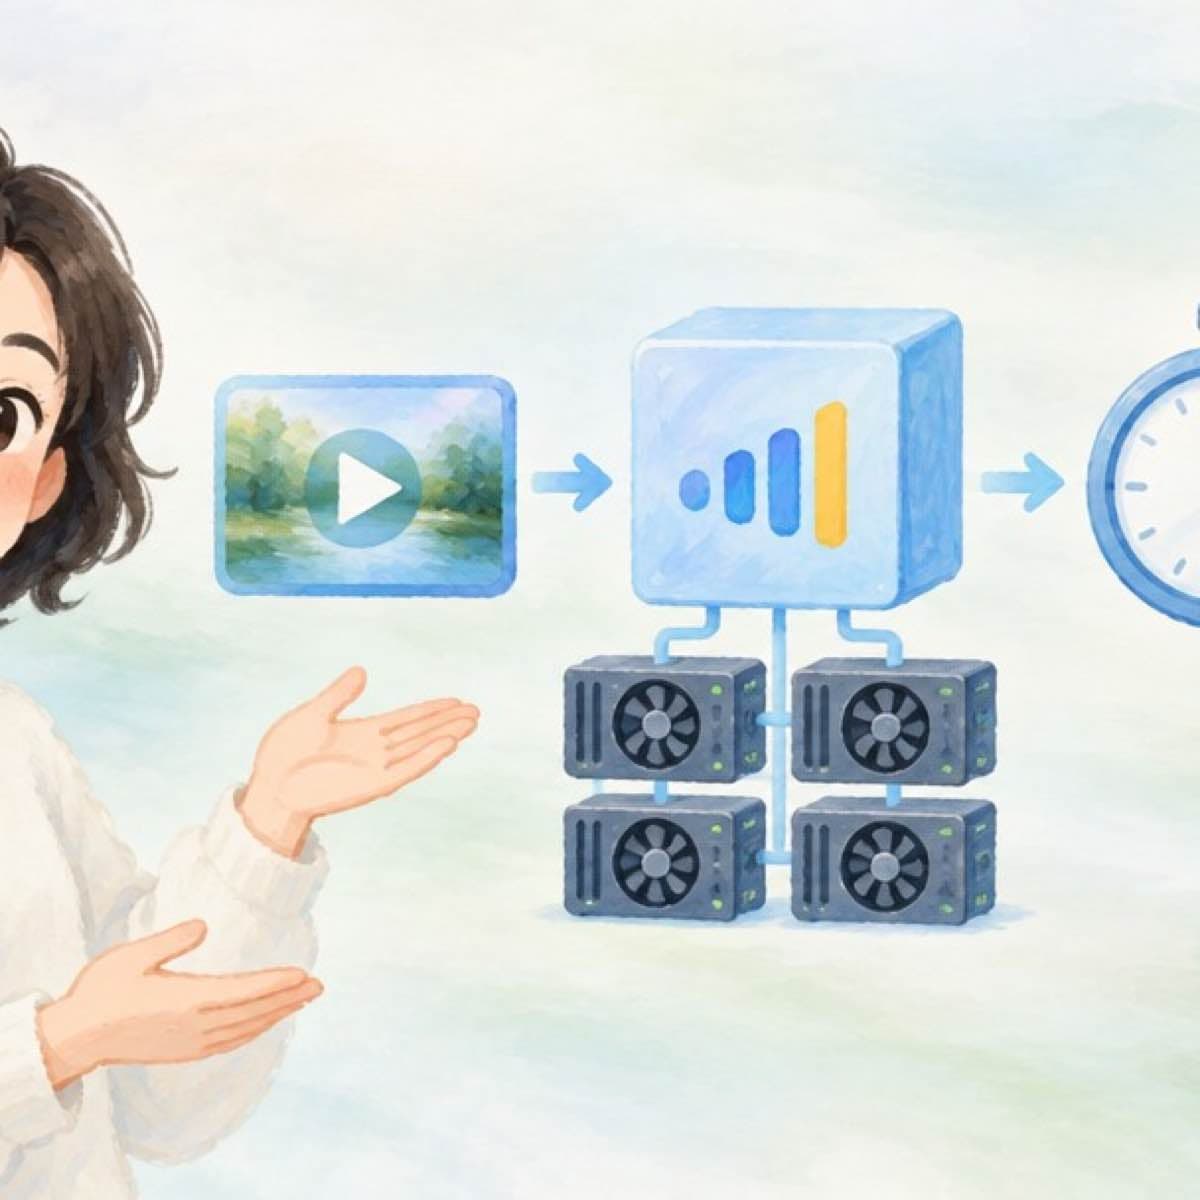
H3 on vLLM-Omni: 87 s on 4 B300 for one clip, and the cost
MiniMax says an 8.7 s H3 clip takes about 87 s on 4 B300 GPUs. Turn that into GPU-seconds, a break-even rate, and compare with a 9 s Sume job.
Mac or Windows team: which open video models need Linux and CUDA?
HunyuanVideo and HunyuanVideo-1.5 list Linux; LTX-2.5's fastest decoder is Linux plus CUDA; H3 has a Mac route. What each page says and a hosted option.
MiniMax H3 4K hero clip vs 768p cutdowns: holiday ad cost
A 10-second MiniMax H3 clip is $0.75 at 768p, $1.625 at 2K and $2.00 at 4K on Sume. Five free reference images are included; extra ones are $0.10 each.
MiniMax H3 on a 12 GB RTX 3060: 480p only, 42 GB, and the price
MiniMax says 12 GB of VRAM runs 480p H3 clips with audio from a pruned int8 checkpoint of about 42 GB. What that buys, and a 480p clip on Sume costs.
Packaging label text test: 12 prompts on 3 Sume models, what it costs
Test Nano Banana 2.1, Imagen 4 Ultra and GPT Image 2.5 on 12 label-text prompts first: about $1.20, $0.90 and $1.40 on Sume. A short script runs it.
AA text-to-video top 12: six you can call on Sume, six you cannot
Of the 12 models on the AA text-to-video board, six have a Sume id that takes a prompt-only request. The list, with Elo and Sume's price per minute.
Video editing board: Wan 3.0 1,187, Seedance 2.5 1,151; Sume uses Omni
Wan 3.0 tops the AA video-editing board at 1,187 Elo. Sume's documented edit route is video_url on gemini-omni-flash-1.1, third at 1,139. Price inside.
Wan 2.2 CUDA out of memory: offload_model, dtype and t5_cpu flags
The Wan 2.2 README fixes OOM with three flags: offload_model, convert_model_dtype and t5_cpu. Which commands need 80 GB and 24 GB, and what it does not promise.
What a 13-point Elo gap means: Wan 3.0 vs Seedance 2.5 win chance
Wan 3.0 leads Seedance 2.5 by 13 Elo on the AA text-to-video board. On the standard Elo scale that is a 51.9% win chance per vote. Arithmetic for other gaps.
Can I show HunyuanVideo clips to EU viewers? Section 5(c) read
Tencent's HunyuanVideo license says do not use or display Outputs outside the Territory, which excludes the EU, UK and South Korea. Clause by clause.
Can you train a model on open video weights' outputs? Four licenses
H3 and HunyuanVideo bar using outputs to improve other models. LTX bars commercial distillation. Wan 2.2 is Apache 2.0. The clauses, quoted from vendor files.
Do you have to credit an open video model? Label, notice, license
H3 requires a visible 'MiniMax H3' label in commercial products. Hunyuan only encourages 'Powered by'. LTX and Wan ask for notices and a license copy. Per file.
Does Sume offer Haiku 5.5, GLM 5.3 Flash or Mistral Large 4?
Checked against Sume's model catalog on 2026-10-08: Haiku 5.5 and GLM 5.3 Flash have enabled rows; Mistral Large 4, Clef and Strands Decider 2B have none.
Gemini Omni Flash 1.1 at 4K vs 1080p for an 8-second product ad
An 8-second Gemini Omni Flash 1.1 clip costs $1.00 at 720p, $1.50 at 1080p and $3.00 at 4K on Sume. Audio is always on and the ratio is 16:9 or 9:16.
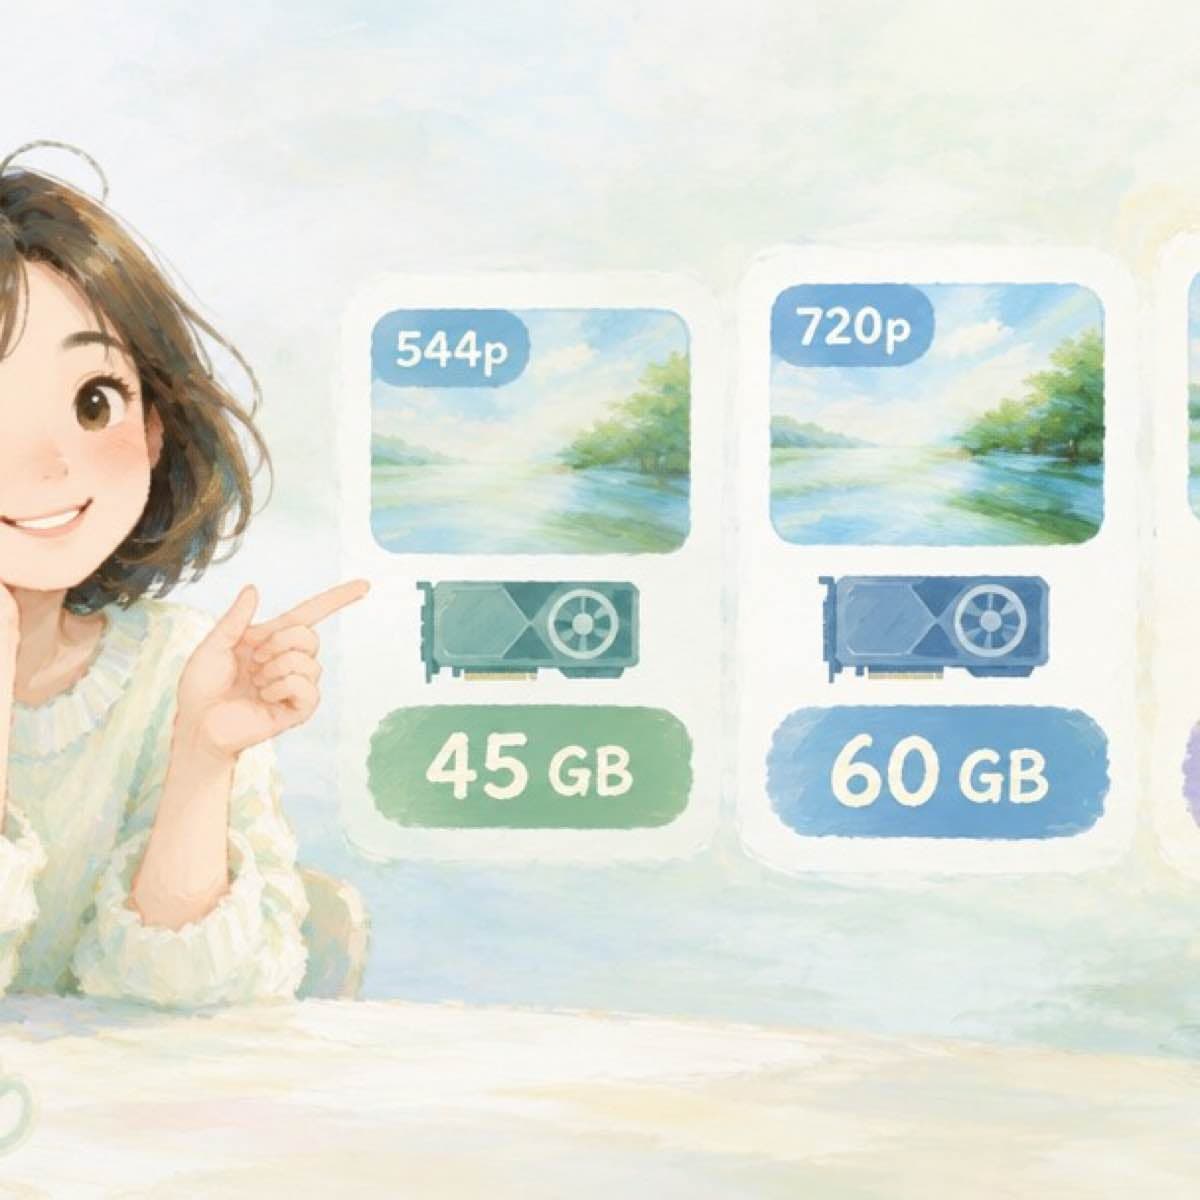
HunyuanVideo VRAM: 45 GB at 544p, 60 GB at 720p, 80 GB advised
The HunyuanVideo README lists 45 GB for 544x960 and 60 GB for 720x1280 at 129 frames, tested on one 80 GB GPU. FP8 saves about 10 GB. Table and hosted route.
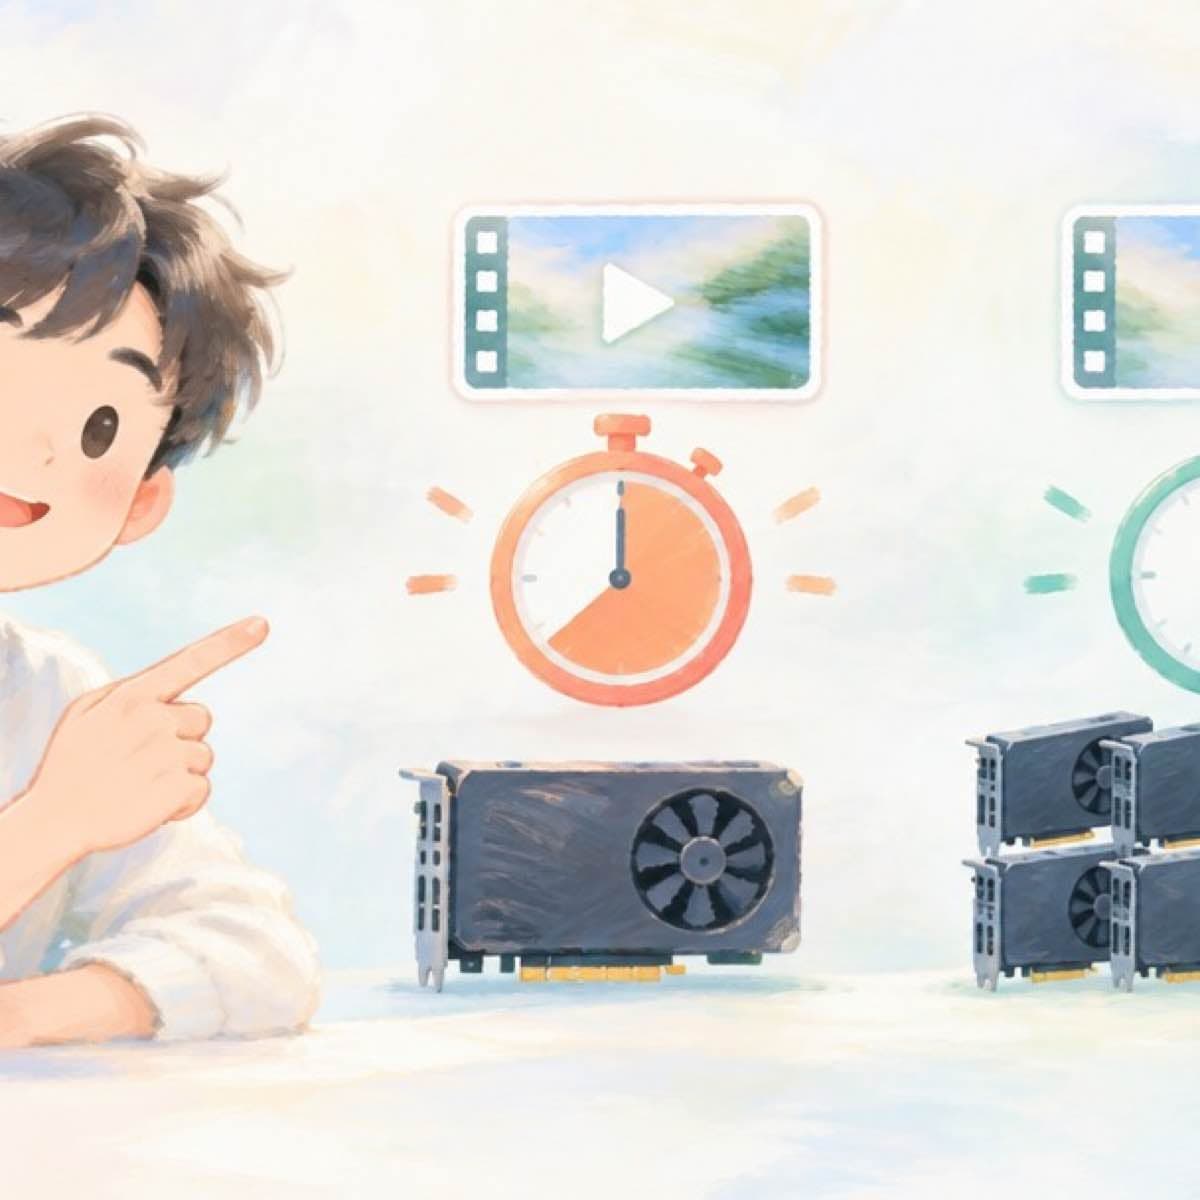
HunyuanVideo 720p: 1,904 s on one GPU, 338 s on eight
README latency for a 1280x720, 129-frame, 50-step clip: 1,904 s on 1 GPU and 338 s on 8. The GPU-seconds each setup burns, and what it means for hosted jobs.
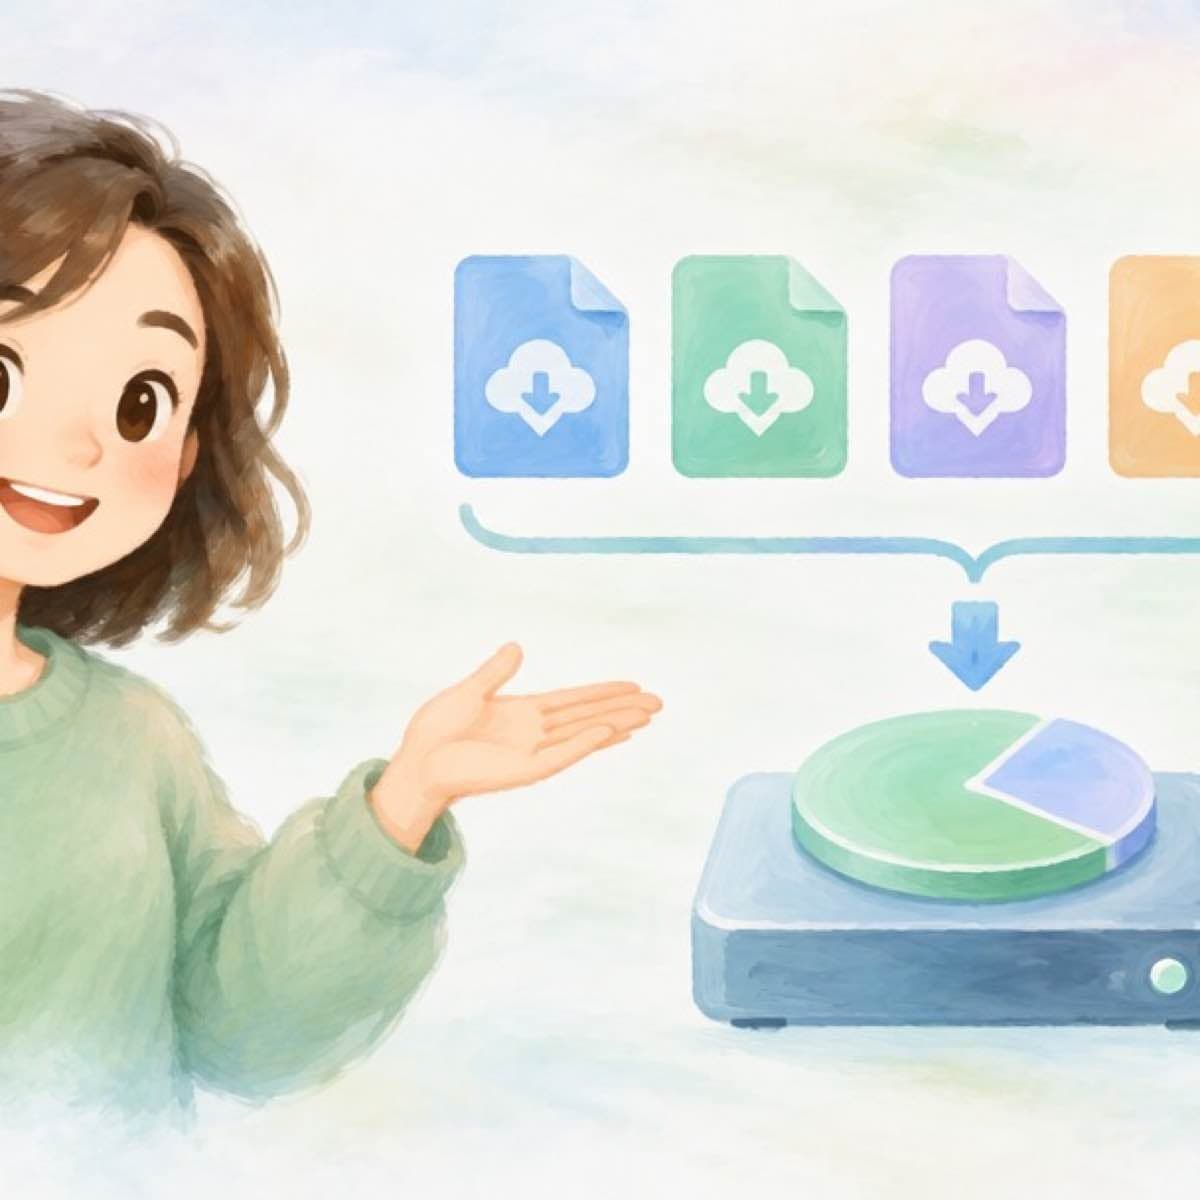
LTX-2.5 quick start downloads 66 GiB: the five files and a disk plan
The LTX-2 README quick start pulls about 66 GiB for five LTX-2.5 files, including a 12B Gemma text encoder. What to budget, and what Sume lists instead.
500-image job on a preview model: Hy Image 3.5 availability, plan B
OpenRouter shows 83.39% availability over 3 days for Hy Image 3.5 Preview, one provider. At 500 images that is about 83 failures to retry. Plan B on Sume.
Strands Decider 2B scores 167 of 231: not a spend guard
The Strands Decider 2B card reports 167 of 231 correct on JevBench public (72.3%). Fine for routing, not payment control. Why Sume's spend cap decides.
US company and open video weights: H3 is out, three others differ
MiniMax H3 weights exclude the US by license. HunyuanVideo, Wan 2.2 and LTX-2.5 read differently. A territory table and a hosted route on Sume.
Wan 2.2 prompt extension: a DashScope key or a local Qwen model
Wan 2.2's README offers prompt extension via Alibaba DashScope (DASH_API_KEY) or a local Qwen model. What each needs, and what Sume's request takes.
Which Sume image model after this week's launches: lookup by need
A lookup table: text drafts, photo edits, label text, 4K, 12+ references. Maps Nano Banana 2.1, Imagen 4, GPT Image 2.5 and Hy Image to what Sume lists.
Who owns an AI video from open weights? Output clauses compared
H3 says you own outputs, Hunyuan, LTX and Wan 2.2 claim no rights in them. What each clause adds or withholds, read from the vendor files.
4:5, 9:16 and 16:9 together: 15 of 19 Sume image models list all three
Which Sume image models list 4:5, 9:16 and 16:9 in one catalog row, which four miss 4:5, and what each costs per image.
Edit with input_references: 5 of 19 Sume image models are text-only
Five Sume image models cannot take input_references: Soul, Imagen 4 Fast, Imagen 4 Ultra, Recraft V4 and Qwen Image Max. Here are the 14 that can, with prices.
Pin lyria-3.5 or leave sume/music-auto? Read routed_model per job
sume/music-auto resolves to Lyria 3.5 today and can move without notice. When to pin lyria-3.5 on Sume and how job.request.routed_model records the engine.
background: transparent on the Sume image API: two GPT rows only
Transparent PNGs from the Sume image API need background: transparent, which only the two GPT Image 2.5 rows list. See the request, price and the 400 elsewhere.
nano-banana-2 still works on Sume: it runs as Nano Banana 2.1 at 10c
Nano Banana 2 is retired on Sume. The ids nano-banana-2 and google/nano-banana-2 still work and run as Nano Banana 2.1, and the job stores the 2.1 id.
Sonic 3.6 vs 3.5 vs 3 on Sume TTS: same price, so pin the id
All Sonic ids in Sume's TTS router list 38 micro-dollars per character and a 20,000-character cap. sonic-latest is an alias for 3.6. What to pin and why.
Wan 3.0 reference limits: 10 images, 5 videos and 5 audio tracks
Sume lists Wan 3.0 references as up to 10 images, 5 videos (15 s total) and 5 audio tracks (15 s total). Sume docs do not claim 50 references.
3:2 photo ratio image API: GPT Image 2.5 does not list it on Sume
3:2 is the classic camera ratio, yet GPT Image 2.5 and GPT Image 2 do not list it on Sume. Fourteen other rows do. Table of rows and the crop workaround.
Hy Image 3.5 lists 13 ratios; GPT Image 2.5 on Sume lacks six
OpenRouter's Hy Image 3.5 Preview ratio list has six ratios GPT Image 2.5 does not offer on Sume: 1:2, 1:4, 2:1, 2:3, 3:2 and 4:1. Which Sume rows list them.
Grep for nano-banana-2 in your code: those calls bill as 2.1
Retired Nano Banana 2 ids still run on Sume, as 2.1 at 10 cents at 1K. A grep-and-replace plan so logs, tests and cost sheets name the model that ran.
Seedance 2 Mini at 1080p costs less than Seedance 2.5 at 720p: 10 s
A 10-second 9:16 clip: Seedance 2 Mini at 1080p is $4.26 on Sume, below Seedance 2.5 at 720p ($5.78). Full ladder for 2.5, 2.0, Fast and Mini inside.
Vidu Q4 takes 15 image refs: what Sume's reference limits are
Vidu Q4 Preview lists up to 15 image and 3 audio references. Sume does not list Vidu; Gemini Omni Flash 1.1 takes 10 images and 3 clips of 3 s, none audio.
Edit a clip, swap a person, or move motion onto photos: 3 Sume models
Omni Flash edits a clip by prompt ($1.25 per 10 s, 720p), H3 Max Recast swaps people ($3.75, 768p), Genjutsu moves motion onto photos ($3.98, 480p).
Is Hy Image 3.5 Preview on Sume? Check the models list in code
Tencent's Hy Image 3.5 Preview is not in the Sume rows used here. How to confirm against GET /v1/images/models with a 12-line script instead of guessing an id.
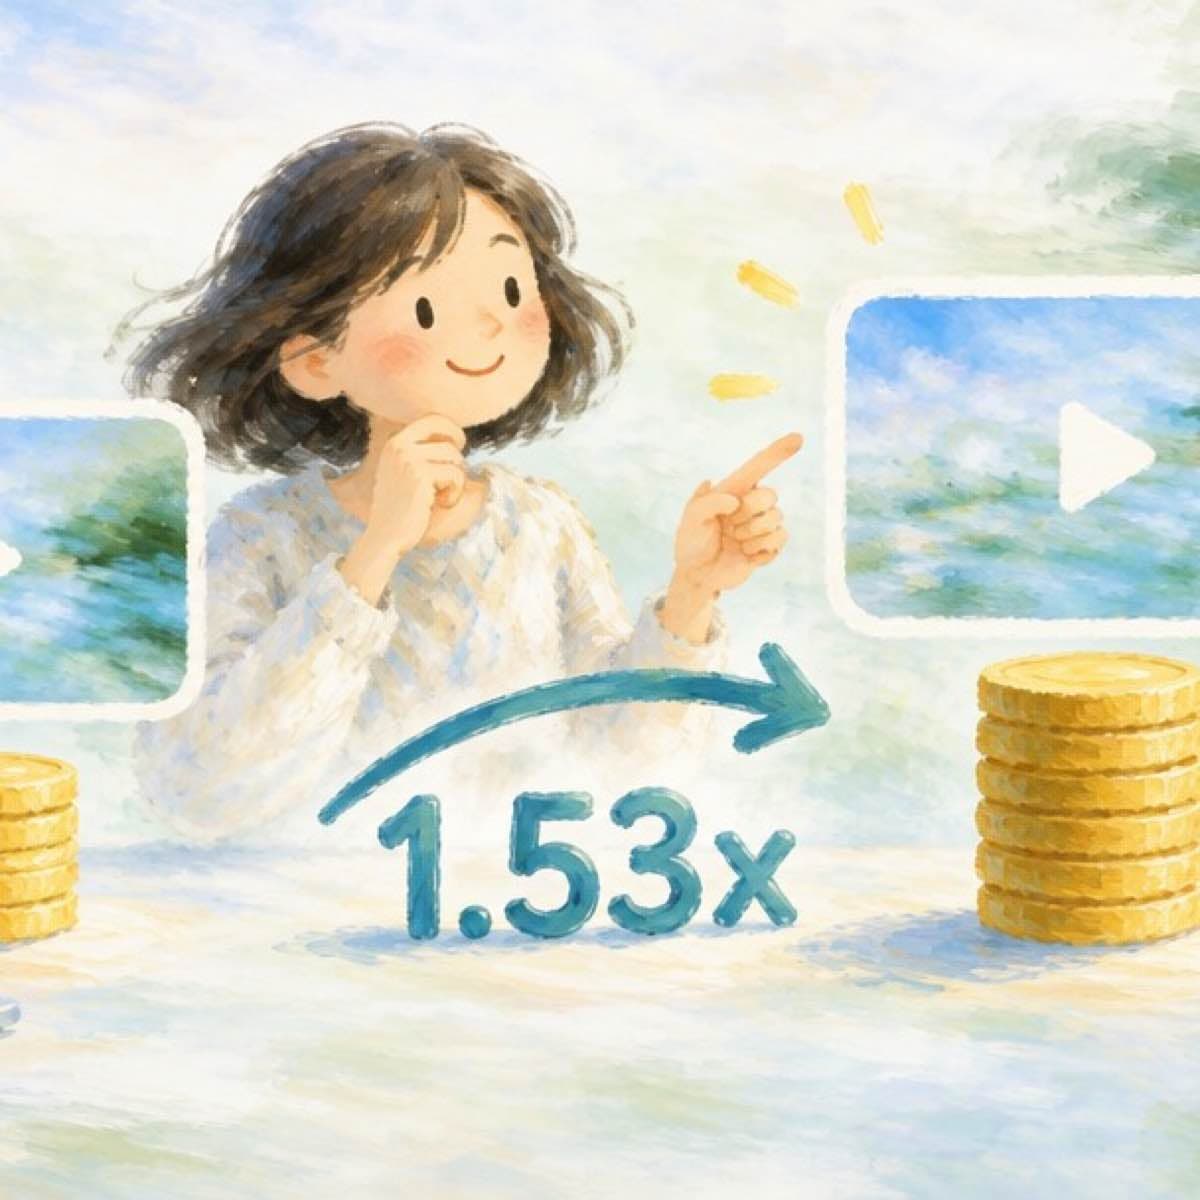
Seedance 2.5 costs 1.53x Seedance 2.0 at 720p for 10 seconds
A 10 s 9:16 clip at 720p is $5.78 on Seedance 2.5 and $3.78 on Seedance 2.0 on Sume. What the extra $2.00 buys, and the ratio at 480p and 1080p.
Is MAI-Voice-2.1 on Sume? What Sume's audio docs list instead
Sume does not list MAI-Voice-2.1 or MAI-Transcribe-2. Here is what its docs do list for speech, transcripts, music and captions, with prices.
AI video with native audio: which Sume models let you turn it off
On Sume, only Kling v3 Pro prices audio separately (+$0.07/s). Gemini Omni and MiniMax always make audio; Grok Imagine and Genjutsu make none. Table inside.
How many aspect ratios each Sume image model lists, vs Hy's 14
Hy Image 3.5 Preview lists 14 aspect ratios. On Sume, Nano Banana 2.1 and Ideogram list 15, Grok and Flux 13, GPT Image 2.5 only 9. Full counts by row.
Hy Image 3.5 lists a 1.5K tier. No Sume image model does
Hy Image 3.5 Preview offers 1K, 1.5K, 2K and 4K. Sume's tier lists are 512, 1K, 2K, 4K or 1K/2K only. For about 1.5K, GPT rows take 1536x1536 as image_size.
Which new text models can a Sume Format run name as model?
Format runs take a catalog id as model. Haiku 5.5, GLM 5.3 Flash and GPT-6 Astra are in Sume's registry; Mistral Large 4 and GLM 5.3 Fast are not.
Gemini Flash-Lite TTS lacks 29 languages that Flash covers
Google's table lists 132 languages for Gemini 3.8 Flash TTS and 103 for Flash-Lite, so 29 are Flash-only, including Thai, Swedish and Finnish. Read 2026-10-08.
How long can a Sume agent run take? Timeouts for slow models
Format runs are finalized at 90 minutes, or after 10 silent minutes once past 25. Agent Completions publish no deadline. Webhooks time out at 10 s per attempt.
MAI-Voice-2.1 ~550 ms vs Flash ~45 ms: does it matter for voiceover?
Microsoft lists ~550 ms and ~45 ms model-inference latency for MAI-Voice-2.1 and Flash. In series, 1,000 lines take 9.2 minutes vs 45 s. Read 2026-10-08.