
Who said what without speaker labels: STT per track, merge by time
Sume STT has no diarization. If each speaker has an own track, transcribe each and merge words by start time into labeled turns. Python, 1 cent a minute.
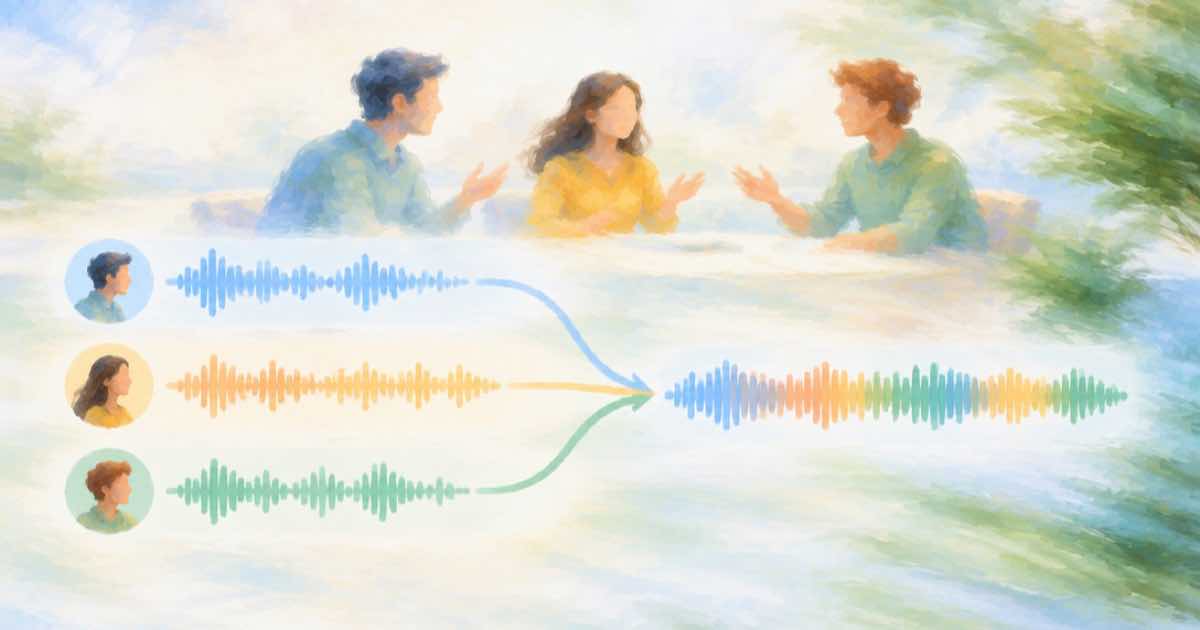
Microsoft's MAI-Transcribe-2 post (read 2026-10-05) is about streaming transcription in 60 languages. If your real need is a meeting transcript with names, there is a simpler route than labeling voices: record each person on their own track. Remote recording tools and most podcast setups give you one file per speaker. Then the speaker label is the file name, and you do not need diarization at all.
What Sume gives you
Sume STT 1.0 fixes diarize and tag_audio_events on the server and rejects them if you send them, so a single mixed file comes back with no speaker labels. Each job returns words[] with start and end seconds from the start of that audio. If all tracks begin at the same instant, the timestamps from different files share one clock. That is what makes the merge possible.
The merge
Transcribe each track as its own job. Tag every word with the track name. Sort all words by start. Start a new turn whenever the speaker changes. A short overlap, where two people speak at once, becomes two alternating one-word turns, which you can join if they are under 0.3 seconds apart.
import os, time, requests
B = "https://api.sume.com/v1"
H = {"Authorization": "Bearer " + os.environ["SUME_API_KEY"]}

def run(path, body, key=None):
    h = {**H, **({"Idempotency-Key": key} if key else {})}
    r = requests.post(B + path, json={**body, "mode": "async"}, headers=h)
    r.raise_for_status()
    job = r.json()["data"]["job"]["id"]
    while not requests.get(f"{B}/jobs/{job}/status", headers=H).json()["data"]["terminal"]:
        time.sleep(3)
    res = requests.get(f"{B}/jobs/{job}/result", headers=H)
    res.raise_for_status()
    return res.json()["data"]["result"]

tracks = {"Ana": os.environ["ANA_URL"], "Ben": os.environ["BEN_URL"]}
allw = []
for who, url in tracks.items():
    res = run("/stt-1.0/transcribe", {"audio_url": url, "duration_seconds": 600})
    allw += [{**w, "who": who} for w in res["words"] if w.get("type") == "word"]
allw.sort(key=lambda w: w["start"])
turns = []
for w in allw:
    if turns and turns[-1]["who"] == w["who"]:
        turns[-1]["text"] += " " + w["word"]
    else:
        turns.append({"who": w["who"], "start": w["start"], "text": w["word"]})
for t in turns:
    print(f"[{int(t['start'] // 60):02d}:{int(t['start'] % 60):02d}] {t['who']}: {t['text']}")
Cost and caveats
- Each track is billed separately at about $0.01 per minute, so a 10-minute interview with two tracks is about 20 cents, and with four guests about 40 cents.
- Each job takes at most 10 minutes. Cut every track at the same offsets if the call runs longer, and add the offset to each word time.
- Bleed from one microphone into another produces words on both tracks. Keep the speaker whose track gives the longer run of words in the same window, or ask for headphones next time.
- If you only have one mixed file, this method does not apply. Sume does not offer labels.
Sources
Related posts
More in Use cases
- AI Shorts lost views after Oct 2, 2026? Diagnose first
Not every drop is the originality update. A diagnosis order for AI Shorts: copied clips, sameness, labels, then ordinary causes, using only what YouTube says.
- Why TTS plus lip-sync avatars feel fake: Griffin's 2.4% vs 48%
Tavus says its older avatar stack passed as human 2.4% of the time and Griffin-Lite 48%. Here is what that means for TTS-then-lip-sync clips.
- Win-back video for lapsed customers: 30-second avatar script, cost
A win-back email clip made with a Sume avatar: what to say in 30 seconds, what not to promise, and the cost per lapsed account on standard, plus and max.
- X carousel ads: 2 to 6 media assets, rendered as one Sume batch
X carousel cards hold 2 to 6 media assets. Make the whole set at one aspect ratio in a single Sume Image API call with n, then check each file.
Written by Sume