
Two reference images, one clip: Omni's cat-and-yarn pattern on Sume
Google's docs show two images, a cat and yarn, producing one video. Here is the Sume request with IMAGE_REF tokens and what changes with a brand product.
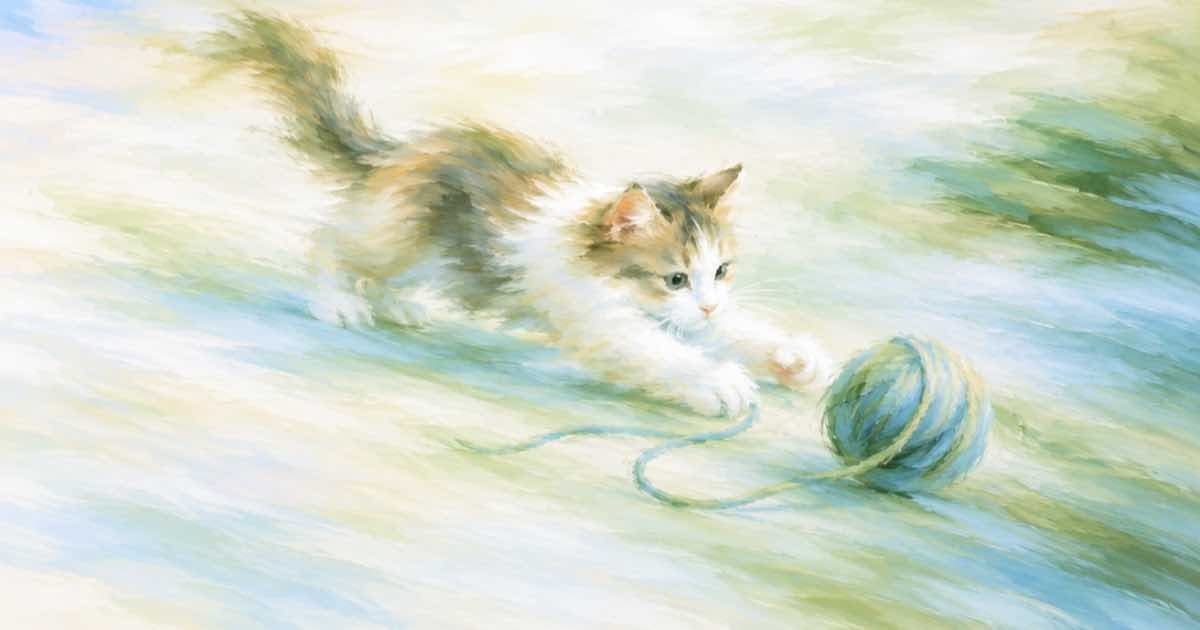
To put two reference subjects in one Gemini Omni Flash 1.1 clip, send both pictures in reference_image_urls and refer to them in the prompt as <IMAGE_REF_0> and <IMAGE_REF_1>. Google's documentation uses a cat and a ball of yarn as the example. The tokens are 0-based, and up to 10 images are allowed on Sume.
What Google shows
The Gemini API docs describe subject reference as generating a video that incorporates specific subjects provided as reference images, and show two PNGs, a cat and yarn, with the prompt "A cat playfully batting at a ball of yarn." (read 2026-10-07). The Google request passes images as input parts and writes no tokens. Sume's reference mode adds the tokens, so the prompt can say which image plays which role.
The Sume request
Reference mode uses reference_image_urls and/or reference_video_urls, with no image_url or video_url in the same request. The prompt names each image by its index.
curl -X POST https://api.sume.com/v1/video-router/generate \
  -H "Authorization: Bearer $SUME_API_KEY" \
  -H "Content-Type: application/json" \
  -H "Idempotency-Key: cat-yarn-001" \
  -d '{
    "model": "gemini-omni-flash-1.1",
    "prompt": "<IMAGE_REF_0> playfully bats at <IMAGE_REF_1> on a wooden floor. Handheld, warm afternoon light.",
    "reference_image_urls": [
      "https://example.com/cat.png",
      "https://example.com/yarn.png"
    ],
    "duration": 6,
    "resolution": "720p",
    "mode": "async"
  }'
Swap in your own subject and prop
The pattern is subject plus object, so it carries over to a person and a product, a mascot and a prop, or a pet and a toy. Use one clean image per subject, on a plain or neutral background, so the model does not carry the old background into the clip. State the interaction in the prompt in one verb phrase; the cat example is "playfully batting", and a clear verb gives the model something to animate.
| Resolution | Per second | 6 seconds |
|---|---|---|
| 360p | $0.0375 | $0.225 |
| 720p | $0.125 | $0.75 |
| 1080p | $0.1875 | $1.125 |
Camera and motion
Reference mode is subject-driven, so the prompt carries the camera. Say "handheld", "static" or "slow push-in" once, and say where the action happens. If you leave the setting out, the model fills it from the images, which can pull the background of one picture into the whole clip. A neutral location named in the prompt, such as a wooden floor in afternoon light, keeps the reference backgrounds from leaking in.
Six seconds is long enough for one beat of action. A cat bats at yarn, the yarn rolls, the cat follows. Asking for a story with three events in 6 seconds produces rushed motion.
When it goes wrong
If the prompt says nothing about which image is which, the model may merge them. If a token points past the end of the list, the request is a mistake in your payload, not a creative problem; keep the list and the prompt in the same file so you edit them together. More than 10 images is rejected, and so is more than 3 reference videos; the reference error cases list the messages. Native audio is on and cannot be turned off, so even a silent-looking subject gets sound. Run a 360p draft first at $0.225 for 6 seconds to see whether the two subjects read as separate things.
To reuse the same character across a whole sequence, see reference clips of three seconds each.
Sources
Related posts
More in Models
- Video edit prompt: say what stays, then what changes (Omni Flash)
A prompt pattern for Gemini Omni Flash 1.1 video edit on Sume: one change per pass, an explicit keep clause, and what the video_url route fixes for you.
- Does Wan 3.0 do 4K? Claim check against vendor pages and Sume
Alibaba lists 480p, 720p and 1080p for Wan 3.0, Morphic says no 4K, and Sume rejects 4k for wan-3.0. Where 4K exists on Sume and at what clip length.
- Wan 3.0 document-to-video claim vs what Sume accepts as reference
Alibaba says Wan 3.0 reads PDFs, slides and docs. Sume's catalog lists image, video and audio references for it, not documents. Read the field before you plan.
- Wan 3.0 same-face test: eight 480p takes for $3.04 before 1080p
Alibaba says Wan 3.0 avoids same-face AI people. Test that claim on Sume with eight 6-second 480p takes at $0.38 each, then render only the best at 1080p.
Written by Sume