
Transcribe a 30-minute video: three 10-minute detaches and STT, $0.33
A 30-minute file is too long for one detach or one STT call. Cut three 10-minute audio ranges at $0.01 each, then transcribe each at $0.01 per minute: $0.33.
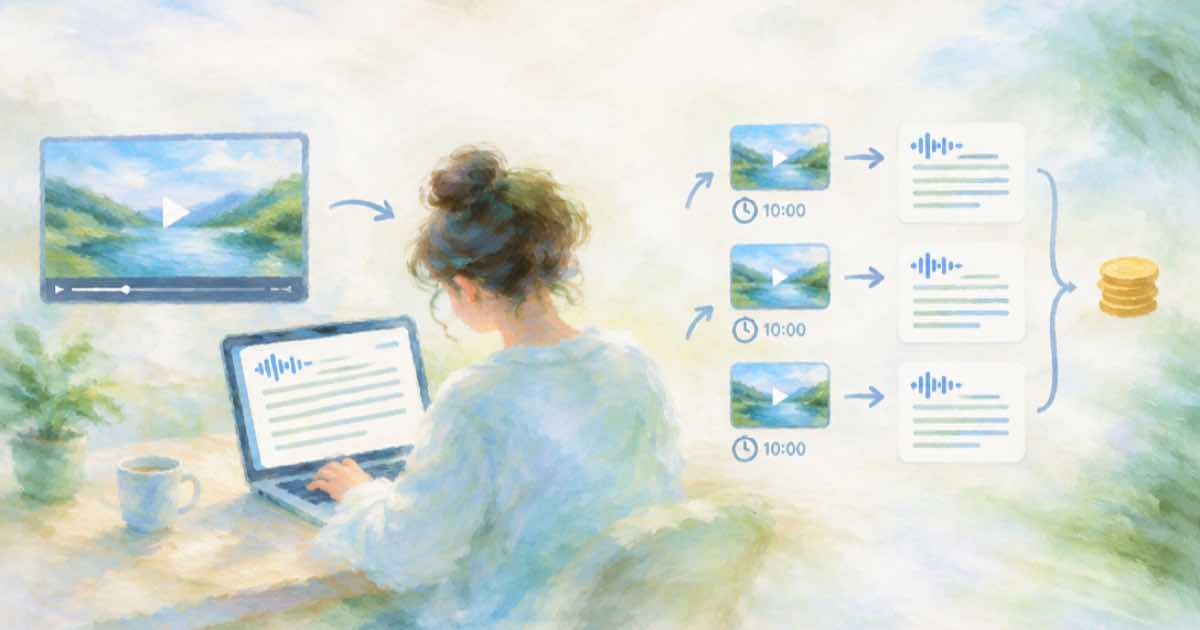
Detach the audio in three 600-second ranges, then send each to speech-to-text. A 30-minute video then costs three detaches at $0.01 each plus 30 transcript minutes at $0.01, so $0.33 at the public rates in the docs. One detach cannot do it in a single pass: output is capped at 900 seconds, and the speech-to-text duration hint at 600.
Why three ranges
Audio detach accepts a source up to 1,800 seconds, but its output is limited to 900 seconds, and a whole track longer than that needs a range. STT's duration_seconds hint runs from 1 to 600. Cutting the 1,800 seconds into 0 to 600, 600 to 1,200 and 1,200 to 1,800 satisfies both caps and keeps each reservation tight. Ask for 16 kHz mono wav: the docs name that as the STT shape. Ranges are in seconds from the start of the source, and the last range may simply end at the true duration.
Send the three detaches
Each job needs its own idempotency key. The script prints three job ids; poll each with jobs and read audio_url from the result. Each range is open to the next one, so there is no overlap to merge, and you add 600 or 1,200 to the word times of the second and third parts.
import os, requests
B = "https://api.sume.com"
H = {"Authorization": "Bearer " + os.environ["SUME_API_KEY"]}

def main():
    src = "https://media.sume.com/artifacts/artf_demo/talk-30min.mp4"
    for i in range(3):
        body = {"video_url": src, "format": "wav", "channels": "mono", "sample_rate": 16000,
                "range": {"start": i * 600, "end": (i + 1) * 600}}
        r = requests.post(B + "/v1/audio-detach", json=body,
            headers={**H, "Idempotency-Key": "talk-detach-" + str(i)})
        r.raise_for_status()
        print(i, r.json()["request_id"])

if __name__ == "__main__":
    main()
Then transcribe each part
Post each audio_url to POST /v1/stt-1.0/transcribe with duration_seconds 600 and segmentation mode sentence if you want caption-style lines. Words come back with start and end times relative to that part, so shift them by the range start. Check probe.has_audio first with a video_inspect that sets frames to false; a silent file fails detach with detach_source_has_no_audio.
| Item | Count | Rate | Total |
|---|---|---|---|
| audio_detach (600 s ranges) | 3 | $0.01 per job | $0.03 |
| STT audio minutes | 30 | $0.01 per minute | $0.30 |
| Whole job | $0.33 |
Stitching the transcript back
Add the range start to every word and segment time from parts two and three, then concatenate the lists in order. A sentence that straddles a boundary will appear as two fragments, one at the end of a part and one at the start of the next; join them when the gap is under a second and the first lacks end punctuation. If you need caption lines, request sentence segmentation on each call and merge afterward.
What this excludes
The $0.33 leaves out any import fee for getting the file into your workspace and any wallet or price-book adjustments. It is a floor for planning, and the live numbers are in GET /v1/catalog. Keep each part's job id with its range, so a missing part is easy to re-run alone under the same key. If a part fails with detach_start_past_source, the file is shorter than you assumed, so probe it first and size the ranges to the real duration.
Sources
Related posts
More in Use cases
- Translate a product label in place into 4 languages with Ideogram 4.5
Swap approved label copy per market with one Ideogram 4.5 edit each on Sume: a copy-deck prompt, $0.15 for four languages at low, and a proofing list.
- Translate chart and diagram labels in an image with Ideogram 4.5
Swap the axis titles, legend and callouts of a chart image into another language with one Ideogram 4.5 edit per language: $0.0375 each at low on Sume.
- Translate your comic's speech bubbles: one Ideogram 4.5 edit per page
Letter a 20-page comic in 3 languages with Ideogram 4.5 edits on Sume: one call per page, 60 calls, $2.25 at low quality, and why per-bubble calls cost 6x.
- Translate small print on a pack: edit the panel crop, paste it back
For ingredient-panel small print, crop the panel, send only the crop to an Ideogram 4.5 edit at high quality, and paste it back with Pillow. Proof every word.
Written by Sume