
Griffin-Lite study: 81% confident about the AI, 79% about people
Tavus reports participants were 81% confident about the AI and 79% about real people. Confidence did not track the truth, so label AI avatar clips yourself.
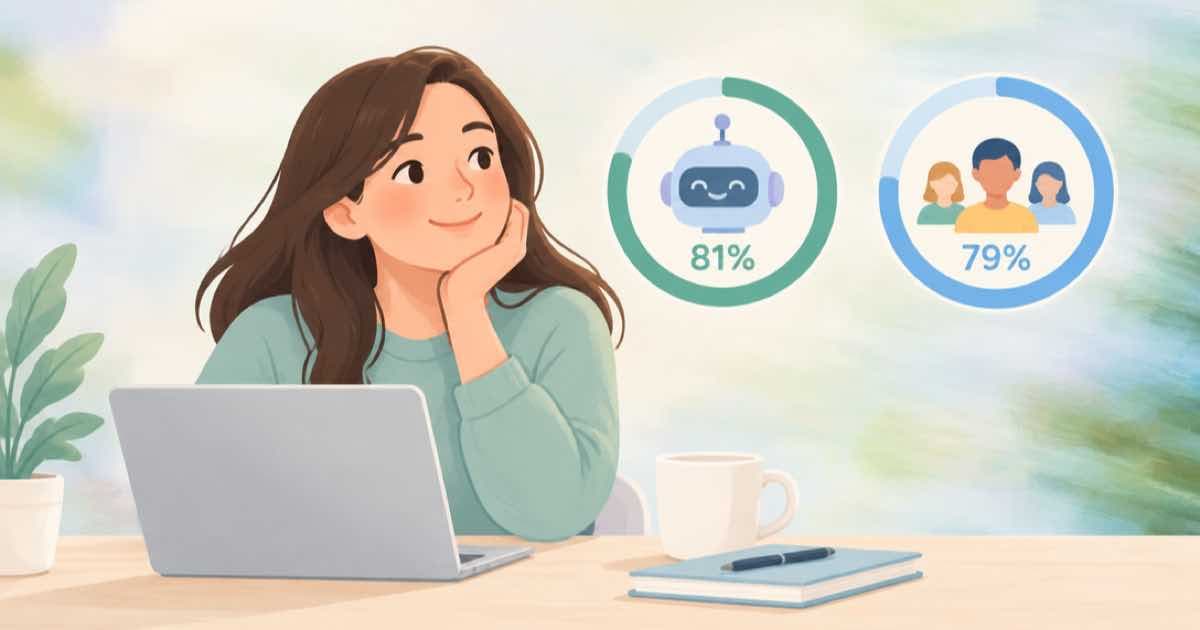
Tavus's Griffin page says participants averaged 79 percent confidence about real people and 81 percent about the AI. So when people judged whether they had talked to a person, their stated confidence was no lower when they were wrong. If viewers cannot tell by feel, any rendered avatar clip you publish should say what it is.
What the page reports
The figures are from the Griffin announcement, read on 2026-10-07. The study had 54 participants for Griffin-Lite, and 48 percent believed they had spoken with a real person after a one-minute video call.
| Measure | Value |
|---|---|
| Participants (Griffin-Lite) | 54 |
| Believed AI was a real person | 48% |
| Average confidence, real partners | 79% |
| Average confidence, AI partners | 81% |
| Prior model (Phoenix-4.5) believed real | 2.4% (n=41) |
Why this matters for a clip
A rendered clip is not Griffin. Griffin-Lite is a research preview for select testers and, per the page, not available to customers. But the finding is about people, not the model: confident viewers can be wrong, so a disclosure should not rely on them noticing.
On Sume you control the words and the caption cues. The avatar video guide documents inline captions with an optional script_text, which pins the on-screen copy. You can write a short AI-generated line into the script, or into the first caption, rather than hoping a viewer reads the face.
What I would do
Put the label where it cannot be missed: in the spoken script or the opening caption. Keep a record of the job id that made each clip. Regulatory rules vary by country and platform, so check the current rule for the channel and region before you publish, and treat this post as no legal advice.
If a sample of 54 people shows a 48 percent pass rate, the interval is wide. Do not turn it into a rule of thumb about your audience.
What Griffin-Lite is not
Per the Tavus page, Griffin-Lite is a research preview offered to a select group of early testers, and a wider release depends on safety work. You cannot book it, and a Sume avatar clip is not a Griffin output. This post uses the study only as evidence about viewers.
Sources
Related posts
More in Sume Avatar 1.0
- 10 products, one 18-second avatar clip each: cost with a product image
Ten 18-second Avatar Video clips cost $33.12 at standard, $44.10 at plus and $99.00 at max; a product image adds $1.80 on standard.
- UGC testimonial ad with an avatar: 10 variants of 15 s cost $27.60
A 15-second talking-head UGC ad costs $2.76 on Sume's Standard avatar tier, $3.68 on Plus and $8.25 on Max. Ten script variants cost $27.60, $36.75 or $82.50.
- What a scripted AI avatar clip cannot do: seven limits and fixes
A Sume avatar clip cannot take questions, run past 60 seconds or switch presenter mid-video. Seven documented limits, each with a workaround.
- Introducing Sume Avatar 1.0
Sume Avatar 1.0 is a multi-agent orchestration system as a single avatar model.
Written by Sume