OpenAI webhook retries (72 hours) vs Sume (10 attempts): what changes
OpenAI retries a failed webhook for up to 72 hours; Sume tries 10 times, 30 seconds apart. Rebuild the receiver around an inbox, job-id dedupe and polling.
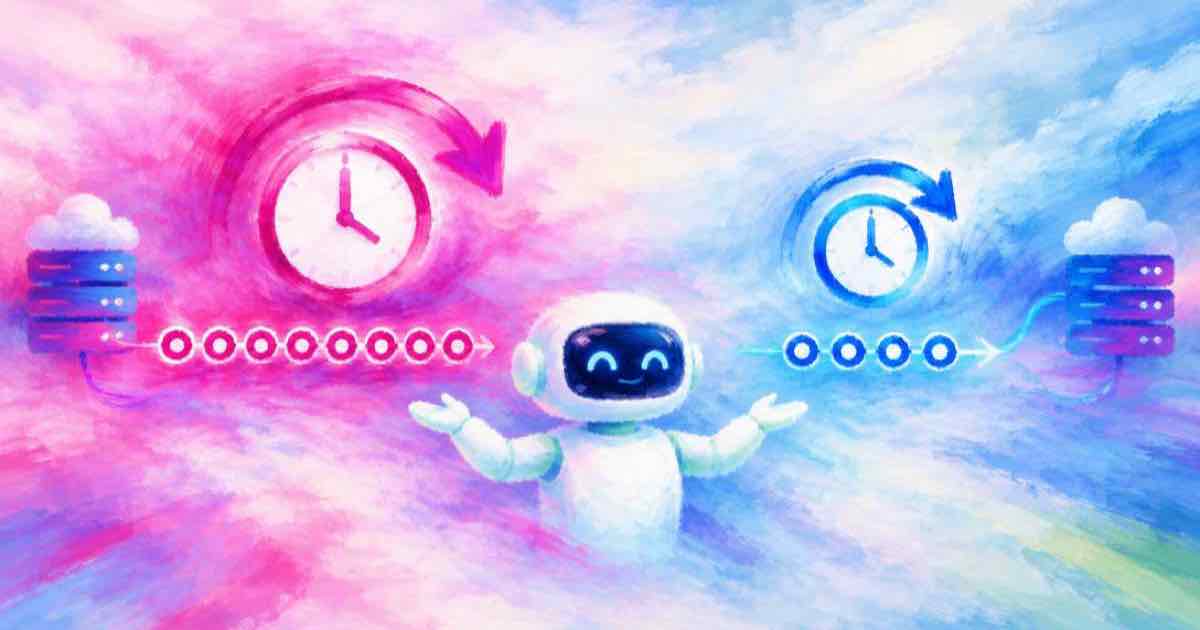
OpenAI's webhooks retry a failed delivery for up to 72 hours with exponential backoff, while Sume makes up to 10 attempts spaced 30 seconds apart, about 4.5 minutes of spacing in total. If your Sora receiver was allowed to be down overnight and still catch up, it will need a poll fallback or a redelivery call on Sume.
The delivery rules
Read the comparison as a change in your obligations, not as one vendor being better. A long retry window lets a lazy receiver survive; a short one asks for a receiver that records the event on the first successful call and never loses it afterwards.
| Property | OpenAI | Sume |
|---|---|---|
| Retry window | Up to 72 hours, exponential backoff | Up to 10 attempts, fixed 30 second spacing |
| Per-attempt timeout | Respond with 2xx quickly | 10 seconds |
| Dedupe key | webhook-id header | job_id in the payload |
| Signature headers | webhook-id, webhook-timestamp, webhook-signature | x-sume-webhook-timestamp, x-sume-webhook-signature |
| Manual redelivery | Not covered in the guide | POST /v1/jobs/{job_id}/webhook/redeliver |
| Duplicates | Possible | Dedupe on job_id |
Event names changed too
OpenAI's webhooks guide, read 2026-10-07, does not mention video events, while the Sora guide named video.completed and video.failed. Since the Videos API is shut down, treat those event names as history. Sume's equivalents are job.completed, job.failed and job.canceled, with a payload carrying request_id, job_id, a status of OK or ERROR, and an artifacts list.
Rebuild the receiver around an inbox
A receiver that assumed three days of retries should stop doing real work inside the request. Accept, verify, write to a table keyed by job_id, return 2xx, and process from the table.
The inbox pattern costs little. One table with job_id as the primary key, the raw body, a received_at time and a processed flag is enough. A worker loop selects unprocessed rows, does the download or encode, and flips the flag, so a crash halfway repeats the work instead of dropping it.
- Verify the signature over the raw body before parsing JSON.
- Insert with a unique constraint on job_id; ignore duplicates.
- Return 2xx inside the 10 second timeout, then do the download or encode.
- Run a sweeper that calls GET /v1/jobs/{id} for any job without an event after a few minutes.
After an outage
A receiver outage longer than the 4.5 minutes is not data loss. The job result stays readable by polling, and the redeliver route replays the event after you fix the endpoint. See jobs and results for the status fields and the webhook docs for signing.
Pair it with a sweeper that runs every few minutes and polls any job older than your expected render time that has no event. With both paths in place, a delivery that never arrives costs you a few minutes of latency instead of a missing video.
Or skip webhooks
For a worker that handles a handful of clips a day, polling alone is simpler; the pick-by-job-count post draws that line.
Sources
Related posts
More in Comparisons
- OpenRouter video client on Sume: six documented differences
Sume says /v1/videos matches the OpenRouter Video Generation API except six items: base path, auth, model ids, auto routing, size and provider.options.
- Pick an image model by job: product photo, poster text, edit
Five new image releases in a month. A job-first table for Sume: GPT Image 2.5, Ideogram 4.5, Nano Banana 2.1, FLUX.2 and Qwen, with the limits that decide.
- Sora API shutdown report: which claims Sume docs can answer
Pondero's Sora API shutdown report names Runway, Kling and Seedance. Sort its claims from what Sume's docs list, so you do not assume a model is there.
- Precise image editing on Sume: what it has and what it lacks
A plain list of what Sume offers for precise edits after Flux 3 Image and Ideogram 4.5: no Flux 3, no box field, mask_url on one model, Ideogram 4.5 present.
Written by Sume