
One TTS job per sentence, then a gapless concat: the Sume recipe
Generate narration one sentence at a time with tts_create, then join the takes with timeline audio. Fix one line without redoing the rest.
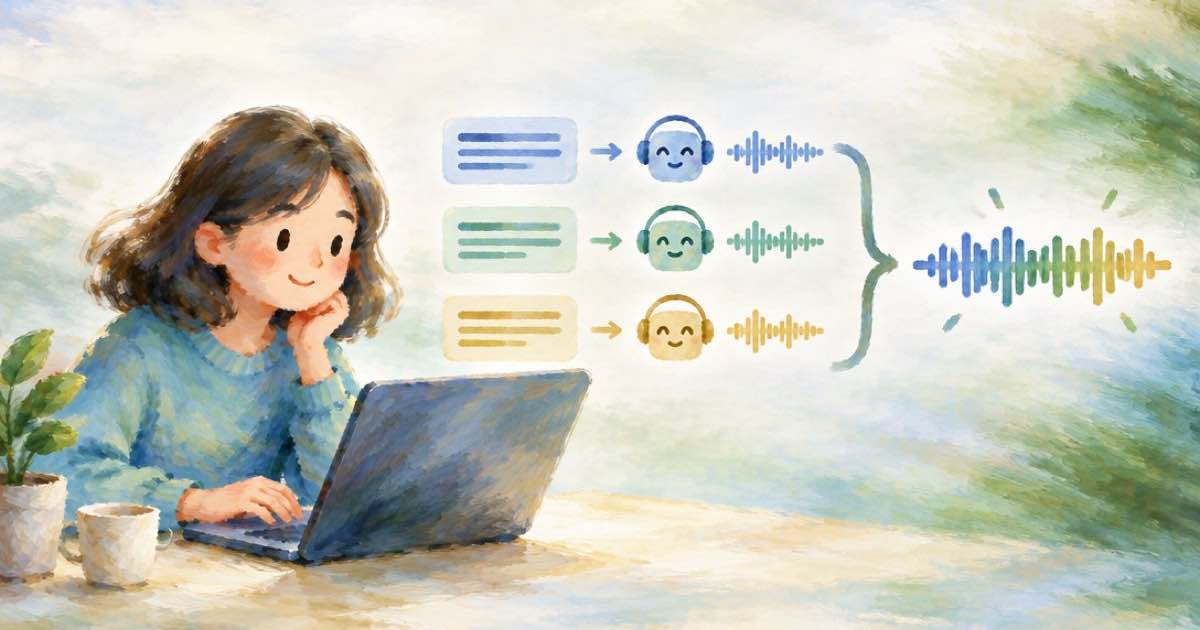
Make narration one sentence per job, then join the takes with Sume timeline audio. The MCP docs use tts_create per sentence as their example of a loop worth running in a script. The join is sample-domain, with no re-TTS and no silence at the seams, so a line you redo later does not force the rest of the narration to be regenerated.
The flow
| Step | Call | Cost note |
|---|---|---|
| 1. Speak each sentence | tts_create per sentence (up to 20000 characters per job) | Priced per transcript character; check GET /v1/catalog |
| 2. Join takes | POST /v1/timeline-1.0/audio, operation: concat | $0.01 flat per job |
| 3. Use the file | audio.url in Timeline 1.0, or Avatar 1.0 audio | Per those pages |
Why per sentence
A single long job gives you one take. If sentence seven is wrong, you redo the whole job. Per-sentence jobs let you regenerate only line seven and join again. The concat has a 20-part limit, so a script over 20 sentences needs two joins, then a final join of the two outputs: 2 + 1 = 3 jobs, or $0.03 for the joins.
Sume also gives free read tools for scripts that must match an accepted text: tts_source_get returns the accepted-script manifest for tts_create with transcript_source, and tts_source_verify_spine compares the selected TTS jobs with the accepted script.
Keeping the voice the same
A completed text-to-speech job records model_id, voice ({ "mode": "id", "id": "..." }), language, output_format, generation_config and speed. Each is null if the request did not send it. Read these values from the first job and reuse them for later lines so the voice stays consistent across takes.
Channel layout
All parts you concat must share a channel layout, or the worker returns audio_parts_channel_mismatch. Generate every line with the same output settings, and keep wav through the join as the docs advise. Microsoft's announcement lists MAI-Voice-2.1 at $22 per 1M characters (read 2026-10-08); Sume does not list that model, so the flow above applies to the TTS Sume does list.
Sources
Related posts
More in Media tools
- Price plate over a product clip: Timeline compose overlay, $0.02
Sume Timeline compose overlay puts a price plate image on a product clip for $0.02. Width_ratio 0.05 to 1, margin_ratio 0 to 0.45, and the stack-key error.
- Do punch and tiktok-green captions accept design overrides? No
In Sume video captions, punch and tiktok-green do not support design: they render on a path that reads none of the tokens. Use another style to tune.
- Brand-color captions: punch and tiktok-green skip design
Sume's docs say punch and tiktok-green read none of the design tokens. To change a caption color per request, use slam or a Hangul style. Token groups.
- Recipe reel from 6 step clips: video trim exact or keyframe, $0.12
Cut six cooking steps from one kitchen take with Sume video trim: exact re-encode or keyframe copy, $0.02 per cut, then one $0.10 Timeline render. Total $0.22.
Written by Sume