Micro-drama key art: one character anchor and 12 9:16 stills, $0.21
Plan a vertical micro-drama with stills first: one GPT Image 2.5 anchor plus 12 reference-guided 9:16 frames is $0.2075 on Sume; Seedream 5 Lite is $0.56875.
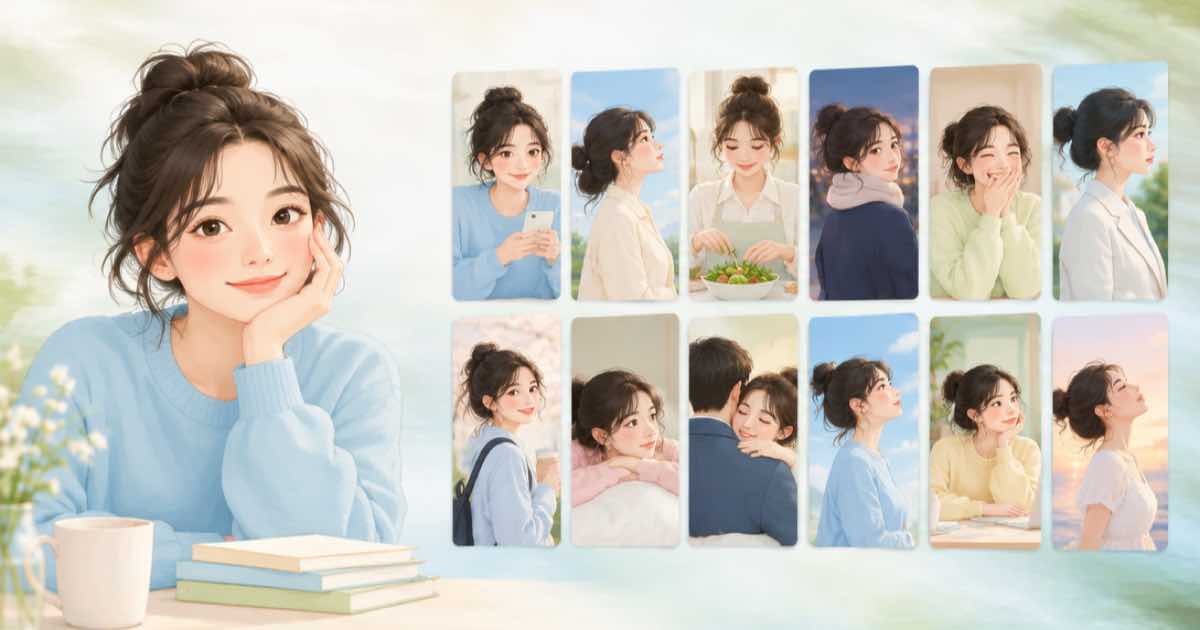
Short vertical micro-dramas are reported to be rising across TikTok, Reels and Shorts (HeyOrca's social news roundup, read 2026-10-07). Before anyone pays for video, the cheapest way to lock a look is a set of stills: one anchor image of the lead, then a frame per beat that uses the anchor as a reference.
On Sume that is two kinds of POST /v1/images call. The anchor is one portrait. The beats are 9:16 edits that send the anchor in input_references. openai/gpt-image-2.5 takes up to 16 references; most other edit-capable models take up to 10.
Cost of the plan
Prices here are Sume's list-times-1.25 figures. The catalog states the billable formula as "list × 1.25 → ceil usd cents", so treat the dollar amounts as the pre-rounding value and read the exact charge from billable_amount_usd_micros in the submit envelope. Failed or cancelled generations are not billed.
| Step | Model and setting | Count | Each | Subtotal |
|---|---|---|---|---|
| Character anchor, 2:3 portrait | openai/gpt-image-2.5, high, 1024x1536 | 1 | $0.0515 | $0.0515 |
| Beat frames, 9:16 | openai/gpt-image-2.5, medium, 1088x1920, anchor as reference | 12 | $0.013 | $0.156 |
| Whole plan | 13 | $0.2075 | ||
| Alternative: all 13 on Seedream 5 Lite | bytedance-seed/seedream-5-lite, 9:16 | 13 | $0.04375 | $0.56875 |
Why 1088x1920 and not 1080x1920
On GPT Image 2.5, custom pixels need both edges to be a multiple of 16, and 1080 is not. 1088x1920 is the nearest legal 9:16 box; crop the 8 extra columns when you assemble the timeline. Seedream accepts the 9:16 ratio directly.
Send the same anchor with every beat prompt and keep one sentence of wardrobe and setting in each, so the model has the same words to anchor on. Run the 12 frames as separate requests with mode: "async" if you want them in parallel; they are independent jobs.
A beat frame request
{
  "model": "openai/gpt-image-2.5",
  "prompt": "Same woman, night kitchen, she reads a text and goes pale. Vertical, cinematic.",
  "quality": "medium",
  "image_size": { "width": 1088, "height": 1920 },
  "input_references": [
    { "type": "image_url", "image_url": { "url": "https://example.com/anchor.png" } }
  ]
}
Reference URLs must be public HTTPS; Sume rejects localhost, private-network and non-HTTPS URLs before submitting. Sources: Sume Image API docs and HeyOrca (read 2026-10-07).
Sources
Related posts
More in Use cases
- Micro-drama season of 40 one-minute episodes: cost by Sume model
Micro-dramas are rising on TikTok, Reels and Shorts. Forty 60-second episodes in 9:16 priced on Omni, Wan, Kling, MiniMax H3 and Seedance, with the catches.
- Microscope-style science clip with Gemini Omni Flash: prompt and cost
Google's own Omni 1.1 demo prompt is a diatom micrograph. Here is how to write one, draft it at 360p, and what 8 seconds costs on Sume at each resolution.
- Midday to golden hour in a video: Omni edit or first/last frame
Change the time of day in a clip you already have. When a Gemini Omni Flash edit fits, when first and last frames fit, and what a 6-second pass costs on Sume.
- Mobile pet groomer reel from one photo: Seedance 2.5 image-to-video
Turn one photo of a groomed dog into a vertical reel clip with Seedance 2.5 on Sume: first-frame input, 4 to 30 seconds, native audio, async job.
Written by Sume