Chain TikTok mini-drama episodes: last frame in, first frame out
Pull the final still of episode one with Sume video frames, then send it as first_frame for episode two so the next shot starts where the last ended.
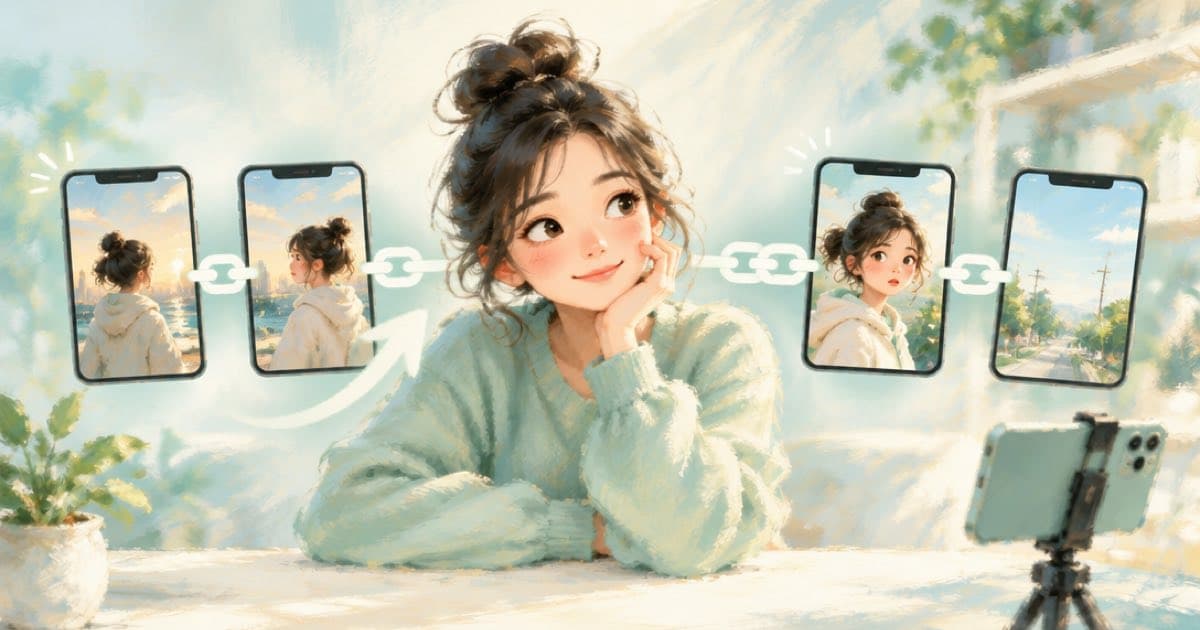
To chain two mini drama episodes, extract the last still of episode one with POST /v1/video-frames, then pass it as a first_frame in frame_images on episode two's POST /v1/videos request. The new episode opens on the exact set, light, and pose where the last one stopped. The frames call must use a time strictly less than the clip duration, so probe the length first.
TikTok runs a dedicated short-drama app, PineDrama, which calls itself "TikTok's official drama app".
Step 1: find the end of episode one
Video frames takes at[] (1 to 24 values, each 0 <= t < duration) and returns durable image artifacts at the source size. A value at or past the end fails with frame_time_out_of_range and the error gives the duration it probed.
Probe first with Video inspect and frames: false, which returns the duration. Then ask for a time a fraction of a second before it, such as duration - 0.1. The source must be 300 seconds or shorter for Video frames, and the job always returns 202, so poll it.
Step 2: start episode two from that frame
The Video generation docs define frame_images as first or last frame images for image-to-video, each with a frame_type of first_frame or last_frame. Check that your model lists first_frame in supported_frame_images via GET /v1/videos/models. The docs show seedance-2 with both first and last frame.
If you also send input_references, frame_images controls the mode and the request is processed as image-to-video, so keep character references for a separate shot.
{
  "model": "seedance-2",
  "prompt": "Camera holds on her face as the door behind her opens; she turns slowly",
  "frame_images": [
    {
      "type": "image_url",
      "image_url": {"url": "https://media.sume.com/artifacts/artf_demo/ep1-last.jpg"},
      "frame_type": "first_frame"
    }
  ],
  "aspect_ratio": "9:16",
  "resolution": "720p"
}
What carries over and what does not
A still carries pose, framing, and light. It does not carry voice or motion momentum, so write the first line of dialogue to start from rest. Characters can drift in later frames, so spot-check with a few stills.
Because no v1 model accepts seed, you cannot re-render a chain link identically. Save every take you like.
| Step | Call | Watch for |
|---|---|---|
| Probe duration | POST /v1/video-inspect, frames: false | Needs a media.sume.com clip |
| Extract last still | POST /v1/video-frames, at: [duration - 0.1] | frame_time_out_of_range if too late |
| Start next episode | POST /v1/videos with frame_images | Model must list first_frame |
| Compare | Inspect stills of both clips | Face and wardrobe drift |
Check the chain before you scale it
Chaining gives continuity of the opening picture, not of motion. The next episode starts from the same frame but the model decides what happens next, so characters can move differently than you expect. Review each handoff by looking at the first two seconds of the new episode next to the last two seconds of the old one.
Keep the prompts short and describe only what changes in the new episode, since a long restated prompt can pull the scene away from the frame you supplied. Remember that input_references cannot be combined with frame_images for a reference-driven look, because frame_images takes over the mode.
Because no v1 model accepts a seed, a failed handoff has to be re-rendered, not nudged. Budget for a second attempt on any episode where continuity matters, and keep the job ids in your ledger so you know which take shipped.
Sources
Related posts
More in Developers
- Chapter timestamps for narrated audio from concat segment offsets
Join one TTS file per chapter with timeline audio concat, then turn the returned segments[] start offsets into mm:ss chapter lines with a short Python script.
- Check a reference image URL before sending it to Sume Images
Sume rejects localhost, private-network and non-HTTPS reference URLs before submission. A short Python pre-flight check that catches them first.
- Check an Omni edit kept the rest of the clip: video-frames pairs
Compare stills from the source and the edited clip at the same timestamps with video-frames on Sume. A script that submits both extracts, plus what to look for.
- Check MiniMax H3 reference limits before you submit: a Python guard
Sume's minimax-h3 rows take up to 9 images, 3 videos and 3 audios, 12 in all, and audio cannot be the only reference. A 20-line Python guard catches it.
Written by Sume