Test several caption looks on one video without re-transcribing
Send source_caption_id with a new style to re-burn a video's captions in a different look. No second speech-to-text; each variant is still a $0.20 render.
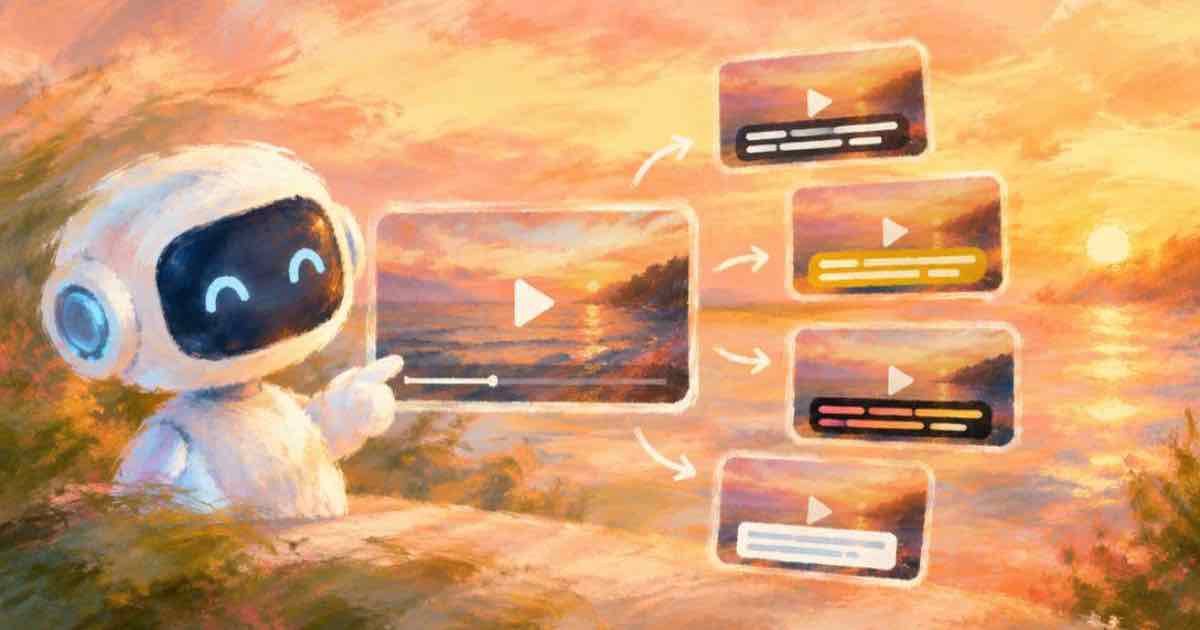
To test several caption looks on the same video, create the first caption job with video_url, then send source_caption_id with a different style for each variant. Sume reuses the source video and the word timings it already has, so speech-to-text does not run again. The price does not drop, because a restyle is still a render at $0.20 per job.
The styles to compare
| Style | Note from the docs |
|---|---|
slam | Default for Latin text when no style is sent |
punch | Selectable by name |
tiktok-green | Selectable by name |
black-outline | Default for Korean text when no style is sent |
clip-wipe | Each word wipes in left to right; the docs call it the clearest at small phone sizes |
korean-ad | CapCut-style karaoke for Korean speech; use with language: "ko" |
The request
The first job takes video_url and optionally style, font, language, design and one of script_text, words, cues or segments. Every later variant is { "source_caption_id": "...", "style": "black-outline" }. Send words with it only to correct the text.
If you do not send a style at all, the caption text picks one: slam for Latin text. If you pick a style yourself, Sume renders that style, and a Latin style with Hangul text is a 400, not a silent fallback.
Fine tune with design overrides
design overrides the style's tokens for one request: colors, typography, placement, phrasing and motion. One key changes one thing, so an accent color test is a one-key request rather than a new style. If you do not send a style, the render has no accent color at all; a default style keeps its own gold tint.
A practical test plan is to change one thing at a time. Keep the text and timing fixed, vary only the style across the first round, then keep the winner and vary one design token in the second round. Because every variant is its own job with its own Idempotency-Key, you can run them in parallel and discard the ones you do not publish.
What a test costs
Four looks on a clip of 60 seconds or less is one first job plus three restyles, four renders at $0.20, so $0.80. Give each its own Idempotency-Key, poll each job, and compare the results on the platform you publish to. Sume tells you what rendered, not which look performs, so the measurement is yours.
If you already have a transcript from another source, skip speech-to-text entirely: send words for word-level timing or cues and segments for phrase-level cards. That is also the route for silent clips, where there is nothing to transcribe. Only one of script_text, words, cues and segments is accepted in a request.
Sources
Related posts
More in Use cases
- Car detailing before-after clip: first and last frame on Seedance 2
Use a dirty-car photo as the first frame and a finished-car photo as the last frame in one Seedance 2 job on Sume. Limits, request body, and what to check.
- One caption per carousel slide: get a typed list from a Sume Format
Write a separate caption for each carousel slide by binding an output_schema to a Sume Format run, so your app gets one typed caption per image.
- Change one of three identical bottles: position words or a mask
Edit one of three identical products in a photo. Flux 3 Image gives each element an id; on Sume, use position words (Ideogram 4.5) or a GPT Image 2.5 mask.
- Change prices on a chalkboard menu photo with Ideogram 4.5
Update dish prices on a chalkboard menu photo with ideogram/ideogram-v4.5: list old and new text, one change set per call, check each digit. $0.075 at medium.
Written by Sume