
14-page read-aloud video: per-page TTS, one concat, page-turn offsets
Narrate 14 pages of 160 characters with Sume TTS ($0.11), join for $0.01, set page starts from segments[]. About $0.32 with a 2-minute render.
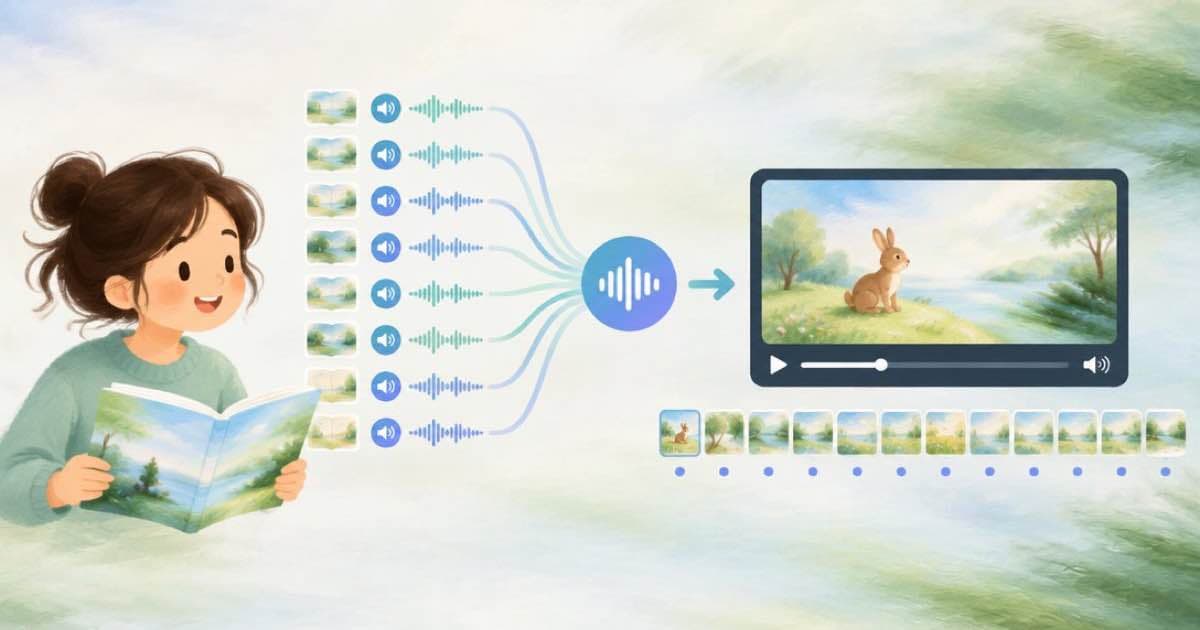
For a 14-page read-aloud video, make one Sume TTS job per page, join the 14 files with one timeline audio concat, and use the returned segments[] starts as each page image's video[].start in a Timeline render. At 160 characters a page the voice costs 2,240 x $0.0475 / 1,000 = $0.106, the concat $0.01, and a 2-minute render $0.20, about $0.32 in all.
Why one job per page
A page turn has to land on a known second. If you narrate the whole book in one TTS job you must find the page boundaries afterwards. If you narrate per page and concatenate, the concat result gives the exact start and duration of every page. The concat is sample-domain, with no silence at the seams, and 14 parts is inside the 20-part cap.
| Step | Quantity | Arithmetic | Cost |
|---|---|---|---|
| TTS, 14 jobs | 2,240 characters | 2.24 x $0.0475 | $0.106 |
| Timeline audio concat | 1 job, 14 parts | flat | $0.01 |
| Timeline render | assumed 8 s per page = 112 s, reserves 2 min | 2 x $0.10 | $0.20 |
| Total | $0.316 |
Building the slots
Each page image is a Timeline video[] slot. Stills are static holds: a slot with a still and a duration stays on screen for that time. The first slot must start at 0, later starts must increase, and the last slot can stop at most 0.5 seconds before the end of the spine. Set video[n].start to segments[n].start and video[n].duration to segments[n].duration_seconds, so that every page changes exactly when its sentence ends.
Add a fade transition of 0.25 seconds on slots after the first for a soft page turn; the transition duration must be at most 1 second and at most half of the shorter neighbouring slot.
Details that bite
Four details decide whether the page turns sit on the right syllable.
- Use the same voice, language and output format for every page, or the concat can fail with
audio_parts_channel_mismatch. - Use wav for the page files. The docs warn that mp3 adds priming padding at every edge, which becomes a small gap at each page boundary.
- Import the page images and the audio to media.sume.com first; Timeline reads only this workspace's files.
- The 8 seconds per page is an assumption. Use the real concat duration in
audio.duration_seconds, and re-check the reserve with the unbilled plan call.
If a page is much longer than the rest
Pages do not need equal lengths, and the concat does not care: each part keeps its own duration. A page that runs long just holds its still longer. If one page is under 0.2 seconds long it cannot be a slot, because a video[] duration must be at least 0.2 seconds, so merge a one-word page into its neighbour before you narrate it. Keep a record of the page number against each segments[] index; the concat output lists them in order, and that order is the only link between the audio and the picture.
A note on engines
Microsoft's MAI-Voice-2.1 lists audiobooks and voice-over among its uses at $22 per 1M characters, which would put these 2,240 characters at about $0.049. Sume does not list MAI, so that voice cannot be dropped into this workflow without bringing its audio in as a file first.
Sources
Related posts
More in Use cases
- 15 thumbnail tests (5 videos x 3 variants): $2.25 at 2K on Sume
Three 16:9 thumbnail variants for each of five videos is 15 images: $1.50 at 1K, $2.25 at 2K or $3.00 at 4K on Nano Banana 2.1 via Sume. YouTube's size rules.
- 150-second YouTube Short from three avatar jobs (60+60+30): cost
A 150-second avatar Short built from 60, 60 and 30 second jobs costs $27.60 at standard video, plus $0.125 music and $0.30 Timeline render.
- A 2-second product hero clip on Wan 3.0 costs $0.125 at 480p
Wan 3.0's shortest clip is 2 seconds: $0.125 at 480p, $0.25 at 720p, $0.50 at 1080p. Here is the price ladder for 2, 3 and 5 seconds.
- 20-SKU catalog videos: one still and one Wan 3.0 clip each, $8.25
Twenty product videos from one 1K still and one 5-second Wan 3.0 clip at 480p cost $8.25. At 720p the set is $14.50. Each SKU is its own job.
Written by Sume