A 4K image request returns 202: poll the job and fetch the result
POST /v1/images waits 30 seconds. Slow 4K or high-quality calls return 202 with a job envelope. Python that handles both and polls to completion.
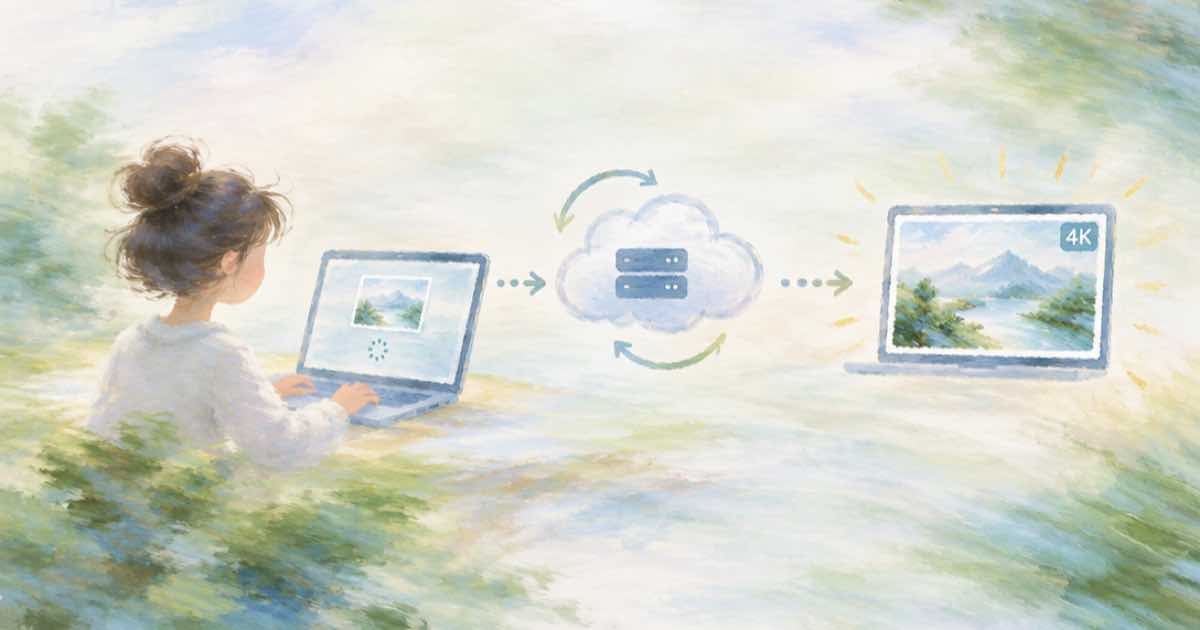
POST /v1/images is synchronous by default: it waits up to 30 seconds and returns 200 with data[].url images. When generation is slower, Sume returns 202 and a job envelope instead of an error. The Sume docs name the slow cases: 4K, high quality and large n. They also say to examine the status code, not the body shape.
The two shapes
| Status | Body | Your next step |
|---|---|---|
| 200 | created, model, data[].url, usage.cost | Use the urls |
| 202 | data.job.id, status_url, result_url | Poll status, then fetch result |
| 502 | error envelope with code and next_action | Fix input or retry per retryable |
Python that handles both
Poll GET /v1/jobs/{id}/status until it reports terminal, then read GET /v1/jobs/{id}/result. The status endpoint's sume_status is completed on success, and the result endpoint answers 409 job_not_completed for any other state.
import os, time, requests
base = "https://api.sume.com"
headers = {"Authorization": "Bearer " + os.environ["SUME_API_KEY"]}
body = {"model": "google/nano-banana-2", "prompt": "Mountain at dawn",
        "resolution": "4K", "aspect_ratio": "16:9"}
r = requests.post(base + "/v1/images", headers=headers, json=body, timeout=60)
if r.status_code == 200:
    print([d["url"] for d in r.json()["data"]])
elif r.status_code == 202:
    job_id = r.json()["data"]["job"]["id"]
    while True:
        s = requests.get(f"{base}/v1/jobs/{job_id}/status", headers=headers, timeout=30).json()["data"]
        if s.get("terminal"):
            break
        time.sleep(s.get("next_poll_after_seconds") or 3)
    if s.get("sume_status") == "completed":
        print(requests.get(f"{base}/v1/jobs/{job_id}/result", headers=headers, timeout=30).json())
else:
    print(r.status_code, r.text)
Alternatives
If you already know the call is slow, send mode: "async" and skip the wait. The job result keeps the platform's generic job shape for every product, so print it once to see where your images sit. Status and result bodies wrap their fields in data, which is why the loop reads ["data"].
How this was checked
Vendor facts come from the pages listed in the sources, read on 2026-10-05. Sume facts come from the Image API docs and the catalog code on main on the same date. Catalogs and limits change, so read the descriptors from GET /v1/images/models before you pin a number in production code.
Sources
Related posts
More in Developers
- Video job stuck in queued on Sume: limits by plan and queue_full
A queued video job is not a failure. Sume runs 1, 4, 8 or 20 jobs at once on Free, Pro, Startup and Scale, and queues the rest. 429 queue_full: queue full.
- Timeline invalid_fit 400: fit must be cover, contain, stretch or blur
invalid_fit means video[].fit is not cover, contain, stretch or blur. Cover is the default, so omit the field if you want it. details.allowed lists values.
- Timeline invalid_fps 400: output.fps must be 24, 25, 30 or 60
invalid_fps rejects any output.fps outside 24, 25, 30 and 60. Omit the field to match the source frame rate; details.allowed lists the accepted values.
- Timeline invalid_transition_type: why xfade is rejected (use fade)
transition.type accepts fade, wipeleft, wiperight, slideup, slidedown and dissolve. xfade is the internal ffmpeg name, so it returns invalid_transition_type.
Written by Sume