Hedra Omnia: one image plus audio, and Sume's lip-sync route
Hedra lists Omnia as full-body animation from one image and audio. Sume's H3 Max lip-sync route also takes a still and audio. Inputs and price compared.
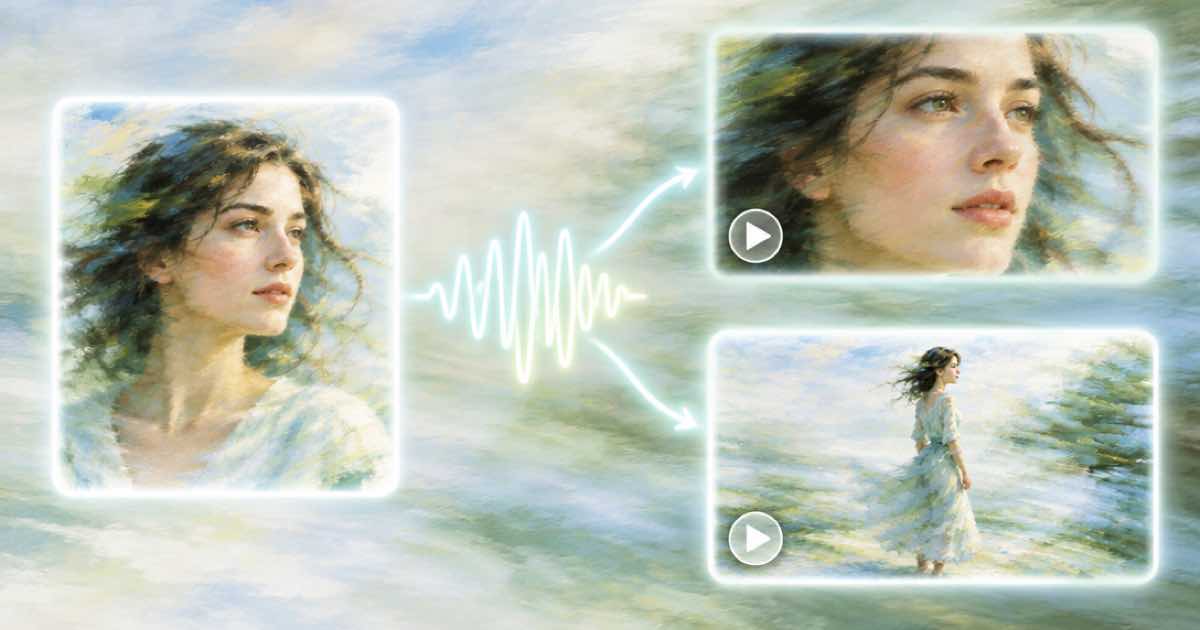
If you want a single image plus an audio file to become a speaking video, both Hedra and Sume take that pair of inputs. Hedra lists Omnia (Fast Alpha) as full-body and facial animation from one image and audio. Sume's POST /v1/minimax/h3-max/lip-sync takes image_url (or a saved avatar_id / avatar_handle) plus a Sume-hosted audio_url and returns a lip-synced video. The difference you must plan for is the scope: the Sume route is a lip-sync route, and the docs describe it as a still plus audio job, not a full-body motion model.
What each side lists
The Hedra row comes from the vendor's own announcements page, which is dated June 1, 2026, so check it again before you build on it. The Sume row comes from the repo API doc for the route.
| Item | Hedra Omnia (Fast Alpha) | Sume H3 Max lip sync |
|---|---|---|
| Inputs | One image and audio | One still (or a saved avatar) and Sume-hosted audio, 10 MB at most |
| Scope listed | Full-body and facial animation | Lip sync on the still; clip length set by duration_seconds |
| Clip length | Not stated on the page I read | 5 to 14.8 seconds, rejected outside that range |
| Resolution | Not stated for Omnia | 480p, 768p (default) or 1080p |
| Price | Not stated for Omnia | Rate card times 1.25; 5 s at 768p reserves $0.50 |
| Status | Fast Alpha | Public route, job type avatar_image_to_video |
A quick way to test both
Use the same portrait and the same 8-second line for both services. The point is to see what moves, not to rank them.
- Render the line once with Sume at 480p so you pay the lowest rate: ceil(8) seconds at $0.0625 is $0.50.
- Check that the still's width divided by height is between 0.4 and 2.5; Sume rejects other stills.
- Upload the audio to Sume first, because
audio_urlmust be a Sume-hosted file. - Send
duration_secondsthat matches the audio, as a number from 5 to 14.8. - Poll
GET /v1/jobs/:id/status, then read/resultwhen it is done.
What Sume does not do
Sume's lip-sync route does not turn a still into a full-body performance. If you need a body to move, the docs point to Kling motion control, which takes a still plus a motion video rather than audio. I could not find a Sume route that takes one image and audio and animates the whole body, so treat that as a gap against the Hedra listing.
The route also does not clamp. A duration_seconds of 15 is refused, not trimmed, and speed_tier is accepted and ignored. The strict body rejects model, endpoint and provider_endpoint.
How to choose
Pick by the shot you need. A head-and-shoulders line read by a presenter fits a lip-sync job, and you pay a known per-second rate with a reserve at admission and a refund if the job fails. A shot where the character walks or gestures needs a motion source. Whatever you choose, pin the model for the whole run: the Sume packet guidance is to use one lip-sync model per run so faces and timing stay consistent across segments.
Sources
Related posts
More in Comparisons
- Soul vs Seedream 5.0 Lite for 100 concept frames on Sume
100 concept frames: Soul bills $0.50 at 720p in 25 calls of four; Seedream 5.0 Lite bills $4.375 and can edit a reference. Ratios, limits and when each fits.
- input_references by Sume image model: 0, 5, 10 or 16 images
Sume image rows take 0, 5, 10 or 16 reference images. A table for every row, plus how Nano Banana 2.1's 14 and Hy Image 3.5's 20 compare.
- Is 1080p worth it for 30 s AI shots? 2.46x on Seedance, 2x on Wan
On Sume, 1080p costs 2.46 times 720p for a 30 s Seedance 2.5 clip and exactly 2 times on Wan 3.0. A rule for choosing the resolution.
- Is MAI-Voice-2.1 on Sume? What the TTS Router lists instead
No. Sume's TTS Router lists five Sonic ids, each up to 20,000 characters at the same price. MAI-Voice-2.1 and Flash are not in the catalog.
Written by Sume