TTS sentence slices: segmentation, wav output and boundary_lead_ms 70
Sume TTS can return gapless sentence segments. Needs timestamps.words and wav or raw for per-sentence audio_url. A 900-character script costs $0.04275.
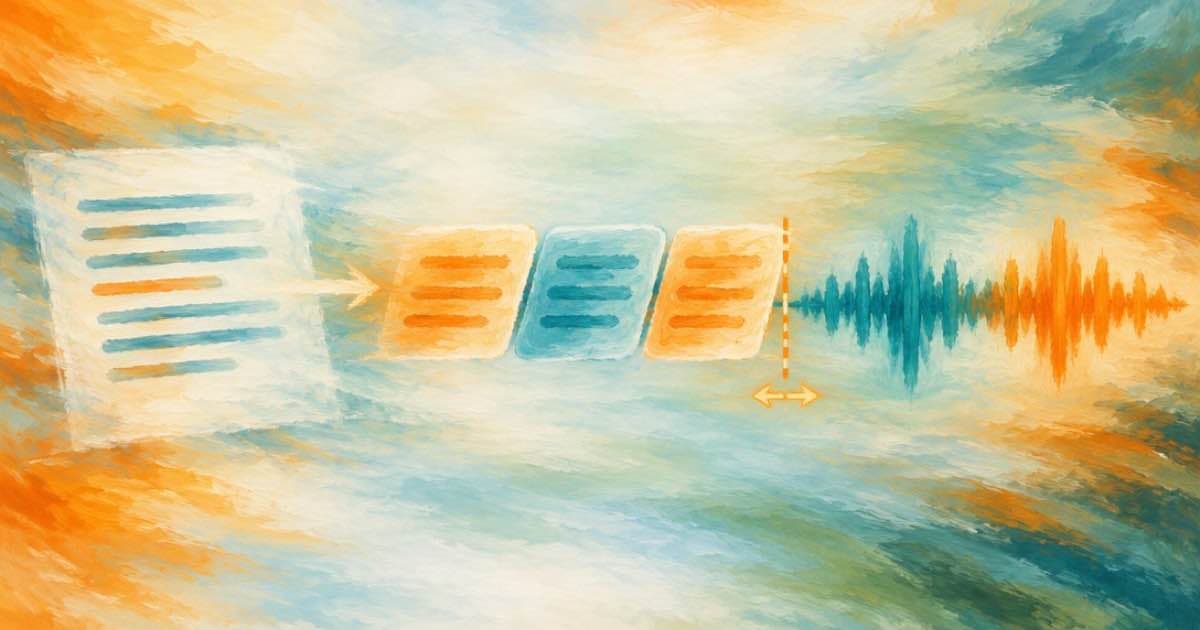
Add segmentation {"mode": "sentence"} to a Sume TTS request, with timestamps.words true, and the result returns gapless segments[]. Use a wav or raw container to get a sample-exact audio_url per sentence; a 900-character script is $0.04275.
How the options combine
Rules are from the OpenAPI schema for segmentation.
| Setting | Value | Effect |
|---|---|---|
| mode | sentence (only option) | Cuts at sentence ends |
| boundary_lead_ms | 0 to 500, default 70 | Cut falls this long after the last word; the next segment absorbs the pause |
| emit_audio | default true | With wav or raw: per-segment audio_url. With mp3: timings only |
Request
Per-sentence slices are handy when each sentence maps to one scene.
{
  "transcript": "Rain starts at noon. Bring a jacket. Dry by evening.",
  "avatar_handle": "@narrator",
  "language": "en",
  "output_format": {"container": "wav", "sample_rate": 24000, "encoding": "pcm_s16le"},
  "timestamps": {"words": true},
  "segmentation": {"mode": "sentence", "boundary_lead_ms": 70}
}
Gotchas
Segmentation without timestamps.words is invalid. With mp3 you still get segment timings but no slices. Segments are gapless: segment[i].end equals segment[i+1].start, so pauses live at the start of the next sentence.
Sources
Related posts
More in Developers
- Sume TTS sentence segments: boundary_lead_ms 0 vs 500, 12 lines
Ask Sume TTS for words and sentence segmentation and you get gapless wav slices. boundary_lead_ms (default 70) moves each cut 0 to 500 ms after the last word.
- TTS speed 1.2 turns a 30-second read into about 25 seconds
Sume TTS accepts generation_config.speed from 0.6 to 1.5. Speed changes length, not the bill: 450 characters cost $0.021375 at any speed. Test the real length.
- TTS word timings straight into captions: a 45-second ad for 33 cents
Ask Sume TTS for timestamps.words and send them as words on the caption job: no speech-to-text. 700 characters, render and captions come to $0.33.
- 20 Nano Banana 2.1 2K images: $3.00 and one jobs_result read
Twenty Nano Banana 2.1 images at 2K cost $3.00 on Sume. Over hosted MCP, one jobs_result call with 20 job_ids reads them back; failed ids are named.
Written by Sume