
Try-on still to a 6-second reveal: Gemini Omni start and end frame
Use gemini-omni-flash-1.1 with an image_url and end_image_url on Sume to animate a try-on from the plain product shot to the finished look.
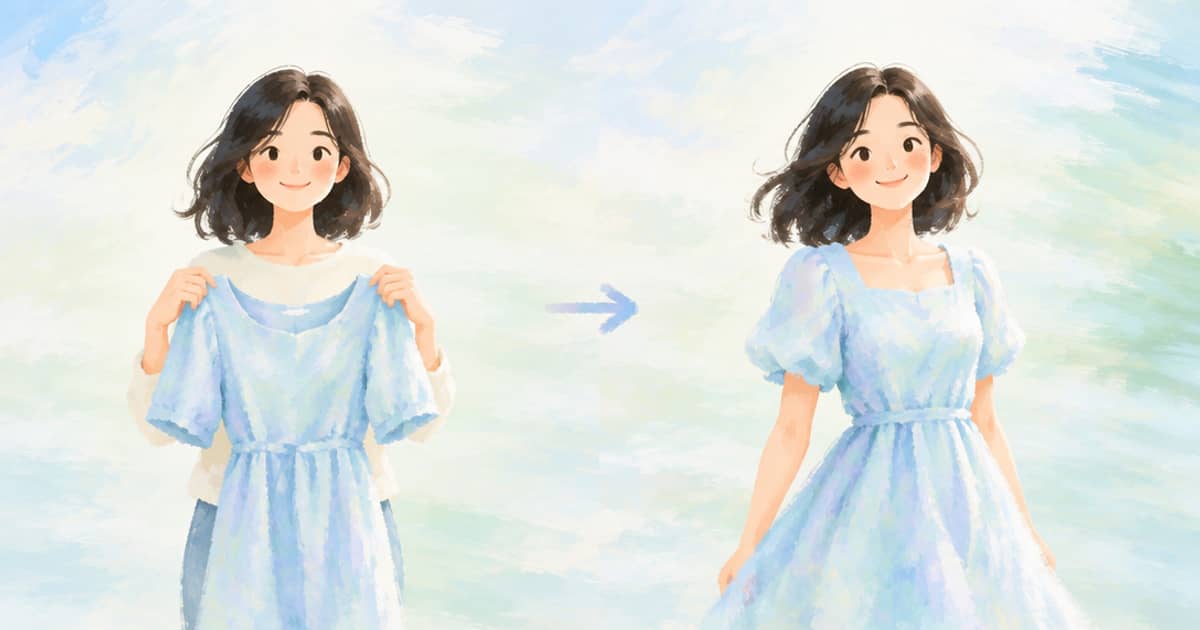
To turn a try-on still into a short clip, send the plain product or base shot as image_url and the finished try-on as end_image_url to gemini-omni-flash-1.1 through Sume's Video Router, with a duration between 3 and 10 seconds. The model fills the motion between the two frames. This is the right pattern when you already have both stills, for example from a ChatGPT Try On style render, and want a reveal.
The Sume docs list gemini-omni-flash-1.1 with text-to-video, image-to-video, reference-to-video and video edit modes. Image-to-video takes image_url plus an optional end_image_url, in the same envelope as text-to-video: 3 to 10 seconds, 360p to 4K, 16:9 or 9:16 (read 2026-10-03, Sume Video Router docs).
The request
Native audio is always on for this model, and generate_audio: false is rejected, so plan a sound-off check before you post. Write the prompt about motion, not about the product, because both frames already define how it looks.
curl -X POST https://api.sume.com/v1/video-router/generate \
  -H "Authorization: Bearer $SUME_API_KEY" \
  -H "Content-Type: application/json" \
  -H "Idempotency-Key: tryon-reveal-sku-1042-v1" \
  -d '{
    "model": "gemini-omni-flash-1.1",
    "prompt": "Slow push-in. The model turns a quarter turn and the jacket settles into place. Soft window light.",
    "image_url": "https://cdn.example.com/tryon/1042-base.jpg",
    "end_image_url": "https://cdn.example.com/tryon/1042-final.jpg",
    "duration": 6,
    "resolution": "720p",
    "aspect_ratio": "9:16",
    "mode": "async"
  }'
What to feed it
The two frames should share a camera position, a person and a background. If the end frame is a different pose from a different crop, the model has to invent the move between them, and that is where garments change shape mid-clip. A try-on built from the same reference photo, as in the screenshot try-on post, gives you matching frames for free.
OpenAI's page for Images 2.5 says the model is better at preserving subjects in reference photos and follows editing instructions more reliably across multiple turns (read 2026-10-03). That is a reason to expect a consistent end frame, not a guarantee, so look at both frames side by side before you spend on video.
| Setting | Value | Note |
|---|---|---|
| Duration | 3 to 10 seconds | Fixed range for this model |
| Resolution | 360p, 720p, 1080p, 4K | Draft at 720p first |
| Aspect ratio | 16:9 or 9:16 | Pick 9:16 for Reels and Shop feeds |
| Frames | image_url plus optional end_image_url | End frame is optional |
| Audio | Always on | generate_audio: false is rejected |
| Edit mode | video_url alone | Cannot combine with image fields |
Cost and retries
Video Router bills the provider list price times 1.25 per output second, by resolution. A 6-second 720p draft costs a fraction of a 4K one, so lock the motion at 720p and only then re-render. Send an Idempotency-Key that names the SKU and a version, as above, so a double submit does not charge twice. For the choice of video model by use, the which-call-returns-which post is the map.
If a call fails, the shared errors page lists the common cases: 402 insufficient_credits when the balance is short, 429 rate_limited or queue_full when you are sending too fast, and input errors such as input_media_unreachable when a frame URL is not public HTTPS or cannot be fetched. Fix the URL and resend with the same key. The failed attempt does not hold the key.
Checking the clip before you post
A reveal clip fails in a few predictable ways. The garment can change length between the first and last frame, a pattern can swim as the camera moves, and hands can pick up an extra finger on the turn. Pull a few frames from the result with the video-frames endpoint and compare them to the end still; the QC checklist lists what to look at.
Because audio is always on for this model, also listen once. If you need a silent clip for a platform that autoplays with sound off, that is fine, but a clip with unwanted sound will not be fixed by a flag on this model. A short prompt line about a quiet room is the lever you have.
Finally, keep the two input frames in your own storage next to the output URL. If a shopper reports a bad render, you can see exactly what the model was given, and re-run with a changed prompt and a new key version rather than guessing.
Sources
Related posts
More in Media tools
- Turn a hum into music with AI: what Sume takes as input
Stability says hum-to-steer is coming. Sume's music API takes text and one optional image, not audio. Here is how to describe a hummed tune in a prompt.
- Upload 15 Shorts at once in Studio: probe every file first
Studio takes up to 15 Shorts per upload, each up to 3 minutes and square or vertical. Check duration and frame shape with video-inspect before you queue.
- Upscale an old Sora download: the limits of Sume's video upscaler
Sora files you saved can be upscaled. Sume's video-upscale model takes a scale from 1.1 to 4, up to 30 seconds, and a fast, standard or pro tier.
- Vertical video subtitles: BBC's 3-line rule and Sume settings
BBC guidance for 9:16 subtitles: up to 3 lines, 90% width, placed a little high. How to set safe_width_ratio and anchor_ratio on Sume burned-in captions.
Written by Sume