
Sume job webhooks: 10 attempts, 30 seconds apart, at least 270 s
Ten attempts with a fixed 30-second gap cover at least 270 seconds. What that means for your deploys, cold starts and when to fall back to polling a Sume job.
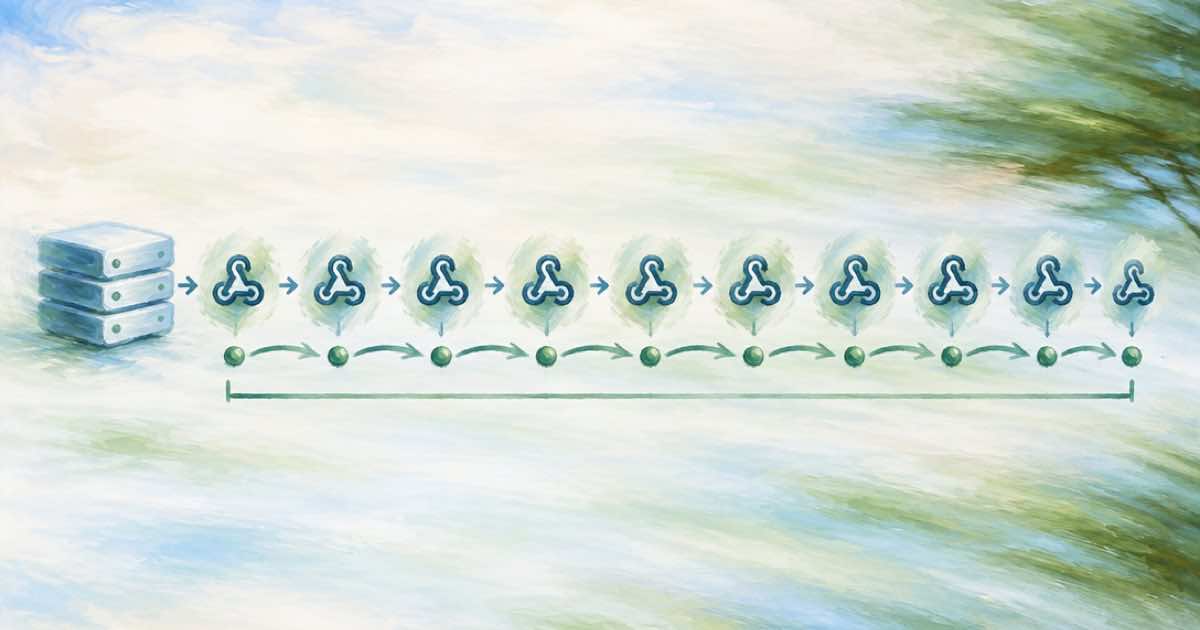
Sume tries a job webhook up to ten times in total, with a fixed delay between attempts (30 seconds by default, not exponential), and gives each attempt 10 seconds. Nine gaps of 30 seconds is 270 seconds, so your endpoint has at least four and a half minutes of retries to come back from a deploy or a cold start. After that the delivery is exhausted, but the job is still finished.
Treat that as a design input. If your receiver is down for longer than about five minutes, you will not get a retry-after-recovery; you will get a poll, or you will use Redeliver.
The numbers, from the docs
These values come straight from the generation-job webhooks page. The derived row is plain arithmetic on them, not a Sume statement.
| Item | Value |
|---|---|
| Total attempts | 10 |
| Spacing | Fixed delay, 30 seconds by default |
| Per-attempt timeout | 10 seconds |
| Gaps between attempts | 9 |
| Derived minimum span | 9 x 30 s = 270 s (4.5 minutes), plus attempt time |
| Delivery statuses | pending, delivering, delivered, retrying, failed, exhausted |
What survives and what does not
A rolling deploy that takes a minute is fine: the retries land on the new instance. A cold start that takes 12 seconds is not: the attempt times out at 10 seconds and is counted. So acknowledge first and work later; write the event to a queue or table, return 204, and do the slow copy of the media afterwards.
A weekend-long outage is outside the retry window entirely. That is why the docs call webhooks a delivery optimization and not the only recovery path.
Recovery tools you already have
There are three, and none needs a new job.
The job object and webhook.delivery events show the delivery status and attempt count when it is available, so you can query what happened. Redeliver re-sends the real terminal event with a fresh timestamp and signature and does not use one of the automatic ten. Polling status_url always works.
POST /v1/jobs/{job_id}/webhook/redeliver(needsjobs:write) re-POSTs the realjob.completed,job.failedorjob.canceledevent.- Send test (
POST /v1/webhooks/test-deliveries) posts a dummywebhook.testand never replays a job. Do not use it as a replay. GET /v1/jobs?status=...lists jobs so a sweeper can find ones that finished while you were down.- Redeliver cannot change the URL; a new URL is a new job.
A sweeper schedule that fits
Run a sweeper every few minutes that lists non-terminal jobs older than your expected duration and polls their status. With the exact retry window known, you can set the sweeper to start looking about five minutes after a job should have finished, which avoids racing the webhook path and doubling your reads.
Checking your own endpoint against the window
Measure three things before launch: your slowest cold start, your slowest deploy gap, and your p99 handler time with the media copy removed. If the cold start is above 10 seconds, the first attempt will always time out, so keep one instance warm or accept that the second attempt (30 seconds later) does the real work.
Log the delivery attempt count if you can see it, and alert when the same job id arrives more than twice; that usually means a slow handler, not an outage.
Sources
Related posts
More in Developers
- sume login --no-browser on a remote server: approve the user_code URL
On an SSH box, sume login --no-browser prints the approval URL instead of opening a browser. After you approve the user_code, the CLI stores a CLI-scoped key.
- Sume media tools: which wait for a 200 and which always return 202
Video inspect defaults to sync; trim, filter, detach, compose and timeline to async; frames is always 202. The 30 s wait and where each result is read.
- Sume music job in Python: 30-second wait, then poll, one paid job
Submit a Lyria track to Sume Music Router with a 30-second sync wait, fall back to polling on timeout, and reuse one Idempotency-Key. Runnable Python.
- Why the Sume catalog shows $0.02 to $42.86 for one video route
GET /v1/catalog publishes an estimate plus a minimum and maximum for each route. Video spans $0.02 to $42.86, image $0.01 to $7.36, TTS $0.01 to $0.95.
Written by Sume