Split one voiceover into six beat files with Timeline audio split
Slice a 180-second voice file into up to 20 ranges for $0.01 flat, then use each file as a beat of a Reel. Ranges can overlap and the last can be open-ended.
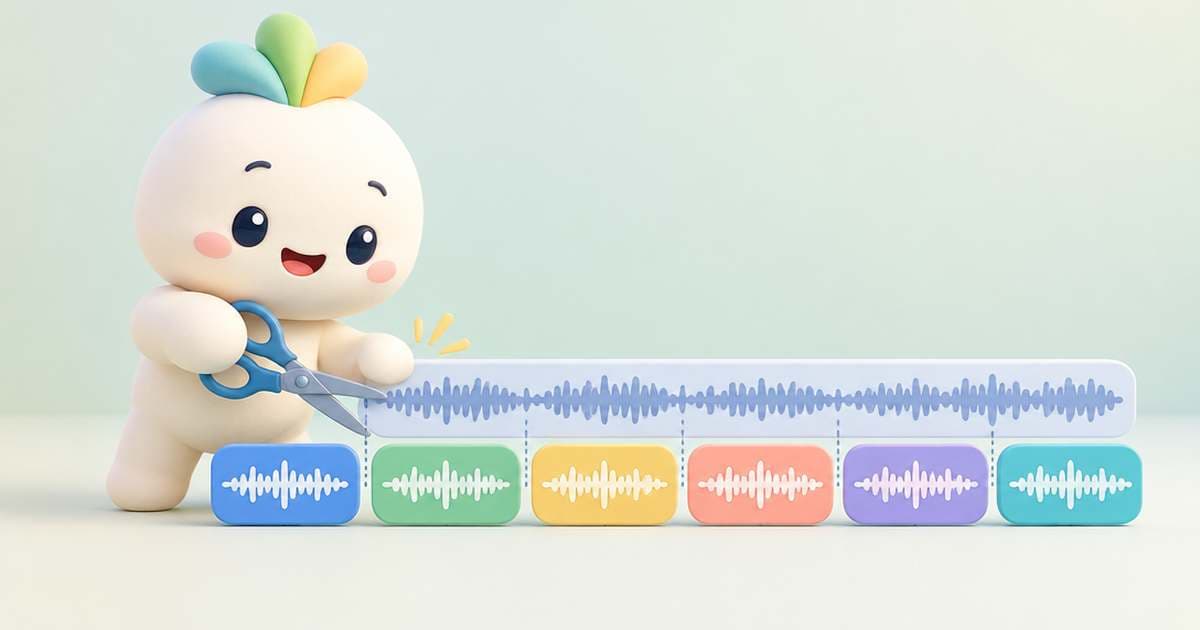
Sume's timeline audio split cuts one hosted audio file into up to 20 ranges in a single job and costs a flat $0.01. Each range returns its own durable audio URL, so a 3-minute voiceover can become six beat files in one call. Ranges may overlap, and a range with no end runs to the end of the file.
Why split a voice file
A Reel at 3 minutes (reported by Metricool (read 2026-10-03)) is easier to edit as beats, where each beat's pictures start where its voice starts. If you recorded one long take or detached one from an earlier Reel, splitting gives you per-beat files for avatar jobs, captions or re-voicing, without running text-to-speech again.
The request
POST /v1/timeline-1.0/audio with operation: "split", a top-level url and ranges[]. Do not send parts, which belongs to concat. An end at or before the start fails with audio_range_end_before_start. The default output is wav; mp3 is available through output.format but is smaller and less exact.
| Beat | start (s) | end (s) |
|---|---|---|
| 1 | 0 | 22 |
| 2 | 22 | 52 |
| 3 | 52 | 88 |
| 4 | 88 | 124 |
| 5 | 124 | 158 |
| 6 | 158 | (omit) |
Code
Idempotency is required, so a repeated call with the same key does not bill twice.
import os, requests

edges = [0, 22, 52, 88, 124, 158]
ranges = []
for i, start in enumerate(edges):
    r = {"start": start}
    if i + 1 < len(edges):
        r["end"] = edges[i + 1]
    ranges.append(r)

res = requests.post(
    "https://api.sume.com/v1/timeline-1.0/audio",
    headers={
        "Authorization": "Bearer " + os.environ["SUME_API_KEY"],
        "Idempotency-Key": "split-beats-001",
    },
    json={
        "operation": "split",
        "url": os.environ["VOICE_URL"],
        "ranges": ranges,
    },
)
res.raise_for_status()
print(res.json())
What Sume does not do
Split does not find the beat boundaries. You choose them, for example from the sentence segments of a transcript. It also does not re-time: the produced audio is limited to 1800 seconds, and the cut points are exactly the ones you send. For a join that is only needed inside one render, skip the audio job and use audio.parts[] in Timeline 1.0 (up to 20 slices).
Sources
Related posts
More in Media tools
- Spotify podcast transcript upload: VTT, 5MB and Sume STT parts
Spotify takes VTT or SRT up to 5MB, with timestamps. Build one from Sume STT in 10-minute parts, stitch the cues, and upload from Spotify for Creators.
- SRT or WebVTT? What Vimeo, Spotify, Apple and Cloudflare accept
Vimeo, Spotify and Apple Podcasts take SRT or WebVTT; Cloudflare Stream documents WebVTT. A table read 2026-10-03 and a script writing both from Sume segments.
- Swap the model in a clothing video with AI: H3 Max Recast
Recast swaps the person in a clip for a person from a photo, 5 to 30 seconds. What it keeps, what the docs leave open about the garment, and the Sume call.
- TikTok ad caption budgets: 100 in TopView, 150 for Spark Pull, 4 lines
TikTok's TopView page caps ad captions at 100 characters, Spark Pull allows 150, and both display four lines. Limits by placement and short burned-in text.
Written by Sume