Low-latency TTS without streaming: one job per sentence
Sume TTS has no streaming. To start playback early, split the script by sentence, submit the jobs in parallel and play each file as it finishes, in order.
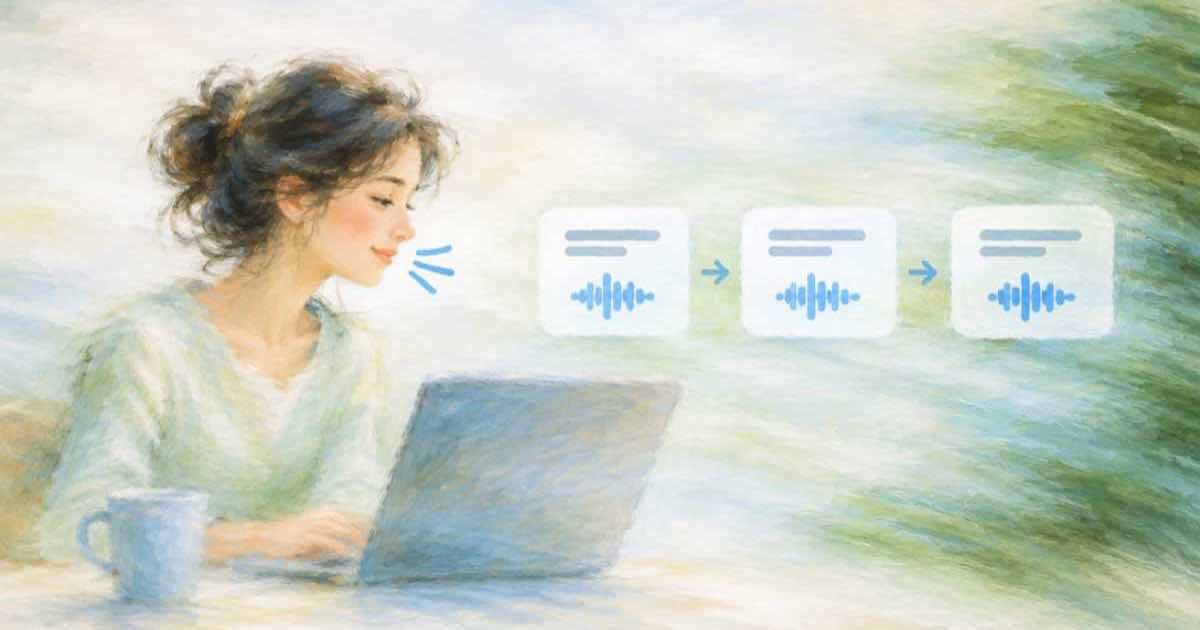
Sume TTS does not stream audio, so you cannot start playing a line before the job finishes. You can still cut the wait on a longer script: split it at sentence boundaries, submit one job per sentence at the same time, and play each file as soon as it completes, in order. The user hears sentence one when sentence one is done, not when the whole script is. This is a latency pattern for narration, not a replacement for a real-time voice agent.
Microsoft's MAI-Voice-2.1-Flash is the reason the question is trending. The October tracker lists a vendor claim of 150 ms end to end at $15 per 1M characters (read 2026-10-06). If your product needs speech inside a live turn, that is the right class of tool. If it needs a read-aloud button, a video voiceover or a preview, per-sentence jobs on Sume get you most of the way and keep the pricing flat.
What you can and cannot get
Sume's own docs say what the router is: an asynchronous job API, with streaming TTS listed as a non-goal. The first response returns a job, and the audio is a hosted artifact. Latency to first sound is therefore the time to finish the first job, plus your download. Shorter text finishes sooner, so the first job should be small. Send a short first sentence and let the rest batch behind it.
Parallel submission is the part that helps. Jobs started together run side by side, so the wait for the last file tracks the slowest job rather than the sum, up to your workspace concurrency limits. Measure your own numbers with the timing helper in benchmark TTS latency yourself; this post does not quote a figure because none ships in the docs.
Submit all, play in order
import asyncio, json, os, re, time, urllib.request as u

KEY = os.environ["SUME_API_KEY"]
HANDLE = os.environ["SUME_AVATAR_HANDLE"]

def call(url, body=None, extra=None):
    h = {"Authorization": "Bearer " + KEY, "Content-Type": "application/json", **(extra or {})}
    data = json.dumps(body).encode() if body is not None else None
    return json.load(u.urlopen(u.Request(url, data=data, headers=h)))["data"]

def render(i, sentence):
    job = call("https://api.sume.com/v1/tts-router/generate",
               {"model": "sonic-3.6", "transcript": sentence, "avatar_handle": HANDLE, "language": "en"},
               {"Idempotency-Key": f"read-aloud-v1-{i}"})
    state = job
    while not state["terminal"]:
        time.sleep(state.get("next_poll_after_seconds") or 1)
        state = call(job["status_url"])
    arts = call(job["result_url"])["result"]["artifacts"]
    return next(a["url"] for a in arts if a["type"] == "audio")

async def main():
    text = "Your order shipped today. It should arrive on Friday. Reply here if you need to change it."
    sentences = re.split(r"(?<=[.!?])\s+", text.strip())
    t0 = time.time()
    tasks = [asyncio.create_task(asyncio.to_thread(render, i, s)) for i, s in enumerate(sentences)]
    for i, task in enumerate(tasks):
        print(f"{time.time() - t0:5.1f}s play {i}:", await task)

asyncio.run(main())
Order, cost and the seam
Awaiting the tasks in order gives you the playback order while the later jobs keep running. Give each sentence its own Idempotency-Key so a crash and rerun reuses finished jobs instead of paying again. Derive the key from the sentence text and voice, as in idempotency keys for batch TTS.
The cost does not change with the split. TTS is billed per character at $0.0475 per 1,000 on every router model, per the pricing page (read 2026-10-06), so the per-character rate does not change when you split a script. Check usage after a trial run to see how tiny jobs are rounded on your account. Watch the seam instead: separate takes can differ slightly in pace and tone. For read-aloud this rarely matters. For a branded voiceover, render the whole script as one job and use segmentation to cut it.
One more limit to respect: the router applies the same admission rules to every job, so a burst of 40 sentence jobs can meet a 429 rate_limited or queue_full. Retry the same POST with the same key after a short delay instead of dropping the sentence, and cap your own concurrency at a handful of jobs per listener. For a read-aloud button, five or six parallel jobs per page view is plenty, and the first short sentence is what the listener waits for.
A worked example with the sample script in the code above: it is 90 characters including spaces and punctuation, which the TTS docs say count toward the bill. At $0.0475 per 1,000 characters that is about $0.0042 for the whole script, and the three sentence jobs together carry the same character count. The numbers are small on purpose. The reason to split is latency and retry granularity, not cost: if sentence two fails, you rerun sentence two under its own key and the other two finished files stay as they are.
| Need | Use | Why |
|---|---|---|
| Speech inside a live conversation | A streaming TTS such as MAI-Voice-2.1-Flash | Vendor claims 150 ms end to end |
| Read-aloud or preview within seconds | One Sume job per sentence, parallel | No streaming, first file arrives early |
| Branded voiceover for a video | One job for the full script | One take, with word timings and sentence segments |
Sources
Related posts
More in Developers
- Shadow-run gpt-image-2.5 beside your current model before October 23
Render one prompt on a Sume image id and your current model with a separate idempotency key per model, then compare cost and output before gpt-image-1 ends.
- Shortest and longest values Sume accepts for a Short: one table
Minimum clip, slot, spine and fade values and the maximums for trim, transitions and soundtrack on Sume, in one table with an offline slot checker in Python.
- Shorts season webhooks: a Python receiver that counts episodes
Receive Sume job webhooks for a season of Shorts renders: verify sume-v1, reject an empty secret, de-dupe by job_id, and know when every episode is terminal.
- Sora API gone: 9:16 portrait video on Sume, model by model
Which Sume video models return 9:16 after the Sora API ended on 2026-09-24, how to ask for it, and a script that reads the catalog instead of trusting a table.
Written by Sume