Redis sorted set scheduler for AI video job polling in Python
Keep video job ids in a Redis ZSET scored by next-poll time, claim due ids with ZREM so no two workers poll one job, reschedule by next_poll_after_seconds.
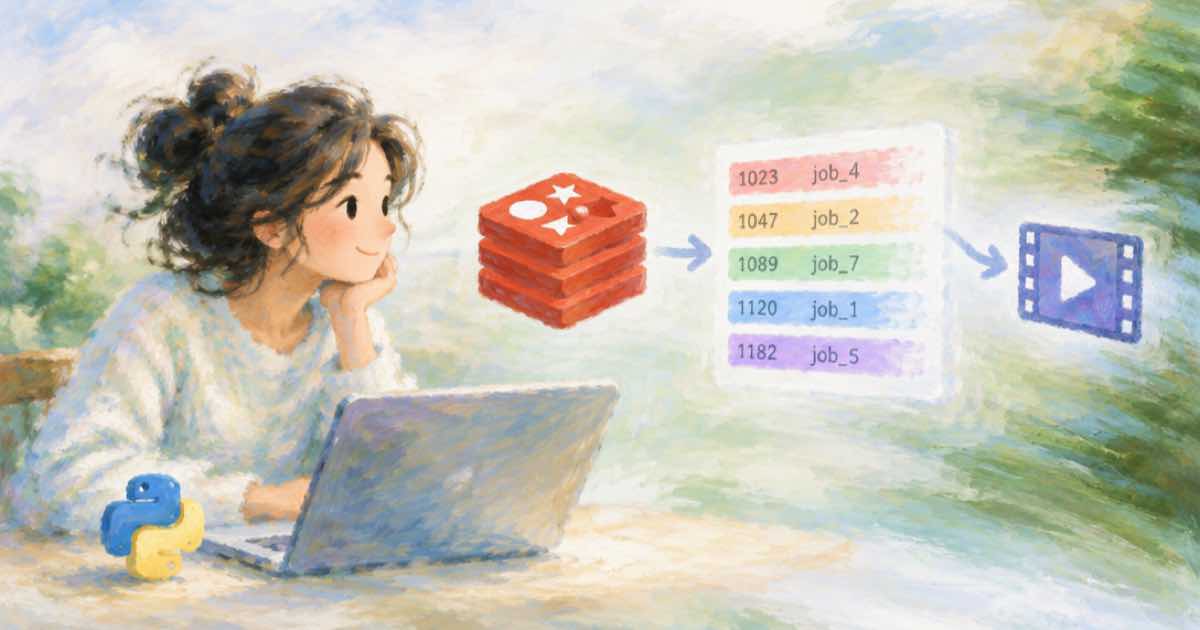
If you run hundreds of video renders and do not want one timer per job, store each job id in a Redis sorted set with the next due time as the score. Workers fetch ids whose score is at or below now, claim each with ZREM, read Sume's status once, and ZADD the id back with a later score. ZREM returns the number of members removed, so only the worker that gets 1 owns the poll (Redis ZREM, read 2026-10-06).
The delay comes from next_poll_after_seconds on GET /v1/jobs/{id}/status; a terminal job returns no delay and leaves the set (Sume jobs guide, read 2026-10-06).
What does the worker loop look like?
ZRANGEBYSCORE is deprecated since Redis 6.2.0 in favor of ZRANGE with BYSCORE (Redis docs, read 2026-10-06), so the code uses redis-py's zrange(..., byscore=True). Run python worker.py with REDIS_URL and SUME_API_KEY set.
import os, time, requests, redis

r = redis.Redis.from_url(os.environ["REDIS_URL"], decode_responses=True)
KEY = "sume:polls"
H = {"Authorization": f"Bearer {os.environ['SUME_API_KEY']}"}

def tick() -> None:
    due = r.zrange(KEY, "-inf", time.time(), byscore=True,
                   offset=0, num=20)
    for job_id in due:
        if r.zrem(KEY, job_id) != 1:
            continue  # another worker claimed it
        try:
            s = requests.get(
                f"https://api.sume.com/v1/jobs/{job_id}/status",
                headers=H, timeout=30)
            s.raise_for_status()
            s = s.json()
        except requests.RequestException:
            r.zadd(KEY, {job_id: time.time() + 30})
            continue
        if s.get("terminal"):
            print(job_id, s["sume_status"])
        else:
            wait = s.get("next_poll_after_seconds") or 15
            r.zadd(KEY, {job_id: time.time() + wait})

if __name__ == "__main__":
    while True:
        tick()
        time.sleep(1)
What happens if a worker dies mid-poll?
Between ZREM and the final ZADD the job id lives only in that worker's memory. If the process is killed there, the id is gone from the set and the render keeps running at Sume. Cover it with a durable record: keep every submitted job id and its state in your database, and run a sweep that re-adds any non-terminal id missing from the set. A Lua script that pops and re-adds with a short lease score is the stricter fix, at the cost of more code.
Why not poll every job every few seconds?
Sume admits only a limited number of jobs per workspace at once (Pro: 4 processing and 20 queued, per the generation admission guide), so most of a large batch sits queued with a suggested delay up to 30 seconds. Scheduling by the returned delay costs a fraction of the reads a fixed one second loop would.
Sources
Related posts
More in Developers
- Refuse an empty Sume API key or webhook secret: a fail-fast loader
An empty SUME_API_KEY or webhook secret fails late and confusingly. Load both at boot, reject empty or whitespace values, and never print them. Python, tested.
- Save a Sume artifact atomically: write a .part file, then rename
A half-written MP4 that looks finished is worse than none. Download a Sume artifact to a .part file, check the length, rename once. Tested in Python.
- Schedule the next Ideogram 4.5 batch wave from ratelimit-reset
Size each wave from ratelimit-remaining and wave_size_hint, and when the write bucket is empty sleep ratelimit-reset seconds. A pure function you can test.
- SDK waitForJob after a 202 from createImage: TypeScript sample
When createImage returns 202 on a slow gpt-image-2.5 render, pass the job id to waitForJob from @sume-com/sdk and read the terminal job instead of hand-polling.
Written by Sume