Postgres SKIP LOCKED poll table for AI video jobs with next_poll_at
Track Sume video jobs in one Postgres table with next_poll_at, claim due rows with FOR UPDATE SKIP LOCKED and reschedule from next_poll_after_seconds.
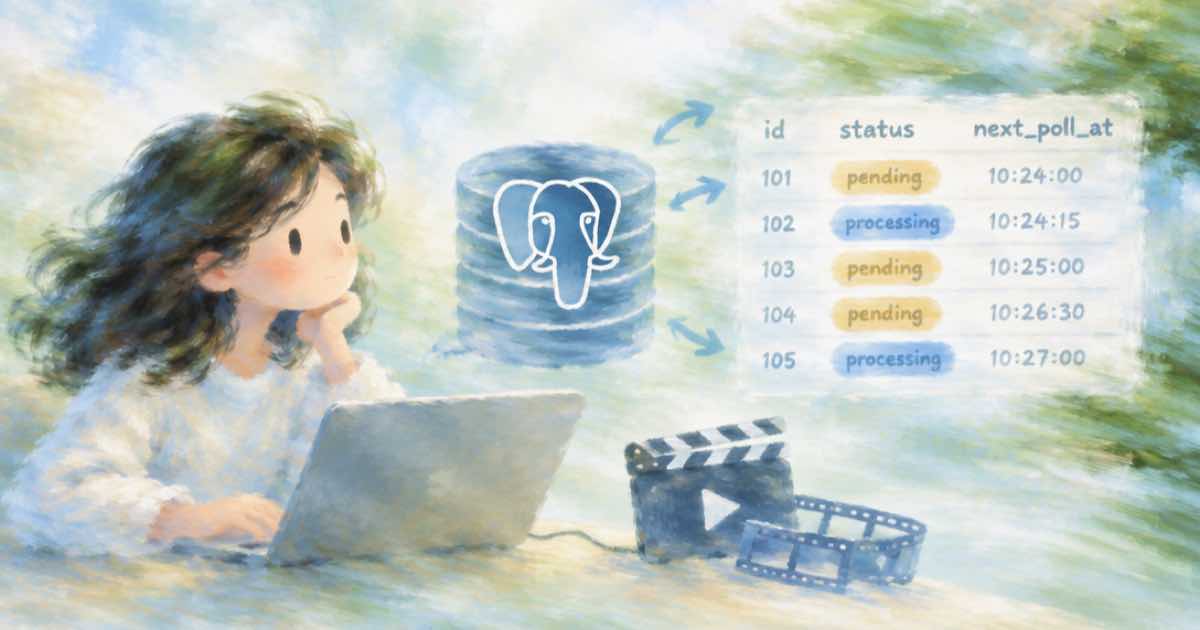
If you already run Postgres, you do not need a queue to poll AI video jobs: one table with a next_poll_at column and a FOR UPDATE SKIP LOCKED query lets any number of workers claim due rows without blocking each other. Each worker reads Sume's GET /v1/jobs/{id}/status, then sets next_poll_at from next_poll_after_seconds, or marks the row done when terminal is true (Sume jobs guide, read 2026-10-06).
The table is also your durable record of paid jobs, which a Redis-only scheduler is not: a worker crash leaves the row in place and it becomes due again.
What is the schema and the claim query?
Insert a row right after POST /v1/videos returns 202, with the job id and next_poll_at = now() + interval '15 seconds'.
CREATE TABLE video_jobs (
  job_id        text PRIMARY KEY,
  state         text NOT NULL DEFAULT 'pending',
  next_poll_at  timestamptz NOT NULL DEFAULT now() + interval '15 seconds'
);
CREATE INDEX ON video_jobs (next_poll_at) WHERE state = 'pending';

-- claim one due row; other workers skip it instead of waiting
SELECT job_id FROM video_jobs
WHERE state = 'pending' AND next_poll_at <= now()
ORDER BY next_poll_at
FOR UPDATE SKIP LOCKED
LIMIT 1;
How does the Python worker use it?
The row lock is held for the length of the HTTP read, so keep the timeout short. If the worker dies, Postgres releases the lock and the row is claimable again.
import os, time, psycopg, requests

H = {"Authorization": f"Bearer {os.environ['SUME_API_KEY']}"}
CLAIM = ("SELECT job_id FROM video_jobs WHERE state='pending' "
         "AND next_poll_at <= now() ORDER BY next_poll_at "
         "FOR UPDATE SKIP LOCKED LIMIT 1")

with psycopg.connect(os.environ["DATABASE_URL"]) as db:
    while True:
        with db.transaction():
            row = db.execute(CLAIM).fetchone()
            if row:
                job_id = row[0]
                s = requests.get(
                    f"https://api.sume.com/v1/jobs/{job_id}/status",
                    headers=H, timeout=15).json()
                if s.get("terminal"):
                    db.execute("UPDATE video_jobs SET state=%s WHERE job_id=%s",
                               (s["sume_status"], job_id))
                else:
                    wait = s.get("next_poll_after_seconds") or 15
                    db.execute("UPDATE video_jobs SET next_poll_at = now() "
                               "+ make_interval(secs => %s) WHERE job_id=%s",
                               (wait, job_id))
        if not row:
            time.sleep(2)
What can go wrong?
- A non-2xx status response makes
.json()return an error body; checkstatus_codefirst in production and leave the row untouched so it is retried. - Long transactions: a slow API call holds the row lock and an open transaction. A 15 second timeout bounds it.
- The
statecolumn stores Sume'ssume_status(completed,failed,canceled) so the partial index only covers rows still being polled.
Does re-running the poller bill a second clip?
No, as long as it only reads. Keep the paid POST /v1/videos in a separate step with an Idempotency-Key you own. A client-side give-up never cancels the render, so store the job id and read it again later instead of submitting a second time (Sume jobs guide, read 2026-10-06).
Sources
Related posts
More in Developers
- pytest: fail CI when a configured image model id isn't in Sume's list
A pytest that reads your image model ids and checks each against GET /v1/images/models, so a retired id such as gpt-image-1 fails CI before it fails a customer.
- Python asyncio semaphore: submit transcription jobs with a cap
Run Sume STT submits through asyncio.Semaphore and asyncio.to_thread, honor retry-after on 429, and keep one Idempotency-Key per clip. Tested code.
- Python exceptions for Sume errors: retry on the class, not the status
Map the Sume error envelope code to two exception classes, Retryable and Fatal, so one except clause drives retries. Covers 409, 429, 402 and 503.
- Python pre-flight for a Short: catch Timeline schema errors offline
A Python check for a Sume Timeline body: even width and height, allowed fps, 1 to 1800 seconds, fade limits and start order. Run it before the plan call.
Written by Sume