
Index-Echo bilingual SRT from a Chinese video to Sume cues
Index-Echo S2TT turns Chinese speech into timed bilingual subtitles in 60-second windows. Convert its SRT into Sume caption cues and burn the English line.
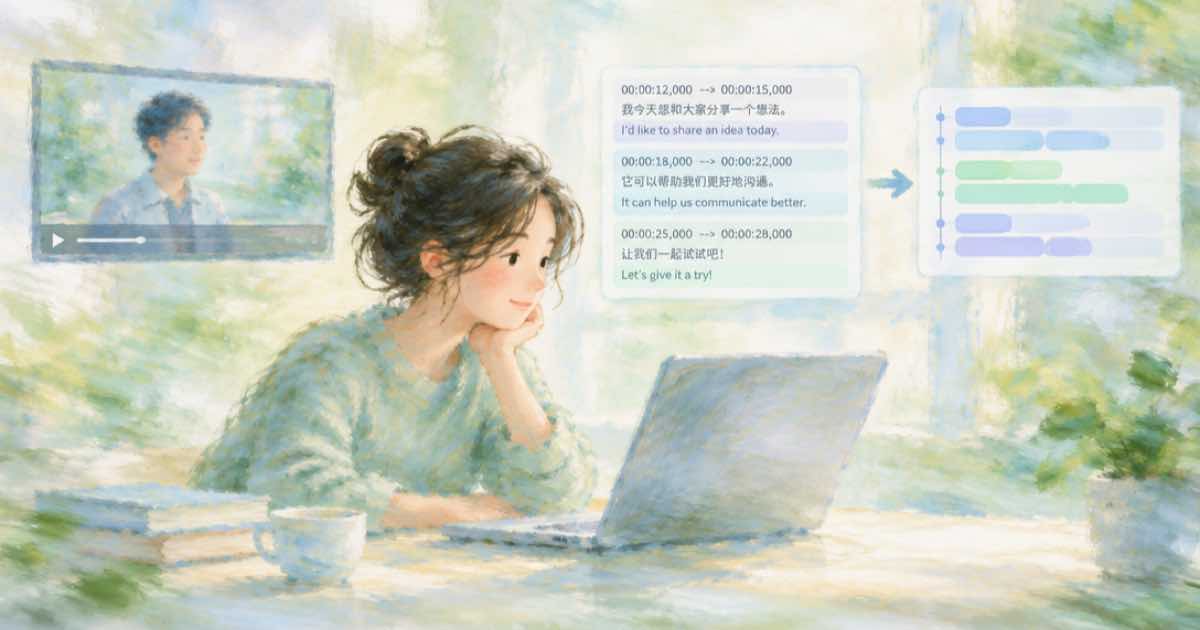
To subtitle a Chinese-language video in English, run Index-Echo S2TT on the file, convert its SRT into caption cues, and burn the English line with Sume. Index-Echo S2TT is the speech-to-text-translation model in Bilibili's Index-Translate family. It transcribes Chinese speech and translates each sentence in one model, with per-sentence timestamps, and writes a bilingual input.srt.
The packaged interface on its model card covers Chinese into English, Japanese or Spanish. This post uses English because Sume's Latin caption styles draw it cleanly.
What does Index-Echo produce?
Per the model card, the command takes a video and a target language and writes an SRT with the Chinese transcript and the translation, plus a per-window JSONL summary. Audio is processed in windows capped at 60 seconds, and longer files are segmented in sequence. The card lists Apache-2.0 and about 10 GB of VRAM at bf16, and it needs ffmpeg on the path. It also warns that timestamp quality can vary with audio conditions and that greedy decoding may repeat on unfamiliar input.
| Item | Value |
|---|---|
| Packaged directions | Chinese to English, Japanese or Spanish |
| Outputs | Bilingual SRT and a per-window JSONL file |
| Audio window | 60 seconds maximum, longer files run in sequence |
| Licence | Apache-2.0 |
| Memory | About 10 GB VRAM at bf16, plus headroom |
| Example command | python3 Index-Echo-S2TT-2B/infer.py input.mp4 --target-lang en --out out_dir |
How do you turn the SRT into Sume cues?
Sume's video captions endpoint accepts cues with text, start and end in seconds, so a bilingual SRT is a parse away. Check which line of each block is Chinese and which is English in your file before you run this; the helper assumes the translation is the last line of each block.
import re

def to_seconds(stamp):
    h, m, rest = stamp.split(":")
    s, ms = rest.split(",")
    return int(h) * 3600 + int(m) * 60 + int(s) + int(ms) / 1000

def srt_to_cues(path):
    cues = []
    text = open(path, encoding="utf-8").read().strip()
    for block in re.split(r"\n\s*\n", text):
        lines = block.splitlines()
        if len(lines) < 3:
            continue
        start, end = lines[1].split(" --> ")
        cues.append({"text": lines[-1].strip(),
                     "start": to_seconds(start.strip()),
                     "end": to_seconds(end.strip())})
    return cues

print(srt_to_cues("out_dir/input.srt")[:2])
What limits apply on the Sume side?
A caption request takes at most 200 cues, each up to 400 characters, with start and end times inside 60 seconds, and cues cannot be mixed with script_text. The 60-second ceiling matches Index-Echo's window, but a longer video needs one job per 60-second piece, with cue times shifted back to start at zero. A standalone job is priced at $0.20 for videos up to 60 seconds under the current estimate.
The video_url must be public HTTPS. Name a Latin style such as slam for English text. Then post the converted cues as in the SRT walkthrough.
What should you review by hand?
- Sentences the model repeated, a known greedy-decoding failure.
- Cues whose timestamps drift from the speech in noisy audio.
- Names and product terms, which are worth a glossary check.
- English lines that run long for their cue, which a reading-speed check will flag.
Sources
Related posts
More in Developers
- Syllable-controlled translation for voiceover that must fit
Translated speech often runs longer than the original. Index-Homura targets length-controlled translation. How to budget words against clip time before TTS.
- Free Index-Translate API for client subtitles: what to check
Index-Translate's free endpoint is labelled an online demo with no stated rate limit. A checklist before client transcripts go in, and the self-host option.
- Keep brand names intact in translated, burned-in captions
Index-Translate supports glossary instructions, but vendor notes say compliance is not guaranteed. Check every term in code before Sume burns the cues in.
- Translate all subtitle cues in one JSON request, then validate
Index-Translate lists JSON format preservation. Send a clip's cues as one JSON array, then validate count, timings and length before Sume burns them.
Written by Sume