Ideogram ad variations API: one axis per call vs Sume n
Ideogram's ad-variations tool varies people, setting, group_size or scene. Sume has no axis field: describe the change in the prompt and set n up to 10.
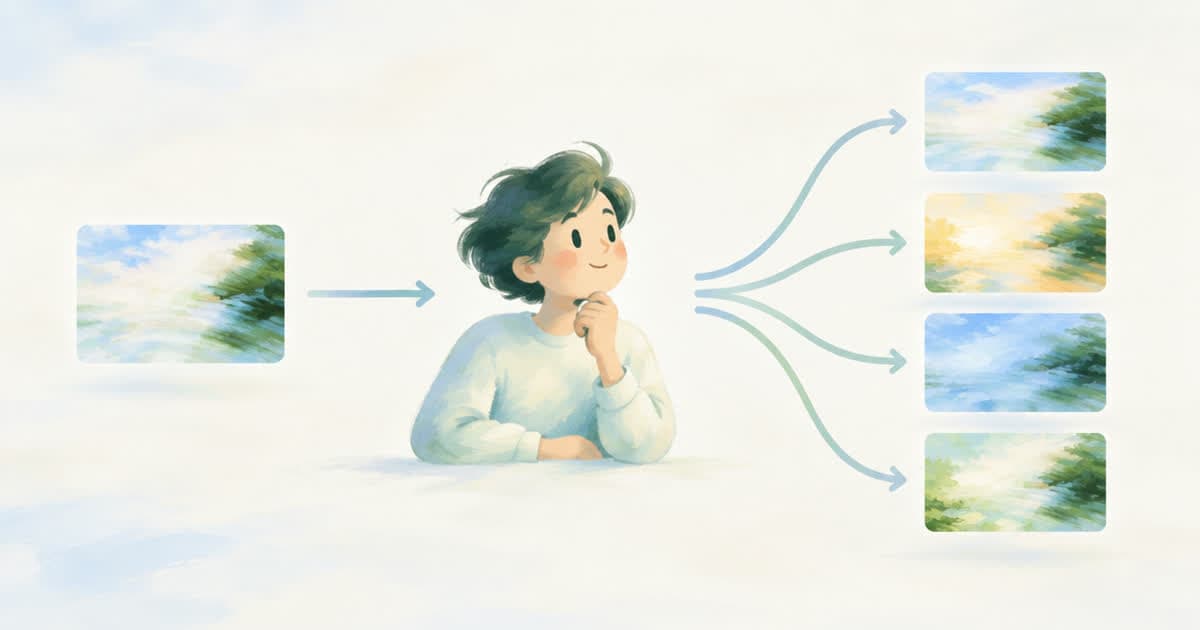
Ideogram's POST /v2/tool/ad-variations varies an ad along one variation_type: people, setting, group_size or scene. Sume has no such field. You send the ad in input_references, name the change in the prompt, and ask for up to 10 images per call with n.
Ideogram facts are from its API reference; Sume facts from Image generation, read 2026-10-01.
What does each Ideogram axis change?
| variation_type | What changes | Prompt wording on Sume |
|---|---|---|
people | Different talent in the ad | Replace the people with different models |
setting | Same subject and product, new environment | Move the product to a new location |
group_size | How many people appear | Show two people instead of one |
scene | Moment or occasion: time of day, season, activity | Same ad at night, or in winter |
What is preserved?
Ideogram says logos, brand colors, the product and all on-image text are preserved, and each output keeps the source's aspect ratio, capped at 3:1. Sume's docs make no preservation claim, so write what must stay fixed into the prompt and set aspect_ratio: "auto" to match the reference.
How do I get many variations on Sume?
Use n. The docs allow up to 10 images per call, with lower per-model ceilings in the catalog's n range descriptor, and GPT Image 2.5 accepts up to 16 references, so you can add a brand-guide image next to the ad. One call can carry only one change, or several; there is no axis enforcement, so keep each prompt to a single change if you want clean comparisons.
For motion ads see ad variations for video.
What if a generation fails?
Image generation billing is all-or-nothing: a generation is either completed and billed in full, or it fails and is not billed.
Sources
Related posts
More in Use cases
- Ideogram ghost mannequin API views vs Sume input references
Ideogram's ghost-mannequin tool takes front, back, left, right, top and bottom photos and a required view. Sume takes a flat input_references list.
- Ideogram model pose variants API vs a Sume edit prompt
Ideogram's pose tool takes an `instruction` field. Sume has no pose endpoint: you edit with a prompt, references and n up to 10 per call.
- Edits bilingual captions vs Sume: language is only a STT hint
Edits translates captions into a second language. In Sume video captions, language only hints speech-to-text, so a second line comes from your own cues.
- Extract audio from an Instagram video: Sume audio detach for intros
Edits can extract audio from a video and save it for later projects. In an API workflow, Sume audio detach returns the track as a new wav or mp3 artifact.
Written by Sume