How Sume TTS splits a script into sentence ids (. ! ? only)
Sume's script source cuts sentences at periods, exclamation and question marks only, keeps every character, and numbers them sent_000000. Examples and traps.
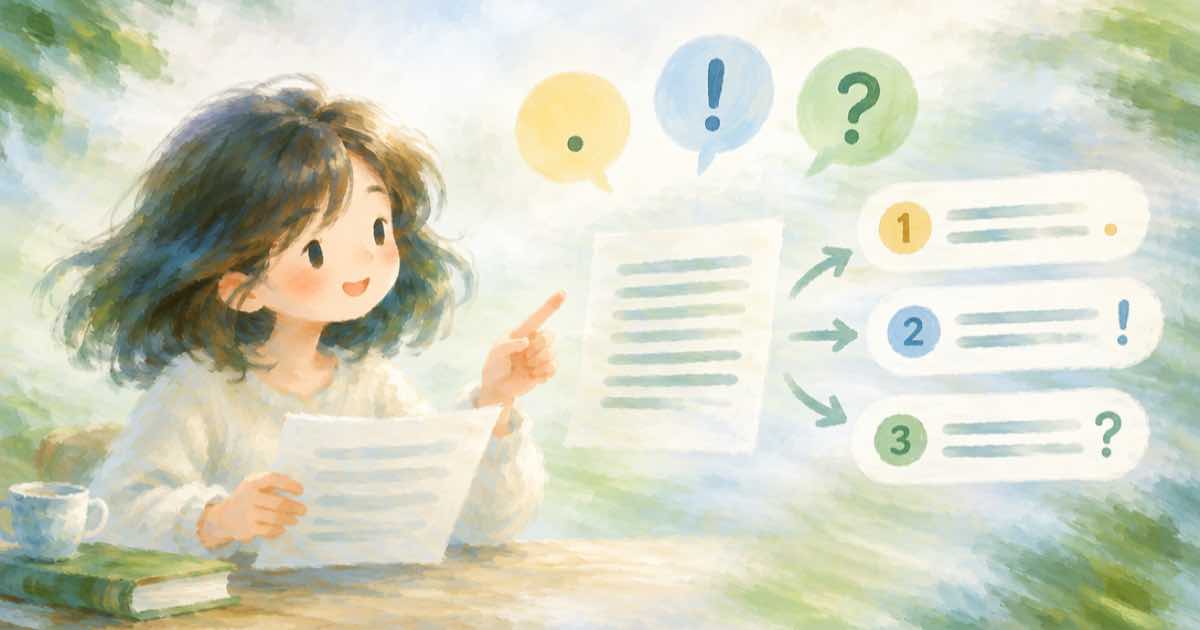
Sume's script-source API splits each accepted script block at three marks: ., ! and ?. Everything up to and including a mark is one sentence, text after the last mark is a final sentence, and nothing is dropped: the pieces joined together must equal the canonical text, or the request fails with 422 tts_sentence_selection_invalid ("Source segmentation must be lossless.").
Each sentence gets an id sent_ plus a six-digit counter that runs across all blocks of the script (sent_000000, sent_000001, ...). The manifest also gives source_block_index, sentence_index within the block and character_count.
What counts as a boundary
| Script text | Result |
|---|---|
| Hello there. Next one. | Two sentences, the space stays with the first one's tail |
| It costs $4.50 today. | Cut at the dot in 4.50: It costs $4. and 50 today. |
| Dr. Lee agreed. | Cut after Dr. |
| Wait... what? | The three dots and the question mark each end a piece; punctuation-only runs are kept, never dropped |
| Line one, no stop\nLine two. | Without a terminal mark the text runs on to the next mark inside the same block |
| Semicolons; colons: commas, | Not boundaries |
Why this matters for narration
A selection must be whole, contiguous sentences, so a bad cut limits what you can regenerate on its own. If a decimal or abbreviation splits a line, either rewrite it (4 dollars 50) or select both halves together. Whitespace-only pieces attach to the previous sentence of the same block.
Before splitting, text is normalized to Unicode NFC with CRLF and lone CR turned into LF. The Python below reproduces the rule so you can preview ids and lengths offline.
import re, unicodedata

def sentences(blocks):
    out = []
    for b, raw in enumerate(blocks):
        text = unicodedata.normalize("NFC", raw)
        text = text.replace("\r\n", "\n").replace("\r", "\n")
        for piece in re.findall(r"[^.!?]*[.!?]|[^.!?]+\Z", text):
            if not piece.strip():
                if out and out[-1][1] == b:
                    out[-1][2] += piece
            else:
                out.append([f"sent_{len(out):06d}", b, piece])
    return out

for sid, b, t in sentences(["Hi there. It costs $4.50! Ready?"]):
    print(sid, b, len(t), repr(t))
What a cut costs
Segmenting is free. Generating costs $0.0475 per 1,000 characters rounded up per job, so a 14-character sentence alone is still $0.01, the one-cent minimum. Group neighboring sentences into one job when you can.
Sources
Related posts
More in Developers
- Huey task that polls an AI video job with schedule(delay=...)
A Huey task reads Sume's job status once and reschedules itself with task.schedule(delay=...) from next_poll_after_seconds, so no worker thread sleeps.
- Idempotency key for transcription: hash the request, avoid 409
Derive the Sume STT Idempotency-Key from a hash of audio_url, language and duration. A retry returns the same job. A changed body under that key is a 409.
- Ideogram 4.5 low to high on one order: new Idempotency-Key or a 409
A reused Idempotency-Key with a different payload returns 409 idempotency_conflict. Key on order id plus a payload hash so a quality change is a new job.
- Keep a series voice consistent: pin model, voice, speed and volume
A series sounds the same only if every episode sends the same TTS settings. Keep one profile in code, pin a model id, and send it with each Sume request.
Written by Sume