HelixWorld spatial audio vs native stereo clips on Sume
HelixWorld renders camera-aligned stereo sound in real time. Sume's video rows give native stereo or synced audio per clip, not live spatial audio. Compare.
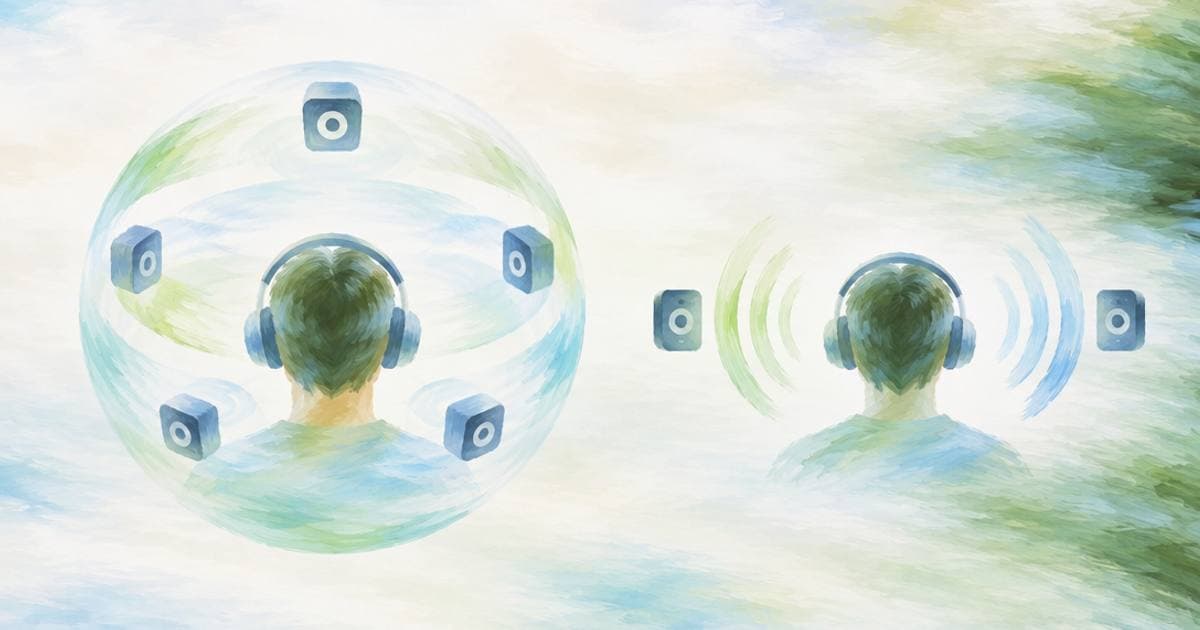
HelixWorld is a research world model whose sound follows the camera as you move, while Sume generates finished clips whose audio is fixed when the clip is rendered. On Sume you can get native stereo or synced audio from several video models, but you cannot walk through a scene and have the sound field turn with you. If you need a pre-rendered clip with a soundtrack, use a video row; if you need live, interactive spatial sound, Sume does not offer that.
What is HelixWorld and what does it claim?
The paper on arXiv describes HelixWorld as a real-time interactive audio-visual world model: visual scenes and camera-grounded spatial stereo sound evolve together as the user interacts. The abstract reports 24 FPS on a single GPU, a streaming student distilled from a bidirectional teacher, and a new benchmark, HelixBench, that checks whether synthesized sound fields track viewpoint motion.
That is a research result, not a Sume feature. Sume does not list HelixWorld, and there is no live session endpoint in the video API.
Which Sume video rows return audio?
The Sume docs describe audio per catalog row. The table below is limited to rows whose audio behavior the Video generation and Video Router pages state in words. Always read the live catalog before building on one, because some rows only appear where a provider is configured.
For gemini-omni-flash-1.1, sending generate_audio set to false is a 400, since the model always produces audio. For minimax-h3 and minimax-h3-max there is no generate_audio toggle at all. In every case the sound is baked into the file at render time: it does not respond to anything after the render, so there is no viewer position for the audio to follow.
| Model id | Audio | Audio reference input |
|---|---|---|
| minimax-h3 | Native stereo, always on, no toggle | Accepted |
| minimax-h3-max | Native stereo, always on, no toggle | Accepted |
| gemini-omni-flash-1.1 | Native synced audio, no toggle | Not accepted |
| seedance-2 | Optional audio via generate_audio | Accepted |
| wan-3.0 | Audio | Accepted |
Can a rendered clip fake camera-aligned sound?
Only by writing it into the prompt and checking the result. A prompt that says the camera pans left past a street musician, with the music fading to the right, may or may not produce a pan in the stereo field. The Sume docs make no promise that a stereo clip's left-right balance tracks camera motion, so treat it as something to listen for on a test clip, not a guarantee.
If the balance matters, a practical route is to generate the picture with one row, then judge the stereo image on headphones before you spend on a full batch.
Two cheap checks help. First, render a short clip with an obvious off-center sound source and listen on headphones for whether the source stays put or moves with the pan. Second, compare two rows on the same prompt, because stereo behavior is a property of the model, not of the prompt wording. Keep the winner's model id in your job notes so a later batch reuses it.
How do I list which rows can generate audio?
The catalog descriptor has a generate_audio field per model, so a short script shows what your account can use today.
import os
import requests


def audio_rows() -> list[str]:
    key = os.environ.get("SUME_API_KEY", "")
    if not key:
        raise SystemExit("Set SUME_API_KEY first")
    resp = requests.get(
        "https://api.sume.com/v1/videos/models",
        headers={"Authorization": f"Bearer {key}"},
        timeout=30,
    )
    resp.raise_for_status()
    models = resp.json().get("data", [])
    return [m["id"] for m in models if m.get("generate_audio")]


if __name__ == "__main__":
    for model_id in audio_rows():
        print(model_id)
When is a world model the wrong tool anyway?
A world model answers one question, what happens next if the viewer moves, and it needs a GPU running during the session. A marketing clip, a product loop, or a social ad needs a fixed file you can trim, caption and publish. For those, a video row plus the timeline tools is the shorter path. See the related posts for what Sume offers in place of a live world.
There is also a cost difference in kind. Sume bills each video job once, at the provider list price times 1.25 on every row, and returns a file. A live world model has no such unit: you pay for the time a session runs, which is why interactive worlds sit outside a per-clip catalog.
Sources
Related posts
More in Models
- Midjourney Rerun (Thinking) is alpha-only: the Sume workaround
Midjourney's Rerun (Thinking) button retries a job that missed the prompt, but only on the alpha site. Here is the nearest retry loop with Sume's image API.
- Nano Banana 2.1, Pro, GPT Image 2.5, Seedream or FLUX.2: 5 checks
Pick between five Sume image rows by elimination: 1:8 ratio, 11+ references, transparent PNG, native 4K, then price from 3.75 to 18.75 cents.
- An OpenRouter-compatible video API: sume/auto or a pinned model
Sume's POST /v1/videos follows OpenRouter's video generation API field for field. Let sume/auto pick the model, or pin a catalog id like seedance-2.5.
- Image generation API with reference images: POST /v1/images
Send a prompt plus public HTTPS reference images to Sume's POST /v1/images. Pin a catalog model or send sume/auto; the catalog lists each model's limits.
Written by Sume