
Griffin-Lite 10 ms audio packets vs Sume's 4 second minimum clip
Two ends of avatar timing: Tavus Griffin-Lite streams audio in packets as small as 10 ms; Sume Avatar 1.0 plans clips of 4 to 12 seconds. What each fits.
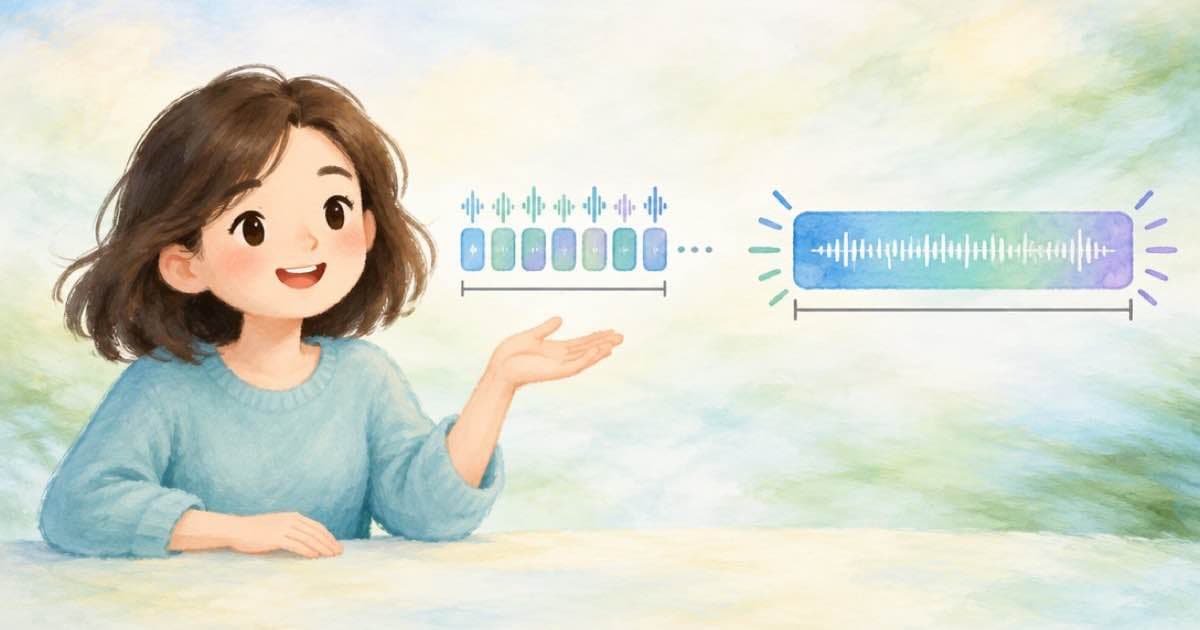
The smallest unit Tavus describes for Griffin-Lite is an audio packet of 10 ms, generated one latent at a time. The smallest unit Sume Avatar 1.0 plans is a 4 second clip, inside a 4 to 60 second job. That gap, about 400 times, is the real difference between a live conversational model and a rendered talking video, and it decides which one you can use this week.
| Item | Tavus Griffin-Lite | Sume Avatar 1.0 talking video |
|---|---|---|
| Smallest audio unit | Packets as small as 10 ms | Whole script, planned into clips |
| Smallest output | One latent at a time, real time | 4 second clip; job window 4 to 60 s |
| Resolution | 720p | 720p |
| Typical wait stated | Average latency 0.43 s (best 0.27, worst 0.59) | Queued, processing, completed job; poll or webhook |
| Availability | Select trusted testers; not available to customers | Public API |
What Tavus says it is built for
The Tavus page describes a model that takes a reference image together with streaming audio and controls, and reports an average latency of 0.43 seconds. It also states that Griffin-Lite is not available to customers at this time and is open to select trusted testers as a research preview. There is nothing to integrate yet unless Tavus has invited you.
Tavus also says it is working on safe disclosure features before wider release, because a model people can mistake for a person needs them. Plan for that on any avatar you ship.
What the Sume timing looks like
A Sume talking-video request is a job. The job states are queued, processing, completed, failed and canceled, and the docs say queued is a normal accepted state. You submit with an Idempotency-Key, poll status or take a signed webhook, then read the result URL. Sync mode only blocks for a bounded wait and may still return a queued or processing job, so do not build a chat loop on it.
The 4 second floor is billed. At the standard tier of $0.184 per second, a 4 second clip is 4 x 0.184 = $0.736. At plus ($0.245) it is $0.98 and at max ($0.55) it is $2.20. The 60 second ceiling is 60 x 0.184 = $11.04 on standard.
Which problem each timing fits
Use a streaming model when a person talks to the avatar and expects it to react within a second. Use a rendered clip when you know the words in advance, want to review them, and want one file that any number of viewers can watch.
If you need both, a common split is a live front door for open questions and a bank of rendered clips for the answers you already know. That second part is something you can build now. The first part waits for access from the vendor.
Planning around the gap
Do not treat the two as competing for the same slot. A live model answers in the moment, so its value is the unplanned part of a conversation. A rendered clip is planned, so its value is control and reuse. Write down which parts of your flow are predictable, such as the greeting, the plan explanation and the next-step instruction, and which are not. Render the first group on Sume and leave the second to a person or a live product you have access to.
Also keep expectations on cost visibility. Sume publishes per-second rates, so you can compute a budget before any call. The Tavus page we read does not state a price, so a live comparison cannot be done on cost today.
Sources
Related posts
More in Comparisons
- Griffin-Lite inputs vs a Sume talking-video request, side by side
Tavus describes a reference image plus streaming audio and controls; Sume takes an avatar handle, a script and a tier. The two request shapes compared.
- Haiku 5.5 vs Sonnet 5.5 token prices for an agent calling Sume
Haiku 5.5 costs $0.10 per million input tokens and Sonnet 5.5 costs $2. What the gap does and does not change for a Sume agent's spend cap.
- HappyHorse 1.1 is 12th at 1,042 Elo: what ranks above it on Sume
HappyHorse-1.1 is 12th on the AA text-to-video board at $10.80 a minute. Sume does not list it; six Sume models rank above it. Per-minute prices inside.
- HappyScribe $0.20 a minute vs a $0.20 Sume caption job
HappyScribe tops up AI minutes at $0.20 each. Sume burns captions into a clip of up to 60 seconds for $0.20 flat. Where each wins.
Written by Sume