
Face swap beta: motion stage runs on Kling, source audio muxed back
Sume's Avatar Face Swap beta runs its motion stage on the Kling 3.0 motion control queue, strips the source audio, then muxes the original audio back in.
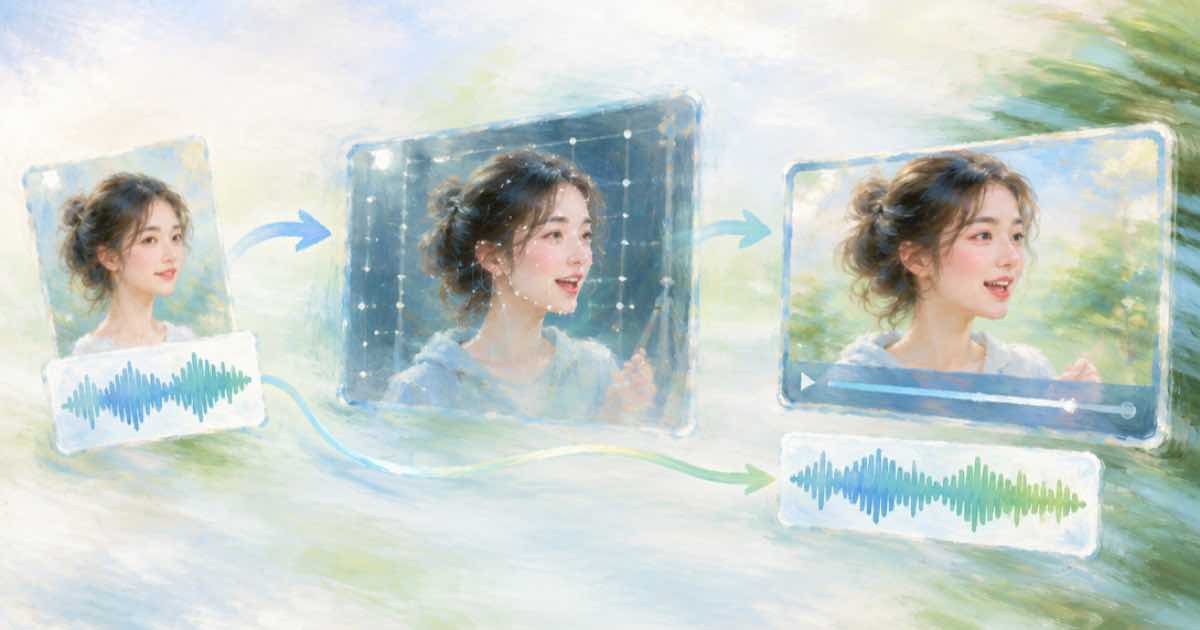
Sume's Avatar Face Swap beta does its motion step on the same Kling 3.0 Standard motion control queue that the public motion control route uses. The swapped first frame is the character, the source video (with its audio removed) is the motion, and the finalize stage muxes the original audio back in. So the sound in your result is the sound of your source, not something the provider made.
The stages in plain words
A face swap job is a small pipeline, and the motion step is one stage of it. The pipeline swaps the face on the first frame of your video, then uses that frame as the still for a Kling motion pass that follows the movement of the source clip, then joins the original audio to the result.
The audio is taken out for the motion stage because the motion model is not asked to produce a soundtrack for a swap. The source audio is the truth, and the finalize stage puts it back so that lip movement, music and room tone stay as they were.
What that means for a buyer
Three practical points follow.
- Length and cost are tied to the source clip, as they are for any motion pass. The beta accepts short clips, so read the current limits on the face swap page before you plan a batch.
- The soundtrack of the output is your own. If the source has music that you do not have rights to, the swapped clip has it too.
- Because it shares the queue, a busy motion control backlog can slow a face swap, and the reverse is also true. Plan concurrency across both.
Face swap and motion control side by side
| Item | Face swap beta | Motion control route |
|---|---|---|
| Provider queue | Kling 3.0 Standard motion control | Kling 3.0 Standard motion control |
| Character still | swapped first frame of your video | image_url or avatar you send |
| Motion source | your video, audio removed | motion_video_url you send |
| Audio in result | original source audio, muxed back | keep_original_sound (default true) |
| How you call it | face swap beta endpoint | POST /v1/kling/3.0/motion-control |
When to call which
Call the face swap beta when your input is a finished video and you want the person in it replaced by a Sume avatar. You hand over one video and one avatar, and the pipeline handles the first frame and the motion.
Call motion control directly when you already hold a still and a performance clip, and you control both. You get the length, the sound switch and the orientation setting yourself, and a clean price of $0.1575 a second.
Both end in a normal Sume job, so the completion path is the same. Use a webhook instead of a poll loop, verify the signature, and then fetch the result. The face swap webhook post covers the event name and the headers for that case.
Related posts
More in Sume Avatar 1.0
- Full-duplex avatar listens while it speaks: script a clip instead
A full-duplex avatar hears you mid-sentence. If your content is scripted, build similar beats into one Sume avatar clip with silence scenes. Curl included.
- Full-duplex or script-driven avatar: six questions before you pick
Tavus Griffin-Lite is a full-duplex video conversation model in research preview. Six questions that separate it from Sume Avatar 1.0 talking video.
- Holiday ad captions on Avatar 1.0: slam, punch or tiktok-green?
Avatar 1.0 burns captions inline in slam (default), punch or tiktok-green. No separate billed caption job, and a caption failure keeps the clean video.
- Map avatar video scene ids to onboarding steps with scene_previews
Give each video_inputs scene a stable id and Sume returns it in scene_previews with start, end and duration, so one clip can drive per-step chapters.
Written by Sume